
e-Literate

Present is Prologue

Tag: learning engineer

  • Learning Engineering: A Caliper Example

    Learning Engineering: A Caliper Example

    In my recent IMS update post, I wrote,

    [T]he nature and challenges of interoperability our sector will be facing in the next decade are fundamentally different from the ones that we faced in the last one. Up until now, we have primarily been concerned with synchronizing administration-related bits across applications. Which people are in this class? Are they students or instructors? What grades did they get on which assignments? And how much does each assignment count toward the final course grade? These challenges are hard in all the ways that are familiar to anyone who works on any sort of generic data interoperability questions. 
    But the next decade is is going to be about data interoperability as it pertains to insight. Data scientists think this is still familiar territory and are excited because it keeps them at the frontier of their own profession. But this will not be generic data science, for several reasons.

    I then asserted the following positions:

    • Because learning processes are not directly observable, blindly running machine learning algorithms against the click streams in our learning platforms will probably not teach us much about learning.
    • On the other hand, if our analytics are theory-driven, i.e., if we start with some empirically grounded hypotheses about learning processes and design our analytics to search for data that either support or disprove those hypotheses, then we might actually get somewhere.
    • Because learning analytics expressions written in the IMS Caliper standard can be readily translated into plain English, Caliper could form a basis for expressing educational hypotheses and translating them into interoperable tools for testing those hypotheses across the boundaries of tech tools and platforms.
    • The kind of Caliper-mediated conversation I imagined among learning scientists, practicing educators, data scientists, learning system designers, and others, is relevant to a term coined and still used heavily at Carnegie Mellon University—”learning engineering.”

    In this post, I’m going to explore the last two points in more detail.

    What the heck is “learning engineering”?

    The term “learning engineering” was first used by Nobel laureate and Carnegie Mellon University polymath Herbert Simon in 1966. It has been around for quite a while. But it is a term whose time as finally has come and, as such, we are seeing the usual academic turf wars over its meaning and value. On the one hand, some folks love it, embrace it, and want to apply it liberally. IEEE has an entire group devoted to defining it. As is always the case, some of this sort of enthusiasm is thoughtful, and some of it is less so. At its worst, there is a tendency for people to get tangled up in the term because it provides a certain je ne sais quoi they’ve been yearning for to describe the aspects of their jobs that they really want to be doing as change agents rather than the mundane tasks that they keep being dragged back into doing, much like the way some folks are wrapping “innovation” and “design” around themselves like a warm blanket. It’s perfectly understandable, and I think it attaches to something real in many cases, but it’s hard to say exactly what that is. And, of course, where there are enthusiasts in academia, there are critics. Again, some thoughtful, while others…less so. (Note my comment in the thread on that particularly egregious column.)

    If you want to get a clear sense of the range of possible meanings of “learning engineering” as used by people who actually think about it deeply, one good place to start would be Learning Engineering for Online Education: Theoretical Contexts and Design-Based Examples edited by Chris Dede, John Richards, and Bror Saxberg. (I am still working on getting half a day’s worth of Carnegie Mellon University video presentations on their own learning engineering work ready for posting on the web. I promise it is coming.) There are a lot of great take-aways from that anthology, one of which is that even the people who think hard about the term and work together to put together something like a coherent tome on the subject don’t fully agree on what the term means.

    And that’s really OK. Let’s just set a few boundary conditions. On the one hand, learning engineering isn’t an all-encompassing discipline and methodology that is going to make all previous roles, disciplines, and methodologies obsolete. If you are an instructional designer, or a learning designer, or a user experience designer; if you practice design thinking, or ADDIE; be not afraid. On the other hand, learning engineering is not creeping Stalinism either. Think about learning engineering, writ large, as applying data and cognitive sciences to help bring about desired learning outcomes, usually within the context of a team of colleagues with different skills all working together. That’s still pretty vague, but it’s specific enough for the current cultural moment.

    Forget about your stereotypes of engineers and their practices. Do you believe there is a place for applied science in our efforts to improve the ways in which we design and deliver our courses, or try to understand and serve our students needs and goals? If so, what would such an applied science look like? What would a person applying the science need to know? What would their role be? How would they work with other educators who have complementary expertise?

    That is the possibility space that learning engineering inhabits.

    Applied science as a design exercise

    One of the reasons that people have trouble wrapping their heads around the notion of learning engineering is that it was conceived of by very unusual mind. Some of the critiques I’ve seen online of the term position “learning engineering” in opposition to “learning design.” But as Phil Long points out in his essay in the aforementioned anthology, Herb Simon both coined the term “learning engineering” and is essentially the grandfather of design thinking:

    Design science was introduced by Buckminster Fuller in 1963, but it was Herbert Simon who is most closely associated with it and has established how we think of it today. “The Sciences of the Artificial” (Simon, 1967) distinguished the artificial, or practical sciences, from the natural sciences. Simon described design as an ill-structured problem, much like the learning environment, which involves man-made responses to the world. Design science is influenced by the limitations of human cognition unlike mathematical models. Human decision-making is further constrained by practical attributes of limited time and available information. This bounded rationality makes us prone to seek adequate as opposed to optimal solutions to problems. That is, we engage in satisficing not optimizing. Design is central to the artificial sciences: ‘Everyone designs who devises courses of action aimed at changing existing situations into desired ones.’ Natural sciences are concerned with understanding what is; design science instead asks about what should be. this distinction separates the study of the science of learning from the design of learning. Learning scientists are interested in how humans learn. Learning engineers are part of team focused on how students ought to learn.”

    Phil Long, “The Role of the Learning Engineer”

    Phil points out two important dichotomies in Simon’s thinking. The first one: is vs. ought. Natural science is about what is, while design science is about what you would like to exist. What you want to bring into being. The second dichotomy is about well structured vs. poorly structured. For Simon, “design” is a set of activities one undertakes to solve a poorly structured problem. To need or want is human, and to be human is to be messy. Understanding a human need is about understanding a messy problem. Understanding how different humans with different backgrounds and different cognitive and non-cognitive abilities learn, given a wide range of contextual variables like the teaching strategies being employed, the personal relationships between students and teacher, what else is going on in the students’ lives at the time, whether different students are coming to class well fed and well slept, and so on, is pretty much the definition of a poorly structured problem. So as far as Herb Simon is concerned, education is a design problem by definition, whether or not you choose to use the word “engineer.”

    In the next section of his article, Phil then makes a fascinating connection between the evolution of design thinking, which emerged out design science, and learning engineering. The key is in identifying the central social activity that defines design thinking:

    Design thinking represents those processes that designers use to create new designs, possible approaches to problem solutions spaces where none existed before. A problem-solving method has been derived from this and applied to human social interactions iteratively taking the designer and/or co-design participants from inspiration to ideation and then to implementation. The designer and design team may have a mental model of the solution to a proposed problem, but it is essential to externalize this representation in terms of a sketch a description of a learning design sequence, or by actual prototyping of the activities which the learner is asked to engage. [Emphasis added.] All involved can see the attributes of the proposed design solution that were not apparent in the conceptualization of it. this process of externalizing and prototyping design solutions allows it to be situated in larger and different contexts, what Donald Schon called reframing the design, situating it in contexts other than originally considered.

    Phil Long, “The Role of the Learning Engineer”

    So the essential feature that Phil is calling out in design thinking is putting the idea out into the world so that everybody can see it, respond to it, and talk about it together. Now watch where he takes this:

    As learning environments are intentionally designed in digital contexts, the opportunity to instrument the learning environment emerges. Learners benefit in terms of feedback or suggested possible actions. Evaluators can assess how the course performed on a number of dimensions. The faculty and others in the learning-design team can get data through the instrumented learning behaviors, which may provide insight into how the design is working, for whom it is working, and in what context.

    Phil Long, “The Role of the Learning Engineer”

    Rather than a sketch, a wireframe, or a prototype, a learning engineer makes the graph, the dashboard, or the visualization into the externalization. For Herb Simon, as for Phil Long, these design artifacts serve the same purpose. They’re the same thing, basically.

    If you’re not a data person, this might be hard to grasp. (I’m not a data person. This is hard for me to grasp sometimes.) How can you take numbers in a table and turn them into a meaningful artifact that a group of people can look at together, discuss, make sense of, debate, and learn from? What might that even look like?

    Well, it might look something like this, for example:
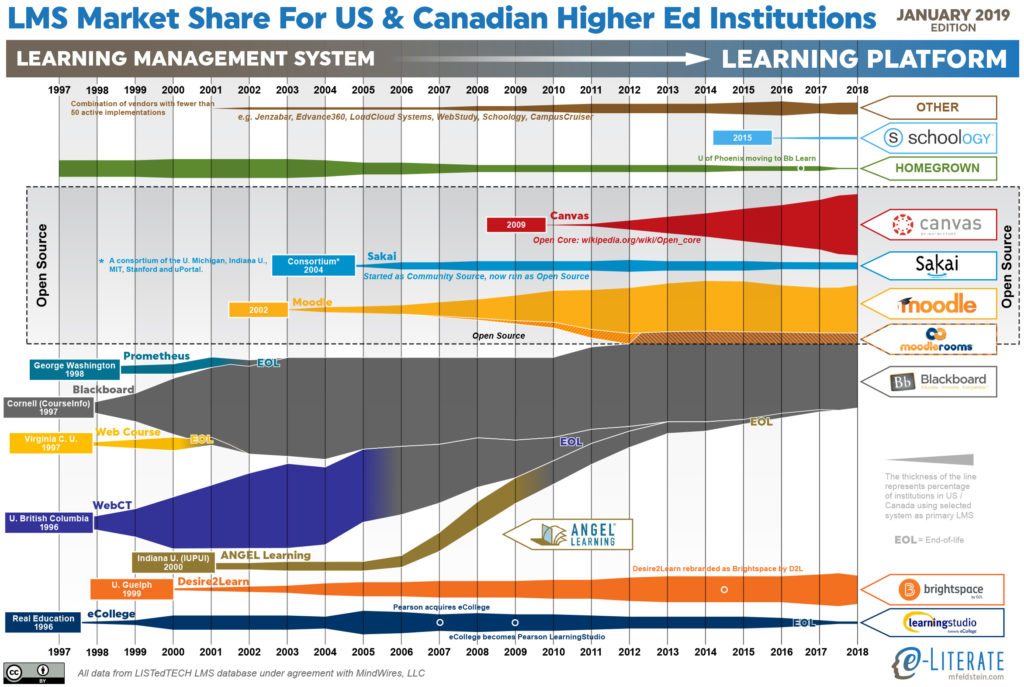
    Higher ed LMS market share for US and Canada, January 2019
    Phil Hill’s famous squid diagram

    Phil Hill has a graduate degree in engineering. Not learning engineering. Electrical. (Also, he’s not a Stalinist.)

    By the way, when we externalize and share data with a student about her learning processes in a form that is designed to provoke thought and discussion, we have a particular term of art for that in education. It’s called “formative assessment.” If we do it in a way such that the student always has access to such externalizations, which are continually updating based on the student’s actions, we call that “continuous formative assessment.” When executed well, there is evidence that it can be an effective educational practice.

    Caliper statements as learning engineering artifacts

    So here’s where we’ve arrived at this point in the post:

    • Design is a process by which we tackle ill-defined problems of meeting human needs and wants, such as needing or wanting to learn something.
    • Engineering is a word that we’re not going to worry about defining precisely for now, but it relates to applying science to a design problem, and therefore often involves the measurement and numbers.
    • One important innovation in design methodology is the creation of external artifacts early in the design process so that various stakeholders with different sorts of experience and expertise can provide feedback in a social context. In other words, create something that makes the idea more “real” and therefore easier to discuss.
    • Learning engineering includes the skills of creation and manipulation of design artifacts that require more technical expertise, including expertise in data and software engineering.

    The twist with Caliper is that, rather than using visualizations and dashboards as the externalization, we can use human language. This was the original idea of behind the Semantic Web, which is still brilliant in concept, even if the original implementation was flawed. Let’s review that basic idea as implemented in Caliper:

    • You can express statements about the world (or the world-wide web) in three-word sentences of the form [subject] [verb] [direct object] e.g., [student A] [correctly answers] .
    • Because English grammar works the way it does, you can string these sentences together to form inferences, e.g., [tests knowledge of] [multiplying fractions]; therefore, [student A] [correctly answers] [a question about multiplying fractions].
    • We can define mandatory and optional details of every noun and verb e.g., it might be mandatory to know that question 13 was a multiple choice question, but it might be optional to include the actual text of the question, the correct answer, and the distractors.

    That’s it. Three-word sentences, which work the way they do in English grammar, and definitions of the “words.”

    A learning engineer could use Caliper paragraphs as a design artifact to facilitate conversations about refining the standard, the products involved, and the experimental design. I’ll share a modified version of an example I recently shared with an IMS engineer to illustrate this same point.

    Suppose you are interested in helping students become better at reflective writing. You want to do this by providing them with continuous formative assessment, i.e., in addition to the feedback that you give them as an instructor, you want to provide them an externalization of the language in their reflective writing assignments. You want to use textual analysis to help the students look at their own writing through a new lens, find the spots where they are really doing serious thought work, and also the spots where maybe they could think a little harder.

    But you have to solve a few problems in order to do give this affordance to your students. First, you have to develop the natural language analysis tool that can detect cues in the students’ writing that indicate self-reflection (or not). That’s hard enough, but the research is being conducted and progress is being made. The second problem is that you are designing a new experiment to test your latest iteration and need some sort of summative measure to test against. So maybe you design a randomized controlled trial where half the students in the class use the new feedback tool, half don’t, and all get the same human-graded final reflective writing assignment. You compare the results.

    This is an example of theory-driven learning analytics. Your theory is that student reflection improves when students become more aware of certain types of reflective language in their journaling. You think you can train a textual analysis algorithm to reliably distinguish—externalize—the kind of language that you want students to be more aware of in their writing and point it out to them. You want to test that by giving students such a tool and see if their reflective writing does, in fact, improve. Either students’ reflective writing will improve under the test condition, which will provide supporting evidence for the theory, or it won’t, which at the very least will not support the theory and might provide evidence that tends to disprove the theory, depending on the specifics. There are data science and machine learning being employed here, but they are being employed more selectively than just shotgunning an algorithm at a data set and expecting it to come up with novel insights about the mysteries of human cognition.

    Constructing theory-driven learning analytics of the sort described here is challenging enough to do in a unified system that is designed for the experiment. But now we get to the problem for which we will need the help of IMS over the next decade, which is that the various activities we need to monitor for this work often happen in different applications. Each writing assignment is in response to a reading. So the first thing you might want to do, at least for the experiment if not in the production application, is to control for students who do the reading. If they aren’t doing the reading, then their reflective writing on that reading isn’t going to tell you much. Let’s say the reading happens to take place in an ebook app. But their writing takes place in a separate notebook app. Maybe it’s whatever notebook app they normally use—Evernote, One Note, etc. Ideally, you would want them to journal in whatever they normally use for that sort of activity. And if it’s reflective writing for their own growth, it should be an app that they own and that will travel with them after they leave the class and the institution. On the other hand, the final writing assignment needs to be submittable, gradable, and maybe markable. So maybe it gets submitted through an LMS, or maybe through a specialized tool like Turnitin.

    This is an interoperability problem. But it’s a special one, because the semantics have to be preserved through all of these connections in order for (a) the researchers to conduct the study, and then (b) the formative assessment tool to have real value to the students. The people who normally write Caliper metric profiles—the technical definitions of the nouns in Caliper—would have no idea about any of this on their own. Nor would the application developers. Both groups would need to have a conversation with the researchers in order to get the clarity they need in order to define the profiles for this purpose.

    The language of Caliper could help with this if a person with the right role and expertise were facilitating the conversation. That person would start by eliciting a set of three-word sentences from the researchers. What do you need to know? The answers might include statements like the following:

    • Student A reads text 1
    • Student A writes text alpha
    • Text alpha is a learning reflection of text 1
    • Student A reads text 2
    • Text 2 is a learning reflection of texts 1 and 2
    • Etc.

    The person asking the questions of the researcher and the feature designer—let’s call that person the learning engineer—would then ask questions about the meanings and details of the words, such as the following:

    • In what system or systems is the reading activity happening?
    • Do you need to know if the student started the reading? Finished it? Anything finer grained than that?
    • What do you need to know about the student’s writing in order to perform your textual analysis? What data and metadata do you need? And how long a writing sample do you need to elicit in order to perform the kind of textual analysis you intend and get worthwhile results back?
    • What do you mean when you say that text 2 is a reflection of both text 1 and 2, and how would you make that determination?

    At some point, the data scientist and software systems engineers would join in the conversation and different concerns would start to come up, such as the following:

    • Right now, I have no way of associating Student A in the note-taking system with Student A in the reading system.
    • To do the analysis you want, you need the full text of the reflection. That’s not currently in the spec, and it has performance implications. We should discuss this.
    • The student data privacy implications are very different for an IRB-approved research study, an individual student dashboard, and an instructor- or administrator-facing dashboard. Who owns these privacy concerns and how do we expect them to be handled?

    Notice that the Caliper language has become the externalization that we manipulate socially in the design exercise. There are two aspects of Caliper that make this work: (1) the three-word sentences are linguistically generative, i.e., they can express new ideas that have never been expressed before, and (2) every human-readable expression directly maps to a machine-readable expression. These two properties together enable rich conversations among very different kinds of stakeholders to map out theory-driven analytics and the interoperability requirements that they entail.

    This is the kind of conversation by which Caliper can evolve into a standard that leads to useful insights and tools for improving learning impact. And in the early days, it will likely happen one use case at a time. Over time, the working group would learn from having enough of these conversations that design patterns would emerge, both for writing new portions of the specification itself and for the process by which the specification is modified and extended.
    Copyright Carnegie Mellon University, CC-BY
  • The IMS at an Inflection Point

    The IMS at an Inflection Point

    A few weeks back, I had the pleasure of attending the IMS Learning Impact Leadership Institute (LILI). For those of you who aren’t familiar with it, IMS is the major learning application technical interoperability organization for higher education and K12 (and is making some forays into the corporate training and development world as well). They’re behind specifications like LIS, which lets your registrar software automagically populate your LMS course shell with students, and LTI, which lets you plug in many different learning applications. (I’ll have a lot more to say about LTI later in this post.)

    While you may not pay much attention to them if you aren’t a technical person, they have been and will continue to be vital to creating the kind of infrastructure necessary to support more and better teaching and learning affordances in our educational technology. As I’ll describe in this post, I think the nature of that role is likely to evolve somewhat as the interoperability needs of the sector are beginning to evolve.

    The IMS is very healthy

    I’m happy to report that the IMS appears to be thriving by any obvious measure. The conference was well attended. It attracted a remarkably diverse group of people for an event hosted by an organization that could easily be perceived as techie-only. Furthermore, the attendees seemed very engaged and the discussions were lively.

    On more objective measures, the organization’s annual report bears out this impression of strong engagement. They have strong international representation across a range of organization types.

    From the IMS Global 2018 Annual Report

    Whether your measure is membership, product certifications, or financial health, the IMS is setting records.

    From the IMS Global 2018 Annual Report

    This state of affairs is even more remarkable given that, 13 years ago, there was some question as to whether the IMS was financially sustainable.

    From the IMS Global 2018 Annual Report

    If you look carefully at this graph, you’ll see three distinct periods of improvement: 2005-2008, 2009-2013, and 2013-2018. Based on what I know about the state of the organization at the time, first period can most plausibly be attributed to immediate changes implemented by Rob Abel, who took over the reins of the organization in February of 2006 and likely saved it from extinction. Likewise, the magnitude of growth in the second period is consistent with that of a healthy membership organization that has been put back on track.

    But that third period is different. That’s not normal growth. That’s hockey stick growth.

    I am not a San Franciscan. By and large, I do not believe in heroic entrepreneur geniuses who change the world through sheer force of will. Whenever I see that kind of an upward trend, I look for a systemic change that enabled a leader or organization—through insight, luck, or both—to catch an updraft.

    There is no doubt in my mind that the IMS has capitalized on some major updrafts over the last decade. That is an observation, not a criticism. That said, the winds are changing, in part because the IMS has helped move the sector through an important period of evolution and is now helping to usher in the next one. That will raise some new challenges that the IMS is certainly healthy enough to take on but will likely require them to develop a few new tricks.

    The world of 2005

    In the first year of the chart above, when the IMS was in danger of dying, there was very little in the way ed tech to interoperate. There were LMSs and registrar systems (a.k.a. SISs). Those were the two main systems that had to talk to each other. And they did, after a fashion. There was an IMS standard at the time, but it wasn’t a very good one. The result was that, even with the standard, there was a person in each college or university IT department whose job it was to manage the integration process, keep it running, fix it when it broke, and so on. This was not an occasional tweak, but a continual effort that ran from the first day of class registration through the last day of add/drop. If you picture an old-timey railroad engineer shoveling coal into the engine to keep it running and checking the pressure gauge every ten minutes to make sure it didn’t blow up, you wouldn’t be too far off. As for reporting final grades from the LMS’s electronic grade book automatically to the SIS’s electronic final grade record, well, forget it.

    If you ignore some of the older content-oriented specifications, like QTI for test questions and Common Cartridge for importing static course content, then that was pretty much it in terms of application-to-application interoperability. Once you were inside the LMS, it was basically a bare-bones box with not much you could add. Today, the IMS lists 276 officially certified products that one can plug into any LMS (or other LTI-compliant consumer), from Academic ASAP to Xinics Commons. I am certain that is a substantial undercount of the number of LTI-compatible applications, since not all compatible product makers get officially certified. In 2005, there were zero, because LTI didn’t exist. There were LMS-specific extensions. Blackboard, for example, had Building Blocks. But with a few exceptions, most weren’t very elaborate or interesting.

    My personal experience at the time was working at SUNY Systems Administration and running a search committee for an LMS that could be centrally hosted—preferably on a single instance—and potentially support all 64 campuses. For those who aren’t familiar with it, SUNY is a highly diverse system, with everything from rural (and urban) community colleges to R1s to everything in between, with some specialty schools thrown into the mix like the Fashion Institute of Technology, a medical school or two, an ophthalmology school, and so on. Both the pedagogical needs and the on-campus support capabilities across the system were (and presumably still are) incredibly diverse. There simply was not any existing LMS at the time, with or without proprietary extensions, that could meet such a diverse set of needs across the system. We saw no signs that this state of affairs was changing at pace that was visible to the naked eye, and relatively few signs that it was even widely recognized as a problem.

    To be honest, I came to the realization of the need fairly slowly myself, one conversation at a time. A couple of art history professors dragged me excitedly to Columbia University to see an open source image annotation tool, only to be disappointed when they discovered that the tool was developed to teach clinical histology, which uses image annotation to teach in an entirely different way than is typically employed in art history classes. An astronomy professor at a community college on the far tip of Long Island, where there was relatively little light pollution, wanted to give every astronomy student in SUNY remote access to his telescope if only we could figure out how to get it to talk to the LMS. Anyone who has either taught a been an instructional designer for a few wildly different subjects has a leg up on this insight (and I had done both), but even so, there are levels of understanding. The art history/histology thing definitely took me by surprise.

    A colleague and I, in an effort to raise awareness about the problem, wrote an article about the need for “tinkerable” learning environments in eLearn Magazine. But there were very few models at the time, even in the consumer world. The first iPhone wasn’t released until 2007. The first practically usable iPhone wasn’t released until 2008. (And we now know that even Steve Jobs was secretly skeptical that apps on a phone were a good idea.) It is a sign of just how impoverished our world of examples was in January of 2006 that the best we could think of to show what a world of learning apps could be like was Google Maps:

    There are several different ways that software can be designed for extensibility. One of the most common is for developers to provide a set of application programming interfaces, or APIs, which other developers can use to hook into their own software. For example, Blackboard provides a set of APIs for building extensions that they call “Building Blocks.” The company lists about 70 such blocks that have been developed for Blackboard 6 over the several years that the product version has been in existence. That sounds like a lot, doesn’t it? On the other hand, in the first five months after Google made the APIs available for Google Maps, at least ten times that many extensions have been created for the new tool. Google doesn’t formally track the number of extensions that people create using their APIs, but Mike Pegg, author of the Google Maps Mania weblog, estimates that 800-900 English-language extensions, or “mash-ups,” with a “usable, polished Google Maps implementation” have been developed during that time—with a growth rate continuing at about 1,000 new applications being developed every six months. According to Pegg, “There are about five sites out there that facilitate users to create a map by taking out an account. These sites include wayfaring.comcommunitywalk.commapbuilder.net—each of these sites probably has hundreds of maps for which just one key has been registered at Google.” (Google requires people who are extending their application to register for free software “keys.” Perhaps for this reason, Chris DiBona, Google’s own Open Source Program Manager, has heard estimates that are much higher. “I’ve seen speculation that there are hundreds or thousands,” says DiBona, noting that estimates can vary widely depending on how you count.

    Nevertheless, even the most conservative estimate of Google Maps mash-ups is higher than the total number of extensions that exist for any mainstream LMS by an order of magnitude.

    There seemed little hope for this kind of growth any time in the foreseeable future. By early 2007, having failed to convince SUNY to use its institutional weight to push interoperability forward, I had a new job working at Oracle and was representing them on a specification development committee at the IMS. It was hard, which I didn’t mind, but it was also depressing. There was little incentive for the small number of LMS and SIS vendors who dominated specification development at that time to do anything ambitious. To the contrary, the market was so anemic that the dominant vendors had every reason to maintain their dominance by resisting interoperability. Every step forward represented an internal battle within those companies between the obvious benefit of a competitive moat and the less obvious enlightened self-interest of doing something good for customers. This is simply not the kind of environment in which interoperability standards grow and thrive.

    And yet, despite the fact that it certainly didn’t feel like it, change was in the air.

    Glaciers are slow, but they reshape the planet

    For starters, there was the LMS, which was both a change agent in of itself and an indicator of deeper changes in the institutions that were adopting them. EDUCAUSE data shows that the US LMS market became saturated some time roughly around 2003. At that time, Blackboard and WebCT had the major leads as #1 and #2, respectively. The dynamic for the next 10 years was a seesaw, with new competitors rising and Blackboard buying and killing them off as fast as it could. Take a look at the period between 2003 and 2013 in Phil’s squid graph: ((By the way, if you haven’t subscribed to Phil’s new blog yet, then you really, really should. Like, right now. I’ll wait.))

    It was absolutely vicious.

    None of this would materially affect the standards making process inside the IMS until, first, Blackboard’s practice of continually buying up market share eventually failed (thus allowing an actual market with actual market pressures to form) and, second, until the management team that came up with this decidedly anti-competitive strategy…er…chose to spend more time with their respective families. (I’ll have more to say about Heckle and Jeckle and their lasting impact on market perceptions in a future post.)

    But the important dynamic during this period is that customers kept trying to leave Blackboard (even if they found themselves being reacquired shortly thereafter) and other companies kept trying to provide better alternatives. So even though we didn’t have a functioning, competitive market that could incentivize interoperability, and even though it certainly didn’t feel like we had one, some of the preconditions for one were being established.

    Meanwhile online education growth was being driven by no fewer than three different vectors. First, for-profit providers were hitting their stride. By 2005, the University of Phoenix alone was at over 400,000 enrollments. Second, public access-oriented institutions, many of which had been seeded a decade earlier with grants from the Sloane Foundation, were starting to show impressive growth as well. A couple were getting particular attention. UMUC, for example, may not have had over 400,000 online enrollments in 2005, but they had well over 40,000, which is enough to get the attention of anyone in charge of an access-oriented public university’s budget. More quietly, many smaller schools were having online success that were proportional to their sizes and missions. For example, when I arrived at SUNY in 2005, they had a handful of community colleges that had self-sustaining online degree programs that supported both the missions and the budget of the campuses. Many more were offering individual courses and partial degrees in order to increase access for students. (Most of New York is rural, after all.)

    The third driver of online education, which is more tightly intertwined with the first two than most people realize, is that Online Program Management companies (OPMs) were taking off. The early pioneers, like Deltak (now Wiley Education Services), Embanet, Compass Education (now both subsumed into Pearson), and Orbis (recently acquired by Grand Canyon University) had proved out the model. The second wave was coming. Academic Partnerships and 2Tor (now 2U) were both founded in 2008. Altius Education came in 2009. In 2010, Learning House (now also owned by Wiley) was founded.

    Counting online enrollments is a notoriously slippery business, but this chart from the Babson survey is highly suggestive and accurate enough for our purpose:

    If you’re a campus leader and thirty percent of your students are taking at least one online class, that becomes hard for you to ignore. Uptime becomes far more important. Quality of user experience becomes far more important. Educational affordances become far more important. Obviously, thirty percent is an average, and one that is highly unevenly distributed across segments. But it’s significant enough to be market-changing.

    And the market did change. In a number of ways, the biggest one being that it became an actual, functioning market (or at least as close to one as we’ve gotten in this space).

    When glaciers recede

    Let’s revisit that second growth period in the IMS graph—2008 to 2013—and talk about what was happening in the world during that period. For starters, online continued its rocket ride. The for-profits peaked in 2010 at roughly 2 million enrollments (before beginning their spectacular downward spiral shortly thereafter). Not-for-profits (and odd mostly-not hybrids) ramped up the competition. ASU launched its first online 4-year degree in 2006. SNHU started a new online unit in 2009. WGU expanded into Indiana in 2010, which was the same year that Embanet merged with Compass Knowledge and was promptly bought by Pearson. (Wiley acquired Deltak two years later.)

    Once again, the more online students you have, the less you are able to tolerate downtime, a poor user interface that drives down productivity, or generic course shells that make it hard to teach students what they need to learn in the ways in which they need to learn. Instructure was founded in 2008. They emphasized a few distinctions from their competitors out of the gate. The first was their native multitentant cloud architecture. Reduced downtime? Check. The second was a strong emphasis on usability. The big feature that they touted which was their early runaway hit was Speed Grader. Increased productivity? Check.

    Instructure had found their updraft to give them their hockey stick growth.

    But they also emphasized that they were going to be a learning platform. They weren’t going to build out every tool imaginable. Instead, they were going build a platform and encourage others to build the specialized the tools that teachers and students need. And they would aggressively encourage the development and usage of standards to do so. On the one hand, this fit from a cultural perspective. Instructure was more like a Silicon Valley company than its competitors, and platforms were hot in the Valley. On the other hand, it was still a little weird for the education space. There still weren’t good interoperability standards for what they wanted to do. There still hadn’t been an explosion of good learning tools. This is one of those situations where it’s hard to tell how much of their success was prescience and how much of it was luck that higher ed caught up with their cultural inclination at that exact moment.

    Co-evolution

    The very same year that Brian Whitmer and Devlin Daley founded Instructure, Chuck Severence and Mark Alier were mentoring Jordi Piguillem on a Google Summer of Code project that would become the initial implementation of LTI. In 2010, the same year that Instructure scored its first major win with the Utah Education Network, IMS Global released the final specification for LTI v1.0. All this time that the market had felt like it had been standing still, it had actually been iterating. We just hadn’t been experiencing the benefits of it. Chuck, who had been thinking about interoperability in part through his work on Sakai, had been tinkering. Students like Brian and Devlin, who had been frustrated with their LMS, had been tinkering. The IMS, which actually had a precursor specification before LTI, had been tinkering. While conditions hadn’t become visible on the surface of the glacier, way down, a mile below, the topology of the land was changing.

    Meanwhile in Arizona, in 2009, the very first ASU+GSV summit was held. I admit that I have had writer’s block regarding this particular conference the last few years. It has gotten so big that it’s hard to know how to think about it, much less how to sum it up. In 2009, it was an idea. What if a university and a company that facilitates start-ups (in multiple ways) got together to encourage ed tech companies to work more effectively with universities? That’s my retrospective interpretation of the original vision. I wasn’t at many of those early conferences and I certainly wasn’t an insider. It was hard for me, with my particular background, to know what to make of it then and even harder now.

    But something clicked for me this year when it turned out that IMS LILI was held at the same hotel that the ASU+GSV summit had been at a couple of months earlier. How does the IMS get to 523 product certifications and $8 million in the bank? A lot of things have to go right for that to happen, but for starters, there have to be 523 products to certify and lots of companies that can afford to pay certification fees. That economy simply did not exist in 2008. Without it, there would be no updraft to ride and consequently no hockey stick growth. ASU+GSV’s phenomenal growth, and the ecosystem that it enabled, was another major factor influenced what I saw at IMS LILI this month.

    There is a lot of chicken-and-egg here. LTI made a lot of this possible, and the success LTI (and IMS Global) have experienced would not have been possible without a lot of this. The harder you stare at the picture, the more complicated it looks. This is what “systems thinking” is all about. There isn’t a linear cause-and-effect story. There are multiple interacting feedback loops. It’s a complex adaptive system, which means that it doesn’t respond in linear or predictable ways.

    Update: I got a note from Rob Abel noting that a lot of the growth in the last leg came from an explosion of participation in the K12 space. That’s good color and consistent with what I’ve seen in my last couple of LILI conference visits. It’s also consistent with the rest of this analysis. K12 benefitted from all of the dynamics above—the maturation of the LMS market, the dynamics in higher education online that pushed toward SaaS and usability, the massive influx of venture funding, and so on. All of those developments, plus the work inside IMS, made the K12 growth possible, while the dynamics inside K12 added another feedback loop to this complex adaptive system.

    But respond it finally did. We have some semblance of a functioning market, and with its rise, blockers preventing the formation of a vibrant interoperability standards ecosystem of the type we have today have largely fallen. Now we have to address the blockers of the formation of the vibrant interoperability ecosystem that we will need tomorrow. Because it will be qualitatively different. Tomorrow’s blockers are not market formation problems but rather collaboration methodology problems. They are about creating meaningful learning learning analytics, which will require solving some wicked problems that can only be tackled through close and well structured interdisciplinary work. That most definitely includes the standards design process itself.

    After the glacier comes the flood

    What I saw at the IMS LILI this year was, I think, a milestone. The end of an era. Market pressures now favor interoperability. The same companies that were the most resistant to developing and implementing useful interoperability standards in 2007 are among the most aggressive champions of interoperability today. This is not to say that foundational interoperability work is “over.” Far from it. Rather, the conditions finally exist where it can move forward as it should, still hard but relatively unimpeded by the distortions of a dysfunctional market.

    That said, the nature and challenges of interoperability our sector will be facing in the next decade are fundamentally different from the ones that we faced in the last one. Up until now, we have primarily been concerned with synchronizing administration-related bits across applications. Which people are in this class? Are they students or instructors? What grades did they get on which assignments? And how much does each assignment count toward the final course grade? These challenges are hard in all the ways that are familiar to anyone who works on any sort of generic data interoperability questions.

    But the next decade is is going to be about data interoperability as it pertains to insight. Data scientists think this is still familiar territory and are excited because it keeps them at the frontier of their own profession. But this will not be generic data science, for several reasons. (I will tell you right now that some of them disagree with me on this. Vehemently.) First, even in the most richly instrumented fully online environments that we have today, they are highly data impoverished relative to what we need to make good inferences about teaching and learning. For heaven’s sake, Amazon still recommends things that I have already bought. If I just bought a toaster oven last month, then how likely is it that I want to buy another one now? And I buy everything on Amazon. If they don’t know enough to make good buying recommendations on consumer products, then there’s no way that our learning environments are going to have enough data to make judgements that are orders of magnitude more sophisticated.

    Well then, some answer, we’ll just collect more data! More more more! We’ll collect everything! If we collect every bit of data, then we can answer any question. (That is a pretty close paraphrase of what one of the IMS presenters said in one of the handful of learning analytics talks I went to.)

    No. You won’t collect “everything”—even if we ignore the obvious, glaring ethical questions—because you don’t know what “everything” is. Computer folks, having finally freed themselves from the shackles of SQL queries and data marts, are understandably excited to apply that newfound freedom to the important problem space of learning. But it is not a good fit, because we don’t have a good understanding of the basic cognitive processes involved in learning. As I wrote about (at length) in a previous post, we have to employ multiple cutting-edge machine learning techniques just to get glimpses of learning processes even when we are directly monitoring students’ brain activity because these are extraordinarily complex processes with multiple hidden variables. Trying to tease out learning processes inside a student’s head based on learning analytics from running machine learning algorithms on LMS data is a little like trying to monitor the digestive processes of a flatworm on the bottom of the Marianas Trench based on studying the wave patterns on the surface of the ocean. There are too many invisible mediating layers to just run a random forest algorithm on your data lake—it all sounds very organic, doesn’t it?—and pop out new insights about how students learn.

    That doesn’t mean we should just throw up our hands, by any means. To the contrary, IMS Global has some extraordinarily good tools close at hand for tackling this problem. But it does mean that they are going to have to take some of the stakeholder engagement strategies they’ve been working at diligently to the next level, to the point where the standards-making process itself may evolve over time.

    Theory-driven interoperability

    There is an excellent data and processing resource that the learning analytics folks have yet to think deeply about how to leverage, as far as I can tell from the conference. The computational power is impressive (and impressively parallel). It is the collective intelligence of educators and learning scientists. Because there are too many confounds to making useful direct inferences from the data, educational inferencing needs to be theory-driven. You need to start with at least some idea of what might be going on inside the learner’s head. One that can be either supported or disproven based on evidence. And you need to know what that evidence might look like. If you can spell all that out, then you can start doing interesting things with learning analytics, including machine learning. There is room for learning science, data science, and on-the-ground teaching expertise at the table. In fact, you need all those kinds of expertise. But the folks with those respective kinds of know-how need to be able to talk to each other and work together in the right ways, which is really hard.

    The IMS has an outstanding foundation for this sort of work, because their Caliper specification turns out to provide the basis for a perfectly lovely lingua franca. To begin with, its fundamental structure is triples, which is the same basic idea as the original concept behind the semantic web. If you’re not a computer person and this is starting to make your eye’s glaze over, don’t worry, because this is plain English. Three-word sentences, in fact. Noun, verb, direct object. Student takes test. Question assesses learning objective. Student highlights sentence. Sentence discusses Impressionism.

    IMS Caliper expresses learning analytics in statements that can easily be translated into three-word plain-English sentences. These sentences can be strung together into coherent paragraphs. Notice, for example, how the last two example sentences are related. Three-word sentences in this format can be chained together to form longer thoughts. New thoughts. With this one, very simple grammatical structure, we have a language that is generative in the linguistic sense. As long as you have words to put into these grammatical placeholders, you can string thoughts together. Or “chain inferences,” to sling the lingo. And it turns out, unsurprisingly, that Caliper has a mechanism for defining these words in ways that both humans and machines can understand them.

    That has to be the bridge. Humans have to understand the utterances well enough to be able express their theories on the front end and understand whatever the machine is telling them it may have learned on the back end. Machines have to understand them specifically enough to be able to parse the sentences in their own, literal, machine-y way. Theoretically, Caliper could be an ideal language to enable educators and computer scientists to discuss theories about how to better support students as well as how to test those theories together.

    The challenge is that the IMS community, at least based on what I saw in the sessions I attended, is not using the specification as an interdisciplinary communication tool in this way yet. What I saw happening instead was a lot of very earnest data scientists pumping as much Caliper data as the can into their data lakes. They come to the conference, give a talk and, to their credit, shrug their shoulders and admit that they really don’t know what to do with those data yet. But then they go home and build bigger pipes, because that’s their job. That’s what they do.

    It’s not their fault. I’ve been friends with some of these folks for a very long time indeed. There are good people here. But if you work in the IT department, and you’re not a learning scientist or a classroom educator, and the faculty are somewhere between dismissive and disdainful of the idea of talking to you about working together to improve teaching and learning, then what can you do? You do what you know how to do and hope that things will change for the better over time.

    It’s not the IMS’s fault either. The conference I attended was called the IMS Learning Impact Leadership Institute. That’s not a new name. Caliper has board that helps guide its direction. That board includes educators who are the kind of advocates that I would like to see on such a body. They are productive irritants in the best possible way. But that’s not enough anymore. This is just a really hard problem. It’s the challenge of the next decade. To meet it, we need to do more than just make sure the right people are in the room together. We need to develop new ways of working together. New roles, methodologies, ways of talking with each other, and ways of seeing the world.

    I’m going to preview a bit of a post that I have in my queue for…I’m not sure when, but some time soon…by mentioning “learning engineering.” This term has gotten a lot of buzz lately, along with some criticism. I’ll be writing up my own take on it, but for now I’ll say that one reason I think the term is gaining some currency is that it represents a set of skills for being a mediator in the kind of collaboration that I’m describing here.

    As it turns out, it was coined by Nobel prize-winning polymath and Carnegie Mellon luminary Herb Simon, after whom Carnegie Mellon University’s Simon Initiative was named. And, as it also turns out, the Simon Initiative hosted this year’s EEP summit and made some news in the process by contributing $100 million worth of open source software that they use in their research and pratice of…wait for it…learning engineering.

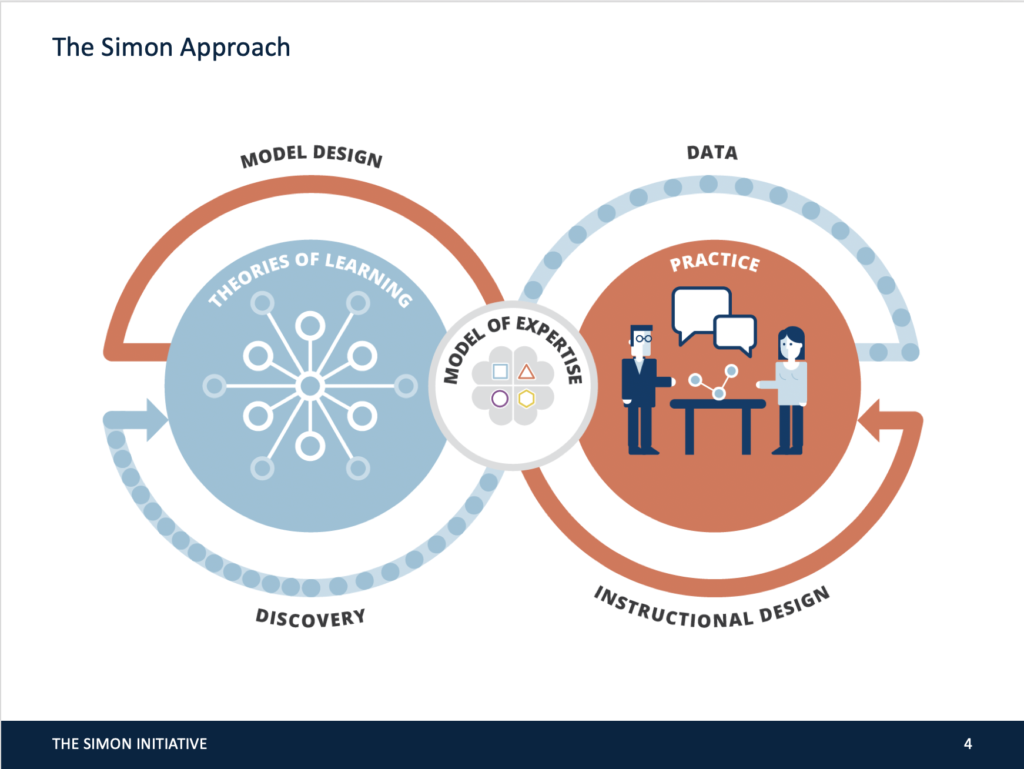
    Here’s a slide that they used in their talk explaining what the heck learning engineering is and what they are doing when they are doing it:

    Copyright Carnegie Mellon University, CC-BY

    (By the way, the videos of all talks from the summit will be posted online, as promised. Please be patient a little longer.)

    This post has already run long, so rather than unpacking the slide, I’ll leave you with a question or two. Think about this graphic as representing a data-informed continuous improvement methodology involving multiple people with multiple types of expertise. What would that methodology need to look like? Who would have to be at the table, what kinds of conversations would they have to have, and how would they have to work together?

    I’m not suggesting that “learning engineering” is a magical conjuring phrase. But I am suggesting that we need new approaches, new competencies, and likely a new role or two if we are going to get to the next updraft.

  • The Need For Learning Engineers (and Learning Engineering)

    Editor’s Note: I am pleased to announce that Bill has agreed to continue contributing blog posts from time to time. Therefore, he is now officially a “Featured Blogger” rather than a “Guest Blogger.”

    Last week, I had the privilege of speaking at a workshop on online graduate education. At that workshop, Carnegie Mellon University Provost and Executive Vice President Dr. Mark Kamlet used the words “Learning Engineering” in his keynote which I built upon in my talk.  In my previous post I referenced the need of semantic data and algorithms to support learning engineers to create and iteratively improve courses and courseware (among other things).  I felt it was worth taking a little time to describe just what I believe that means.

    For over 10 years, the Open Learning Initiative has been bringing together teams to develop online course materials.  Carnegie Mellon is an ideal place to cultivate this work due to its multi-disciplinary programs and culture aside from its expertise in the related fields.   During that time we’ve built a team of experts that are critical to the building of learning environments informed by research and capable of recording data for iterative improvement as well as creating dynamic reports for stakeholders.

    (more…)