The “Ed Tech” category includes posts about educational technology products themselves, including LMSs and other learning platforms, adaptive learning and other digital curricular materials products, learning analytics, and educational apps of all types. It also includes technical aspects of ed tech products, especially interoperability.
I’m delighted to announce a project aimed at making it easier to share interactive digital content at the lesson level as well as to establish baseline educational analytics for digital curricular materials. I’m tempted to call this a “courseware” interoperability effort, but its potential application is broader than that term would imply to some folks. For example, the work could support well-structured content in LMSs.
This effort is consistent in philosophy with my recent “Content as Infrastructure” post series as well as the post of a version of my IMS talk on interoperability, learning analytics, and pedagogical intent. One of the main outputs of the project will be a white paper, released as an Empirical Educator Project (EEP) contribution, describing the standards proposal that is ultimately developed and its value to education. The project also dovetails very nicely with both previously announced and as-yet-unannounced EEP projects, and I’m very excited about the work.
The idea for the work both grew out of and is funded through a grant from the U.S. Department of Education (ED) to develop “active OER.” In the course of the grant planning process, ASU professor and grant PI Ariel Anbar came to the conclusion that the grant would have a much broader impact if the content being developed were interoperable. He consulted with ED, and they agreed that interoperability would potentially increase the impact of the resources related to the grant. So a small fragment of the grant budget was carved off to test the viability of building a coalition that can make useful progress on proposed standards definitions that are both practically useful and likely to be adopted. At the moment, my work as a facilitator is the main budget expense for the project.
Business and mission goals
We had a kick-off meeting of a small group in late October. (More on who was in it, why they were chosen, and how we hope to expand later in this post.) Here are the notes I captured on the goals and ambitions for impact:
Reduce platform lock-in for any interactive courseware content, particularly interactive OER content, which will support the following:
Increase the quality of existing OER content by enabling the preservation of learning design
Increase the supply of interactive OER content by creating a clear and achievable interoperability standard for content developers
Increase the availability and value of OER content for value-added platform and service providers by lowering the cost of goods involved in converting the currently available “flat” OER resources into interactive lessons with effective learning design
Enable educators to more easily mix and match interactive content at the lesson level
Enable the development of an ecosystem of non-OER content that could be licensed at the lesson level
Enable lesson-level, cross-platform, cross-content learning analytics which will support the following:
Data-based continuous improvement of learning content, regardless of its source
Baseline student learning analytics capabilities that will enable institutions to monitor student progress in an apples-to-apples way across lessons, products, and courses
Student- and instructor-facing analytics that will help them analyze how well their respective learning and teaching strategies impact outcomes
A vision for implementation and ecosystem development that incentivizes participation for a wide range of commercial and non-commercial value-added participants in order to:
Lower the barrier to adoption for courseware platforms by assuring customers that any content they develop or use will not be locked into the licensed platform
Lower the cost-of-goods and availability of high-quality pre-existing content for value-added OER curricular materials product and service providers
Enable micro-licensing models for commercial content vendors that develop high-value lesson-level content
Lower the barrier for non-profit organizations and consortia to create interactive content that is competitive in functionality and measurable quality with baseline student and teacher expectations for commercial courseware
I’ll provide more of my personal take on these goals in a subsequent post, but there is consensus in the group that we should be working toward a set of goals that are good for everyone—students, instructors, institutions, and value-added content and platform providers.
Functional and technical goals
Consistent with the posts I linked to at the top of this one, we’re going to start by identifying questions that educators and students would want to answer about student progress, effectiveness of content design, and effectiveness of learning intervention. Our default atomic unit for this work is the “lesson.” Our starting point for identifying this set of questions will be the ones that the participating implementors have identified as ones that their users/adopters/customers want to answer, but I expect that we’ll expand from that base over the two-year life of the initial project.
Once we know what questions we want to answer, then we will identify the metadata for the content that is needed to answer those questions. For example, which learning objective(s) does this assessment question assess? Is the assessment formative or summative? That sort of thing. No firm decisions have been made about how this would work on the technical level, but the basic idea is that the pedagogical intent of the learning design would be captured in some machine-readable form.
Technically, we’d like to build on as much existing standards infrastructure as possible and propose developing as little new work as possible. While the project, as a piece of a larger ED grant, does not have a formal affiliation with an interoperability standards body, I am pleased to say that IMS Global and its CEO, Rob Abel, have been highly encouraging and offered technical support to the group as we think through the effort. IMS has a lot of the infrastructure that would be needed for the effort already baked into its existing specifications. It makes all the sense in the world to try to re-use or extend standards that are already developed and adopted.
Ultimately, the group will produce a set of recommendations for interoperability standards along with a rationale for those recommendations. The hope and intention are that these recommendations will be taken up and carried forward by the appropriate bodies at the end of the project and that the participants will continue to work together on implementation.
More on process and risk management
Standards development is a tricky business. You want to get to an “everybody in the pool” moment, but at the same time, you can’t win everybody over by promising to boil the ocean. So we thought a lot about how to get this process rolling and balance different risks over time.
At my suggestion, we started by inviting in just a few of the many implementors who ultimately should be at the table. Two—Carnegie Mellon University’s Open Learning Initiative and Lumen Learning—are long-time and active participants in the OER world. While this effort will be helpful to more than just OER, the primary purpose of the grant is for the development of (inter)active OER, so we wanted representatives who could speak to the needs and nuances of the OER ecosystem. The two other implementors we invited—Smart Sparrow and CogBooks—are courseware platform implementers that both work extensively with ASU already. Smart Sparrow is also playing a major role in this OER grant since Ariel has chosen its Inspark Education network to help manage the grant and is building the content on the Smart Sparrow platform. Also, CMU, Lumen, and Smart Sparrow have all been participants in EEP. In addition to the implementers and ASU, we had representatives from Scottsdale Community College and ED at the kick-off meeting.
This is a small enough group with enough interconnections that we have a good chance of making progress on scoping goals without excessive amounts up-front diplomacy required but diverse enough that we would get different opinions and perspectives. It’s a good group for getting started and for testing the basic idea that what we want to accomplish is doable within a reasonable period of time. Ultimately, however, the project will need more and different folks to be involved if it going to result in broadly implemented interoperability standards. The starting group of four implementer participants is going to work toward a letter they all can sign onto that says they are committing in principle to implement any standards that ultimately flow out of this effort. The value in their commitment at this early stage is to decrease the risk of other implementors who may want to join but are skeptical that the effort will produce results. In parallel, the project is seeking additional funding that would enable us to support the participation of more stakeholders—educators, platform implementers, content developers, and standards committees (and possibly students as well).
It is early days for this work. So far, the group has only met once. There is still a lot to do and a lot to be figured out. But I am hopeful that we can both develop useful recommendations for advancing interoperability standards and pioneer some new ways of working together on productive EdTech collaboration in the process.
I’ve been asked by several folks to write up some version of the talk I gave at the recent IMS learning analytics summit. The focus was on how, going forward, interoperability standards will need to capture pedagogical intent if we are going to develop meaningful learning analytics.
This isn’t a word-for-word transcription of that talk, but it does capture the gist. The subtitles and literary quotes are mostly from the original presentation. Many thanks to Rob Abel and Cary Brown for inviting me and giving me the opportunity to speak to the IMS community about this important inflection point.
Interoperability is communication
We are not here to curse the darkness, but to light the candle that can guide us through that darkness to a safe and sane future.
John F. Kennedy
Ten or fifteen years ago, when we talked about what we wanted from EdTech software interoperability, most of the time the things we wanted seemed like they ought to be simple. Mostly, we just wanted to transfer student roster and grade information from one system to another. When we got a little more ambitious, we asked for single sign-on and the ability to put a little window of one application into another one. This was foundational interoperability. It wasn’t “disruptive” or “revolutionary” or otherwise life-altering, but it was important.
My first close encounter with an IMS interoperability effort was when I worked at Oracle in on Peoplesoft Campus Solutions team. We just wanted to be able to send a course roster to the LMS and have the LMS send a final grade for each student back. Going in, I couldn’t understand why that was hard or why it hadn’t already been done. All I knew was that (a) it was a problem that IMS had tried and failed to solve at least once before, since we were working on the revision of an existing standard, and (b) a consequence of that failure was that IT professionals on campuses everywhere had to cook up their own, often time-intensive, duct-tape-and-chewing-gum solutions to getting roster data into the LMS. As for grades, it made no sense to me that faculty had to copy grades from their electronic LMS grade book and manually re-enter them into their electronic SIS grade book. It seemed weird that this was a thing.
It turned out that there was a translation problem. Registrars think about classes very differently than instructors and students do. For a registrar, if a student is taking a “statistics for psychology majors” course, and that course can be taken for credit in either the psychology or the math department, then “statistics for psychology” is actually two completely separate courses. And the decision of which of the two courses a student registers for may make the difference between that student meeting the requirements for graduation or not. On the other hand, the students and instructor experience “statistics for psychology” as one course meeting in one place on one schedule with one syllabus and one group of people.
Good software reflects and supports the needs and expectations of its users. Accordingly, SIS software represented “statistics for psychology” as two courses, while LMS software wanted to create one course space for it. In order to have roster information show up as instructors and students expect it in the LMS and then return final grades as the registrar expects them in the SIS, the standards committee had to recognize that there was a translation problem and design a specification that could function as a two-way translator.
This was an important lesson for me. Even seemingly simple interoperability challenges can be complicated because they often aren’t about the software so much as they are about the people who use the software. Interoperability design is at least partly a liberal art.
Now, today, we would have a different possible way of solving that particular interoperability problem than the one we came up with over a decade ago. We could take a large data set of roster information exported from the SIS, both before and after the IT professionals massaged it for import into the LMS, and aim a machine learning algorithm at it. We then could use that algorithm as a translator. Could we solve such an interoperability problem this way? I think that we probably could. I would have been a weaker product manager had we done it that way, because I wouldn’t have gone through the learning experience that resulted from the conversations we had to develop the specification. As a general principle, I think we need to be wary of machine learning applications in which the machines are the only ones doing the learning. That said, we could have probably solved such a problem this way and might have been able to do it in a lot less time than it took for the humans to work it out.
I will argue that today’s EdTech interoperability challenges are different. That if we want to design interoperability for the purposes of insight into the teaching and learning process, then we cannot simply use clever algorithms to magically draw insights from the data, like a dehumidifier extracting water from thin air. Because the water isn’t there to be extracted. The insights we seek will not be anywhere in the data unless we make a conscious effort to put them there through design of our applications. In order to get real teaching and learning insights, we need to understand the intent of the students. And in order to understand that, we need insight into the learning design. We need to understand pedagogical intent.
That new need, in turn, will require new approaches in interoperability standards-making. As hard as the challenges of the last decade have been, the challenges of the next one are much harder. They will require different people at the table having different conversations.
Data and communication are not the same
O wonder! How many goodly creatures are there here! How beauteous mankind is! O brave new world That has such people in’t!
William Shakespeare
The quote above is from The Tempest. Here’s the scene: Miranda, the speaker, is a young woman who has lived her entire life on an island with nobody but her father and a strange creature who she may think of as a brother, a friend, or a pet. One day, a ship becomes grounded on the shore of the island. And out of it comes, literally, a handsome prince, followed by a collection of strange (and presumably virile) sailors. It is this sight that prompts Miranda’s exclamation.
As with much of Shakespeare, there are multiple possible interpretations of her words, at least one of which is off-color. Miranda could be commenting on the hunka hunka manhood walking toward her.
“How beauteous mankind is!”
Or. She could be commenting on how her entire world has just shifted on its axis. Until that moment, she knew of only two other people in all of existence, each of who she had known her entire life and with each of whom she had a relationship that she understood so well that she took it for granted. Suddenly, there was literally a whole world of possible people and possible relationships that she had never considered before that moment.
“O brave new world / That has such people in’t”
So what is on Miranda’s mind when she speaks these lines? Is it lust? Wonder? Some combination of the two? Something else?
The text alone cannot tell us. The meaning is underdetermined by the data. Only with the metadata supplied by the actor (or the reader) can we arrive at a useful interpretation. That generative ambiguity is one of the aspects of Shakespeare’s work that makes it art.
But Miranda is a fictional character. There is no fact of the matter about what she is thinking. When we are trying to understand the mental state of a real-life human learner, then making up our own answer because the data are not dispositive is not OK. As educators, we have a moral responsibility to understand a real-life Miranda having a real-life learning experience so that we can support her on her journey.
Intention matters in education
With regard to moral rules, the child submits more or less completely in intention to the rules laid down for him, but these, remaining, as it were, external to the subject’s conscience, do not really transform his conduct.
Jean Piaget
The challenge that we face as educators is that learning, which happens completely inside the heads of the learners, is invisible. We can not observe it directly. Accordingly, there are no direct constructs that represent it in the data. This isn’t a data science problem. It’s an education problem. The learning that is or isn’t happening in the students’ heads is invisible even in a face-to-face classroom. And the indirect traces we see of it are often highly ambiguous. Did the student correctly solve the physics problem because she understands the forces involved? Because she memorized a formula and recognized a situation in which it should be applied? Because she guessed right? The instructor can’t know the answer to this question unless she has designed a series of assessments that can disambiguate the student’s internal mental state.
In turn, if we want to find traces of the student’s learning (or lack thereof) in the data, we must understand the instructor’s pedagogical intent that motivates her learning design. What competency is the assessment question that the student answered incorrectly intended to assess? Is the question intended to be a formative assessment? Or summative? If it’s formative, is it a pre-test, where the instructor is trying to discover what the student knows before the lesson begins? Is it a check for understanding? A learn-by-doing exercise? Or maybe something that’s a little more complex to define because it’s embedded in a simulation? The answers to these questions can radically change the meaning we assign to a student’s incorrect answer to the assessment question. We can’t fully and confidently interpret what her answer means in terms of her learning progress without understanding the pedagogical intent of the assessment design.
But it’s very easy to pretend that we understand what the students’ answers mean. I could have chosen any one of many Shakespeare quotes to open this section, but the one I picked happens to be the very one from which Aldous Huxley derived the title of his dystopian novel Brave New World. In that story, intent was flattened through drugs, peer pressure, and conditioning. It was reduced to a small set of possible reactions that were useful in running the machine of society. Miranda’s words appear in the book in a bitterly ironic fashion from the mouth of the character John, a “savage” who has grown up outside of societal conditioning.
We can easily develop “analytics” that tell us whether students consistently answer assessment questions correctly. And we can pretend that “correct answer analytics” are equivalent to “learning analytics.” But they are not. If our educational technology is going to enable rich and authentic vision of learning rather than a dystopian reductivist parody of it, then our learning analytics must capture the nuances of pedagogical intent rather than flattening it.
This is hard.
Some more examples
The lesson assessment example is easy enough to understand. (My post series on content as infrastructure explores it in more detail.) But the more one looks around at the full range of analytics that are truly aimed at supporting student success, the clearer the lesson about capturing intent becomes.
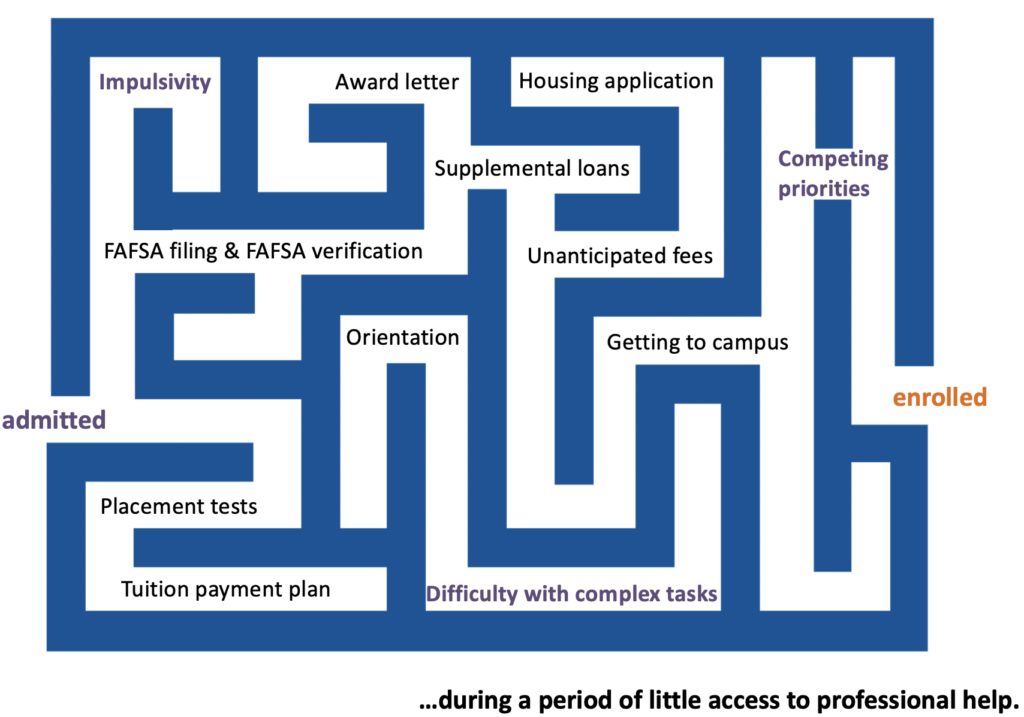
Take, for example, summer melt. I recently just hosted an entire hour-long Standard of Proof webinar on this topic. (You should watch it. It’s good.) Here’s a slide from that webinar which illustrates the obstacles that first-generation students face in getting from their college acceptance letter to the first day of class:
The Summer Melt Maze
Credit: Lindsay Page
Each of the text labels represents an obstacle that first-generation students in particular may struggle to overcome, because their circumstances are complex (e.g., no parent to provide a parental signature), because they don’t have parents or guardians who have the training and knowledge to help them, and/or because they’re seventeen-year-old kids. I don’t know about you, but I don’t think I had to navigate a single one of these obstacles without parental help, and I don’t know if I could or would have done so without it.
Now think about developing a software solution to identify the specific barrier a student is struggling with and provide appropriate help. Could you solve the problem simply by sucking in enough data and running a machine learning algorithm? I very much doubt it. And even if you could, think about how invasive you would have to be to do so. Think about the privacy implications. The cure would be worse than the disease.
Georgia State University took a different approach. They have invited students to share their intent. They use a chatbot. A chatbot is a conversational interface. Students can ask directly about the problems they were encountering. Once students specify their intent, then machine learning can be used to further disambiguate it. For example, the software can figure out that a student who writes “I have no money” may be asking for help obtaining financial aid. But only because there is a conversational interface, and because the software behind that interface has been programmed to anticipate and respond to a certain range of questions that a student might come to the chatbot for answers. Through a combination of the interface layer, the data layer, and the usage context, the educational intent was encoded into the system.
Here’s another example that postdates my talk. ACT recently released a paper on detecting non-cognitive education-relevant factors like grit and curiosity through LMS activity data logs. This is a really interesting study that I hope to write more about in a separate post in the near future, but for now, I want to focus on how labor-intensive it was to conduct. First author John Whitmer, formerly of Blackboard, is one of the people in the learning analytics community who I turn to first when I need an expert to help me understand the nuances. He’s top-drawer, and he’s particularly good at squeezing blood from a stone in terms of drawing credible and useful insights from LMS data.
Here’s what he and his colleagues had to do in order to draw blood from this particular stone:
The online interaction features were generated from the LMS clickstream data. After manual inspection, we determined that the action field alone (e.g., “opened”) was insufficient to address our research questions and needed to be joined with the label of the item that the action was taken in reference to, which was a complex pairing. For example, course item values in the LMS data include “Week 12: Electrochemistry” or “CHEM 102 Practice Exam 4B,” which were easily interpretable from the course syllabus, while others (e.g., “2/27 CL” or “18.7 RQ”) required confirmation from the instructor. Hence, we created broader activity categories for these activity events in the LMS data using the course syllabus with confirmation from the instructor which resulted in 110 unique activity events in the LMS data that were recoded to a total of 21 activity categories as described in Table 4.
First, they had to look at the syllabi. With human eyeballs. Then they had to interview the instructors. You know, humans having conversations with other humans. Then the humans—who had interviewed the other humans in order to annotate the syllabi that they looked at with their human eyeballs—labeled the items being accessed in the LMS with metadata that encoded the pedagogical intent of the instructors. Only after they did all that human work of understanding and encoding pedagogical intent could they usefully apply machine learning algorithms to identify patterns of intent-relevant behavior by the students.
LMSs are often promoted as being “pedagogically neutral.” (And no, I don’t believe that Moodle is any different.) Another way of putting this is that they do not encode pedagogical intent. This means it is devilishly hard to get pedagogically meaningful learning analytics data out of them without additional encoding work of one kind or another.
Interoperability without intent creates chaos
If Jorge Luis Borges’ Library of Babel could have existed in reality, it would have been something like the Long Room of Trinity College.
Christopher de Hamel
I want to underscore the point that simply collecting more data and writing more clever algorithms will not help us find a way out of the problem of that last example. It is a problem of epistemic closure. Data and knowledge are not the same, and more data do not necessarily unlock more knowledge.
“The Library of Babel” is a short story by the great Jorge Luis Borges. (It’s only nine pages long. You should read it.) The story describes a world that perfectly captures the nature of the problem we face:
The universe (which others call the Library) is composed of an indefinite and perhaps infinite number of hexagonal galleries, with vast air shafts between, surrounded by very low railings. From any of the hexagons one can see, interminably, the upper and lower floors. The distribution of the galleries is invariable. Twenty shelves, five long shelves per side, cover all the sides except two; their height, which is the distance from floor to ceiling, scarcely exceeds that of a normal bookcase. One of the free sides leads to a narrow hallway which opens onto another gallery, identical to the first and to all the rest. To the left and right of the hallway there are two very small closets. In the first, one may sleep standing up; in the other, satisfy one’s fecal necessities. Also through here passes a spiral stairway, which sinks abysmally and soars upwards to remote distances….
There are five shelves for each of the hexagon’s walls; each shelf contains thirty-five books of uniform format; each book is of four hundred and ten pages; each page, of forty lines, each line, of some eighty letters which are black in color. There are also letters on the spine of each book; these letters do not indicate or prefigure what the pages will say….
The orthographical symbols are twenty-five in number. This finding made it possible, three hundred years ago, to formulate a general theory of the Library and solve satisfactorily the problem which no conjecture had deciphered: the formless and chaotic nature of almost all the books. One which my father saw in a hexagon on circuit fifteen ninety-four was made up of the letters MCV, perversely repeated from the first line to the last. Another (very much consulted in this area) is a mere labyrinth of letters, but the next-to-last page says Oh time thy pyramids. This much is already known: for every sensible line of straightforward statement, there are leagues of senseless cacophonies, verbal jumbles and incoherences….
Five hundred years ago, the chief of an upper hexagon came upon a book as confusing as the others, but which had nearly two pages of homogeneous ines. He showed his find to a wandering decoder who told him the lines were written in Portuguese; others said they were Yiddish. Within a century, the language was established: a Samoyedic Lithuanian dialect of Guarani, with classical Arabian inflections. The content was also deciphered: some notions of combinative analysis, illustrated with examples of variations with unlimited repetition. These examples made it possible for a librarian of genius to discover the fundamental law of the Library. This thinker observed that all the books, no matter how diverse they might be, are made up of the same elements: the space, the period, the comma, the twenty-two letters of the alphabet. He also alleged a fact which travelers have confirmed: In the vast Library there are no two identical books. From these two incontrovertible premises he deduced that the Library is total and that its shelves register all the possible combinations of the twenty-odd orthographical symbols (a number which, though extremely vast, is not infinite): Everything: the minutely detailed history of the future, the archangels’ autobiographies, the faithful catalogues of the Library, thousands and thousands of false catalogues, the demonstration of the fallacy of those catalogues, the demonstration of the fallacy of the true catalogue, the Gnostic gospel of Basilides, the commentary on that gospel, the commentary on the commentary on that gospel, the true story of your death, the translation of every book in all languages, the interpolations of every book in all books.
Jorge Luis Borges
The rest of the story is a rumination on how humans might make sense of this infinite series of rooms—this “data lake,” in modern parlance—in absence of any information about the intent of its creator.
Since the Library contains every possible book with that number of pages, lines and characters, somewhere in all these rooms must exist a book that explains exactly what it all means. So it’s a data search problem, right?
Wrong. Because there also exist books that are extremely similar but differ in minor but critical details. And books that argue why the book with the Truth is actually false. For that matter, there are books that contain many of the exact same words in the exact same order but are written in languages in which the words mean different things. How can one tell which account is the Truth?
One can’t.
If we are going to make progress toward educationally useful analytics, then we must ruthlessly expunge all traces of magical thinking about data. There are fundamental limits to what the data can tell us. Even systems that are designed for pedagogical intent do not necessarily encode it in a way that is useful for interoperable analytics. In some cases, it may be encoded at the user interface layer. A courseware authoring platform may never label an assessment as “formative” or “summative” in the data because the intended distinction is obvious to the users. In other cases, the data may be encoded in an idiosyncratic manner that does not map well to other systems (either of software or of thought). In still other cases, it may be designed badly and incorrectly or misleadingly reflect the pedagogical intent. It would be relatively easy to create a data lake of Babel which we could explore infinitely in a fruitless search for meaning.
That way lies madness.
If we want useful educational analytics, then we cannot simply worship the data and the algorithms. The humans must do some of the learning.
The “semantic web” is all about intent
I love you. You are the object of my affection and the object of my sentence.
Mignon Fogarty
One of the triggers for my being invited to speak at IMS about learning analytics in the first place was a previous post I wrote which was (partly) on how the structure of Caliper, which is borrowed from the structure of the semantic web, supports new sorts of interoperability conversations. Since you can read that blog post, I won’t repeat the argument in detail here. But the gist is that we both have to and can boil down chains of inference that combine pedagogical intent into simple human language that educators can understand and articulate for themselves. The triple structure of the semantic web—a simple three-word sentence with a subject, a verb, and a direct object—is designed to enable non-technical humans to string thoughts and inferences together in ways that enable more technical humans to translate those inference patterns into data structures and interoperability requirements.
Right now, IMS Caliper adopters are largely using this vernacular as just one more IT tool for largely old-school data centralization. So now they use a “lake” instead of a “warehouse.” It’s still a centralized and IT-specialized mindset which is not suited for thinking about making meaning from multiple applications, never mind talking with other humans about interpreting the intent of users working across multiple applications.
This is the problem that must be solved over the next decade to make real progress on educational analytics. It is at least partly a liberal arts problem. And it will be at least a decade’s worth of work, though we don’t have to wait that long to see early results.
You get to choose the world we live in
O wonder! How many goodly creatures are there here! How beauteous mankind is! O brave new world That has such people in’t!
Shakespeare or Huxley?
So which will it be? A brave new world in which we experience continuous wonder at how beauteous mankind is, or one in which “learning” is defined by the ability to correctly answer a series of questions and earn some digital badges? The difference between these possible futures is not one in which we embrace or reject technology, or data. It’s one in which we either embrace or ignore the complexity of human learning and the reality that we must make a conscious effort to ensure that some of this complexity is encoded into the data if we are going to design analytics systems that are educationally useful. We need to elicit specific reactions from our students as expert educators and encode the pedagogical intent for eliciting those reactions along with the reactions themselves.
I am just thrilled to post the archive of our inaugural Standard of Proof webinar:
Summer Melt Standard of Proof webinar
https://youtu.be/7NoYUa_VHfs
It is a near-perfect encapsulation of everything that the Empirical Educator Project aspires to promote and foster: front-line educators, academic researchers, and commercial vendors working together to measurably increase student success and to do so in a way that is both persuasive in terms of the rigor of evidence and repeatable by other institutions.
As a reminder, Standard of Proof highlights academic collaborations by the Empirical Educator Project’s commercial sponsors with academic researchers and academic practitioners. All projects must either contribute new knowledge to the commons or promote the diffusion of established evidence-backed practices.
In this case, we have a story of a small EdTech start-up—AdmitHub—that has a total of nine randomized controlled trials either completed or in process with academic partner institutions.
Nine.
How many of your EdTech vendors have nine randomized controlled trials either done or in the works? How many have one? How many have you even asked this question? (If you want better answers on the first two questions, then try to improve your answer to the last one.)
They were able to do this, in part, because institutions like Georgia State University had real leaders, like GSU’s Tim Renick, who refused to accept the proposition that disadvantaged students were already beyond help by the time they got to college. Instead, the GSU folks (and their colleagues at other academic institutions conducting research with AdmitHub) set out to study their own practices and identify areas that they were failing students in ways that could be fixed. Using data, with the help of their vendor and an academic researcher—in this case, University of Pittsburgh Professor and summer melt expert Lindsay Page—GSU demonstrated that we can make education better and more equitable. It is the perfect counter-example to the sad situation I described in my post on what I didn’t see at EDUCAUSE.
This is the future that we all should be reaching for, folks. And it is reachable, as all three of my guests made clear. The video is well worth an hour of your time. Standard of Proof webinar production values will improve as we learn our craft, but the conversation quality just doesn’t get much better than this.
We’re actively working on the spring webinar line-up and will have some juicy conversations scheduled by the time you return from your holiday break.
At the OpenEd conference this week, David Wiley made an announcement that was more significant than it may have sounded. Before I attempt to further characterize or analyze it, I think you should read it for yourself in its entirety, copied here from David’s blog: ((Disclosure: David is an employee of Lumen Learning, a sponsor of the Empirical Educator Project.))
In 2003 I invited a small group of about forty people interested in open content and open courseware to Logan, Utah. Since then, this annual meeting has grown year after year to where we are today – 850 people interested in everything from open educational resources and open educational practices to sustainability and social justice. This annual conference has been a remarkable forum for the community to meet, share ideas, and foster collaborations, and the conference community is larger and more diverse than ever before.
With that growth comes change. That little meeting I convened 15 years ago has evolved organically in a way that has served the community fairly well. However, as currently constituted, the conference does not leverage all the energy, enthusiasm, passion, and leadership ability in our increasingly large and increasingly diverse community. And so the time has come for us to reconsider, as a community, how we wish to organize ourselves, learn from each other, and collaborate with one another.
In order to make the necessary space for that conversation, this year’s Open Education Conference is the last I plan to organize. As of this Friday afternoon the conference will be adjourned indefinitely. This is not a call for another person or organization to come forward to keep the same conference running the same way into the future.
Rather, it’s a call to reset and start over. To go back to the drawing board – as a community – and critically examine all of our assumptions about conferences, to grapple with a range of ideas about how we want to learn from and collaborate with each other, and to talk frankly about our end goals and guiding values. And when something like a consensus starts to emerge, the community can choose what to do next. To borrow a phrase, this is an opportunity to revise and remix what is, honestly, a very traditional academic conference, into something – or some things – far better.
This reimagining must be owned by the community. It must be driven by the community. And it would be inappropriate for me to try to facilitate that process beyond extending a brief invitation. And so I invite all of you to use the breaks, lunches, dinners, and other free time you have here in Phoenix to engage in this critical reimagining and to explore with one another the possible shapes future meetings of our community – or communities – might take. I expect this will be a difficult, messy, and at times even painful process. But most things worth doing are.
On a personal note, I want to thank the hundreds of people who have made the conference incredible over the years by presenting, reviewing proposals, convening sessions, volunteering at the information desk, and in countless other ways. Thank you to our Program Committees. Thank you to our sponsors. Thank you to Utah State University, Brigham Young University, BCcampus, and Lumen Learning for serving as the conference’s fiscal agents and logistics leads over the years. Most of all, thanks to each of you. Thank you for giving a bit of yourself to this community, for building each other up, and for moving the work forward. And, as always, thank you for everything you do for students.
I was at the conference for the first day and heard a range of different reactions to the news. Some said it was no big deal and that characterizing it as essentially a changing of the guard of the leadership:
I think the framing of the conference as "ending" was not the best choice of wording. Really, the founder stepped down, that's all. It's new beginning for more diverse & inclusive model. And I say this as some1 who was participating in #oer since 2003 #opened19#notgoinganywhere
I think the framing of the conference as “ending” was not the best choice of wording. Really, the founder stepped down, that’s all. It’s new beginning for more diverse & inclusive model. And I say this as some1 who was participating in #oer since 2003 #opened19#notgoinganywhere
@lpetrides
Others expressed more concern about the nature of the handoff from David to the next steward than Lisa did, but the fundamental view was the same.
In my opinion, these reactions miss an underlying dynamic that makes this change more serious and difficult to patch over than it may appear on the surface. OpenEd was always at least partly an exercise in coalition politics. The attendees were a mix of people coming with different primary and secondary goals that overlapped enough for them to make common cause. That coalition has crumbled. In fact, it has been crumbling for some time. The idea that this conference could have been neatly handed off to some new steward as-is assumes that OpenEd is is otherwise tenable as-is. I don’t believe that is true.
This is not ultimately about David Wiley or even Lumen Learning stepping away from organizing the conference (although the loss of an organization willing to manage an 850-person conference is a significant blow). My conversations with various OpenEd participants this week provided ample confirmation to me that there continue to be long-standing and deepening fractures within the OpenEd coalition, even though many of the participants are either not fully aware of them or not seeing how consequential they are in terms of how people may think about future convenings.
I am by no means suggesting that OER or “open education”—whatever that is—is itself in danger of ceasing to exist. OpenEd is the only conference I know of that fell apart in a year when it had record attendance. If anything, OER adoption appears to be accelerating. In fact, I believe it is precisely OER’s success and growth that may have pushed this long-simmering problem to its breaking point. That growth has caused the balance of power within the coalition shifted in ways that created tensions among coalition members. Ultimately, those tensions proved insurmountable. The center did not hold.
The OpenEd conference as we know it is dead. It may come back in some form, possibly even next year, and possibly even with the same name. But it won’t be the same coalition with the same focus and balance of interests. It won’t be the same OpenEd. That is neither necessarily bad nor necessarily good. But whether it is good, bad, or indifferent, it is a fact.
This was foreseeable—and foreseen
The OpenEd coalition has long consisted of (at least) three different groups with three different primary goals:
Increase access to education by lowering cost of curricular materials
Increase quality of education by increasing quality of curricular materials
Promote values of education by fostering autonomy for educators and agency for learners
Many—possibly most—of the OpenEd participants would likely say that they support all three of these goals. (I certainly do.)
That’s good. Overlapping priorities are a critical success factor in building coalitions. But it’s not everything. Depending on how you interpret and rank these three priorities, your beliefs about strategy and values could be quite different. And there have long been signs that, in fact, there were very serious tensions among the views and priorities of the coalition members.
In 2015, Phil Hill and I gave a joint keynote at the OpenEd conference in Vancouver. The theme of our talk was precisely that OpenEd was a brittle coalition that could fracture if the coalitional challenges were not addressed. Phil, in his part, talked about the challenge and opportunity that faculty surveys about OER demonstrated. There was a lot to be accomplished. My half of the talk was about my experience as a climate activist and how hard it is to build a coalition that holds together and accomplishes its goals over time (hint hint).
Here are some of the questions that I encouraged the conference participants to discuss:
What is your goal?
What is your theory of change?
What is your strategy?
Who do you have to convince?
What are your obstacles?
What power do you have?
Who are your natural allies?
Who is persuadable?
What is your best message?
Who are you willing to let win?
What are you willing to give up?
At the time, Mike Caulfield noted on Twitter that the question about who you are willing to let win was a particularly important one.
Fast forward to a couple of weeks ago. A fight broke out about the planned conference programming that was bad enough to have caught the attention of the Chronicle:
Less than two weeks before its 16th annual meeting, the Open Education Conference has canceled one of its keynote panels — “The Future of Learning Materials” — after facing a backlash on social media.
The panel, which had been scheduled for November 1, was slated to include representatives from Cengage, McGraw-Hill, Lumen Learning, and Macmillan, all for-profit publishing companies, as well as the managing director of OpenStax, a nonprofit. It was supposed to explore the potential role of traditional commercial entities in the future of open education resources.
“That role could be anything from ‘no role’ to ‘deeply committed participant,’” David Wiley, a member of the program committee and a co-founder of Lumen Learning, said in an email. Of the more than two dozen speakers and panels nominated for keynotes, the future panel was one of the top vote-getters on the program committee, he added.
But the reaction to the panel highlighted the often contentious relationship between advocates for open education resources and commercial publishers, as open resources expand in the learning-materials market. The outcry also raised broader questions about the politics of providing platforms to those with opposing views and social media’s tendency to amplify outrage. Many open-ed advocates pushed back against the framing of the panel and objected to elevating profit-seeking entities with a keynote and prescreening questions audience members could ask.
The conference’s program committee, comprising Wiley and 11 others involved in open education, said the decision to cancel had stemmed from “toxic behavior” on Twitter, adding that committee members had received “abusive and harassing” direct messages. Two panelists withdrew, according to a statement, and potential replacements declined to participate because of the tone of the discussion on Twitter. But some in the open-education community, both those who had pushed back against the panel and those who had stayed out of the discussion, said they did not see anything particularly troubling in the public posts.
Wiley declined to share copies of the direct messages that committee members had received, or to comment on their nature. Several committee members and panelists did not respond to requests for comment.
A Conference on Open Education Invited For-Profit Publishers to a Keynote. Then the Objections Began.
To be clear, this latest episode is a symptom of the crumbling coalition rather than the cause of it. Phil and I saw this kind of tension—and occasional acrimony—as far back as 2015, which is what caused us to warn about it. Here’s one quote from the Chronicle article which marks one end of the spectrum of disagreement:
In conjunction with the statement announcing the panel’s cancellation, the programming committee also released all of the questions that had been submitted to the panel. Of the 56 questions submitted, many were directed only toward the for-profit panelists and could be quite pointed. “Why should open-education advocates and OER publishers listen to the opinions of the commercial publishers, whose greed has directly caused the current textbook-cost crisis?” said one question.
Others took the position that, while they were open in principle to commercial publishers participating, some of those entities did not meet key standards for good behavior and good will:
Rajiv Jhangiani, associate vice provost for open education at Kwantlen Polytechnic University, in British Columbia, published a blog post outlining how he thought commercial entities had engaged with open education maliciously in the past, and how many of them were trying to improve how they work with the field.
“While this may seem like a tricky balance, I see it as quite straightforward to criticize openwashing” — marketing as open education without offering a fully open product — “by a commercial player while also recognizing positive developments from the same actor,” Jhangiani wrote. “You see,” he wrote later in the post, “I do want to have these discussions with commercial players. I am interested in a diverse and healthy commons, and I take no joy in skewering for-profit actors publicly when they perpetrate harm and lie to advance their bottom line.”
While it is not a 100% match, OpenEd coalition members’ views of this sort of question—who they are willing to let win (and under what circumstances)—tend to correlate with primary goals. On one end of the spectrum, those who see OER as a particularly effective tool for achieving their primary aim of improving quality of curricular materials (and therefore student outcomes) are likely to be most tolerant of commercial vendors whose tactics they don’t always agree with but who may contribute in multiple ways to improving student outcomes, both through OER and through other means. On the other end, coalition members with different primary goals tend to be least tolerant of the commercial vendors and less forgiving of their perceived bad behavior, in part because these advocates tend to hold a theory of change that is tied to correcting power imbalances. For example, the claim that the publishers’ “greed has directly caused the current textbook-cost crisis” entails the beliefs that the publishers have had all the power to control prices and that correcting the fundamental problem requires taking away power from the publishers. Different primary goals or different theories of change may lead people to different conclusions about who they are willing to let win under which circumstances.
Making matters more difficult, as OER moved from a fringe interest to a more mainstream trend, the balance of attendees at OpenEd has changed from a high percentage individual contributors who sometimes felt alienated from the decision-making processes in their home institutions toward a higher percentage of participants who came precisely to advance institutional initiatives. As is often the case in coalitional politics, it is impossible to completely separate the political from the personal. People attending OpenEd come with both their professional responsibilities and their personal convictions, which tend to be deeply enmeshed among people who are passionate about what they do for a living. As the coalition came under increasing tension from the changing mix in priorities, personal tensions were also bound to increase.
While I did not follow the public fight about the panel on Twitter and have no inside information about any private messages that were exchanged, Phil and I had both seen enough similar behavior by 2015 to have been concerned about whether this group would hold together over the long haul.
What may come next
As I have tried to say throughout this post, the current situation is not a signal of OER’s failure but rather a side effect of its success. Note that none of the three priorities I listed at the top of this post included “OER are intrinsically good and an end in themselves.” Even folks who tend to believe that openness is an important value that leads to other good things—and I count myself as one of those people—argue that a Creative Commons license is an end in itself. An open content license or, more broadly, a bias toward openness of various types can be useful in accomplishing a wide range of goals. And because interest in using OER has increased across a range of people who are pursuing different goals, it is no longer adequate to talk about “open education” and “open pedagogy” as nebulous things that we don’t all need to define and explicitly agree on because it is somehow obvious that we all agree enough. That simply isn’t true anymore, to the degree that it ever was true in the first place.
The OpenEd conference as we know it is dead because it represents a coalition that has, at least for the moment, crumbled under the weight of its own growth and diversification. What comes next will almost certainly be one or more attempts to either reconstitute the old coalition or build new ones—or, most likely, both.
I think it more likely than not that somebody will run a conference next year that will be called “OpenEd.” I also think it more likely than not that there will be one or more conferences—regional, national, and/or international—that attempt to build a new coalition that aligns more closely with one or more factions rather than trying to reconstitute the same blend as OpenEd as it has existed to-date. The efforts that succeed will be the ones that embrace the task of coalitional politics and develop a strategy that both recognizes the real differences among participating factions and develops an explicit strategy to attract and retain a coalition that can maintain alignment over time.
There will doubtlessly be OpenEd participants who passionately disagree with this analysis, and some who may even be angry over it. Unfortunately, that is new to neither OpenEd nor e-Literate. A public platform is a blunt instrument. Sometimes the only way to both ethically and effectively get a message across in a venue like a blog is to be plain spoken and independent-minded at the risk of offending friends.
The OpenEd coalition fell apart this week. It is not the end of OER or open education. But there are multiple paths leading forward from here. Finding the one that maximizes opportunities to do good will depend on the degree to which future coalition members are willing to take a hard look at what went wrong and learn from failures.
In a recent post, I wrote about my experience on the EDUCAUSE exhibition hall looking for vendors with proof that their products actually help students and how this is an example of the more general problem:
Right now, higher education has very poor signals to quickly distinguish between those vendors who can prove that their products are effective and those that can’t. Between those vendors who are contributing to the general state of knowledge about how to improve student success and those that aren’t. Until we can improve the signal-to-noise ratio, we are doomed to ride the roller coaster from hell that is the hype cycle until we pass out from exhaustion.
I’m going to do something about improving the signal-to-noise ratio, and I will be announcing what that something is within the next week.
Today I am pleased to announce the Standard of Proof ongoing webinar series, which attempts to do just that. The first is scheduled for November. But the plan is to have at least one a month starting in late January, after folks have returned from winter break.
How webinar topics are selected
For many years now, I have turned down requests to facilitate paid webinars because it’s very hard to do them without sliding down a slippery slope and either appearing to be a shill or actually crossing over the line and becoming one. And yet, I would like to give webinars that highlight genuinely good work, and I would like to get paid for my time so that I can afford to do this work.
The Empirical Educator Project (EEP) has given me a novel way to thread the needle. Vendors don’t pay me directly for a webinar. Instead, they sponsor EEP. I vet prospective EEP sponsors—they have to have something to contribute beyond just money—and I also price sponsorship to incentivize active participation and contribution. Standard of Proof webinars are now another incentive for vendors to contribute.
A Standard of Proof webinar is not an automatic benefit of EEP sponsorship. Each webinar is about not a company but a contribution to the work of empirical education. It can be, and often is, novel research conducted by the company that (a) contributes to our knowledge of how to help students succeed, and (b) adds to our knowledge in a way that is generalizable beyond their product or service. In other words, it is a contribution to the commons. But the contribution can also be a project that helps disseminate established research-backed practices or generally promote the culture of empirical education. A contribution should either be free if it has no maintenance costs or non-profit if it has does have a cost to maintain.
Contributions also have to have been developed with some meaningful collaboration with or peer review from academics. As with the definition of “contribution” above, I am more interested in the spirit of meaningful collaboration than in setting up narrow rules. But there has to be an academic who was involved enough in the project that she or he is willing to speak publicly about their participation and their views of the project.
While EEP sponsors are not guaranteed a minimum number of webinars in return for their sponsorship, neither are they limited to a maximum number. If they have made multiple contributions and I have time to cover them in the Standard of Proof schedule, I will. If that means running more than one webinar a month, I would be happy to have that problem.
The end goal here is to help vendors that meaningfully contribute to education differentiate based on those contributions. Providing credible evidence that their solutions support student success is part of that work, but the bar is higher than that. The webinar series title, “Standard of Proof,” refers not only to the products but to the vendors. The series highlights acts of good citizenship that promote empirical education. By raising the profile of these acts and the vendors who perform them, I hope to influence the criteria by which prospective vendors are selected and therefore their incentives for behavior.
Folks, this only works if you and your institutions decide that you will prioritize good behavior—including but not limited to credible proof that a product is effective—in your vendor selection. The most that I can do is help make that good behavior a little more visible.
The first webinar
As I wrote earlier in this post, the first webinar coming up later this month. I have two more lined up for early next year that I will be announcing at a later date and more in the pipeline.
Summer melt: A randomized controlled trial
We’ll be kicking off the series a randomized controlled trial by AdmitHub and its academic partners to advance our understanding of a critical phenomenon that influences the success of first-generation students.
Folks involved with admissions at access-oriented schools may be familiar with the term “summer melt.” It’s when students are admitted to a university, say they are coming, and then never show up. And it tends to be a first-generation student problem. There are all kinds of logistical and bureaucratic hurdles in getting from admissions to first day of classes that may be harder for first-generation students, either because the processes are not designed to accommodate their situations or because they don’t have anybody in their lives who can help them. Maybe they need an immunization certification and they don’t know how to get it. Maybe they need the signature of a parent who they don’t know how to contact. This is a problem that is often caused by a number of small contributing factors, and it is hard to diagnose because the people who know what kept them from coming to college…never came to college. So having a dialogue with them after the fact is difficult to arrange (not to mention unhelpful for the student, who has already missed an opportunity).
There are a number of products on the market, particularly machine learning-enhanced chatbots, that purport to address the summer melt problem. AdmitHub is one of them. But rather than just claim that they can help, they collaborated with their major customer, Georgia State University (GSU), and an academic researcher from the University of Pittsburgh who studies summer melt, to conduct a rigorous study of the impact of the AdmitHub-enabled interventions on summer melt at GSU. The results of the study? GSU was able to reduce summer melt by 20% using AdmitHub.
In addition to providing credible evidence for the product’s effectiveness, this study’s results and experimental design both contribute to our general knowledge of summer melt. We’ll be talking about that as part of the webinar, which will include the PI Lindsay Page from Pitt as well as Tim Renick from GSU, who happens to be a personal hero of mine.
Now that Coursera for Campus—which I have occasionally erroneously referred to as “Coursera for Schools” in previous blog posts—has been launched, we have some more information about what it’s really about. (I’ll embed the launch video at the bottom of the post, but if you’d rather go straight to it, you can find it here.) I think it’s significant and portends significant trends in the sector.
Before we get to that, let’s get one item of business out of the way related to my previous posts. As IBL Education notes, Coursera CEO Jeff Maggioncalda said, “Coursera for Campus is not a full-featured LMS. We expect many universities to stay on their LMSs.” IBL News further notes, “According to the company, Coursera for Campus’ LMS is designed to supplement the existing Canvas, Blackboard and Moodle systems.” [Emphasis in original.]
So Coursera for Campus isn’t LMS play, at least for the foreseeable future. I was pretty harsh on Coursera’s SVP of Enterprise Leah Belsky for her disruption language, but as I’ll get into later in this post, this kind of category mistake is actually quite easy to make and one that other courseware providers have made.
Because that is exactly what Coursera has explicitly become with their Courseware for Campus offering: a courseware provider. The less obvious part is that MOOC design and courseware design have been converging for some time now. Their increasing similarities in instructional affordances have been masked by the differences in the business models of their parent companies. And even less obvious is that the Venn diagram of courseware companies and OPM companies is starting to overlap significantly.
“A 21st-Century textbook”
In the launch presentation, Maggioncalda called Coursera for Campus, in part, a “21st-Century textbook.” Take that seriously. These are MOOCs repurposed as curricular materials. And it’s really not that big of a leap. Remember that the pedagogical model of the xMOOC course generally doesn’t require heavy participation from the instructor. Some instructors do participate heavily, while others, less so. A lot of instructor energy goes into course design and lecture video production. The actual live support could be from the instructor, but it also could be from TAs, or it could be self-study. Or, in the case of Coursera for Campus, it could be a different instructor. From its inception, the design model of xMOOCs began decoupling faculty course design from faculty course delivery.
There is some messiness, of course. The biggest challenge in terms of textbook-like may be the lecture videos. Faculty may not love having some other personality featured as the star of the show. But there are two mitigating factors to that. First, Coursera’s design staff is likely guiding faculty toward authoring instructionally sound videos, which would tend to reduce the total amount of talking head content in any given course. Second, textbook-provided commercial courseware, which is still often written by star authors in their field, now also features talking heads. Here, for example, is the Cengage MindTap introductory video for Economics, by author Greg Mankiw:
Greg Mankiw’s head, talking
“But,” you may be thinking, “MOOCs are not designed like courseware.” One of my Twitter followers made a comment to the effect that at least courseware has an instructional design philosophy, unlike xMOOCs.
That person is mistaken, and here is the proof:
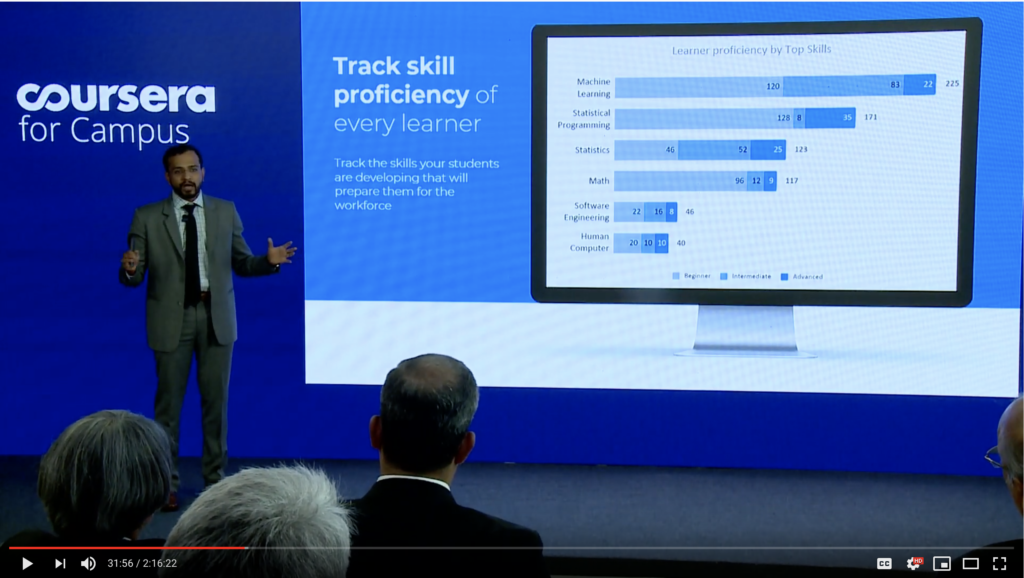
These analytics are only possible with backward design
During the launch presentation, a Coursera executive made the statement that “any of the courses that have been authored on Coursera come with an out-of-the-box analytics platform.” If those analytics look anything like the picture above—and I would bet money that they do—then the courses have been built on a backward design philosophy like the one I have been describing in my recent post series on content as infrastructure.
This shouldn’t be surprising. As I wrote repeatedly throughout that series, almost every professionally designed course uses that design pattern. And Coursera is known for having strong professional course design support.
(I’m telling you, folks. That content pattern is the revolution of our time.)
Update: Matthew Rascoff has reminded me to acknowledge that the professional course designers on campuses play large and critical roles in the design of these courses. The larger point is that, on both sides of the fence, there are trained, professional course designers who are applying this design pattern.
While I haven’t looked at their catalog myself in quite some time, I would not be surprised at all if many of their offerings stack up pretty well against commercial courseware titles. For one thing, while xMOOCs have a bad reputation for anemic social interaction relative to other course models, they probably have more social interaction designed into them than many commercially published courseware titles.
Courseware platforms vs LMSs
It’s easy to get confused about the boundary between a courseware platform and an LMS. I know because I have worked on and consulted on both. The LMS companies inevitably start thinking, “Damn, there are so many courses that get delivered through our platform, and so much money made on selling them. And guess what? Everything that faculty build and deliver through our product is a course! The textbook publishers keep rebuilding what we’ve already built. Badly. I mean, have you seen their grade books? Why can’t we be the platform and get a cut of all that money?”
So they try to displace the publishers. And they fail. Every time.
The textbook publishers, meanwhile, start thinking, “Damn, our customers really hate their LMSs. We’ve built all these LMS features, and they keep asking for more. I mean, we’ve already built a grade book. Wow, that was painful. Why can’t we be the platform and get a cut of all that money?”
So they try to displace the LMS companies. And they fail. Every time.
Here’s the critical difference:
LMS developers have to optimize for a wide range of faculty preferences, teaching styles, and teaching conditions. They have to accommodate every grading scheme imaginable. They have to handle huge classes and tiny classes. They have to deal with face-to-face, online, and blended. Constructivist, lecture, and whatever else. That’s why they spend so much time adding grade book micro-features and then optimizing the usability to handle all those micro-features without being totally overwhelming.
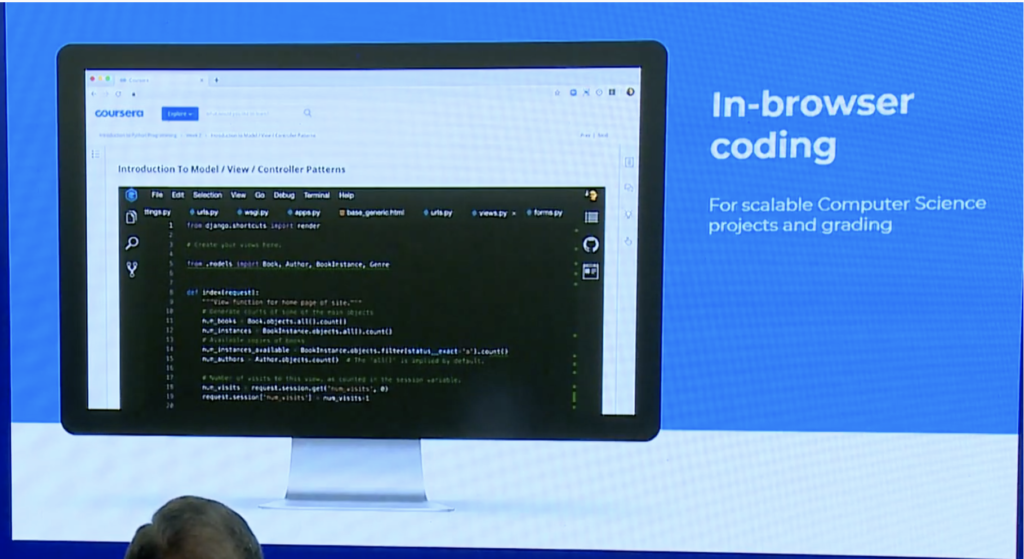
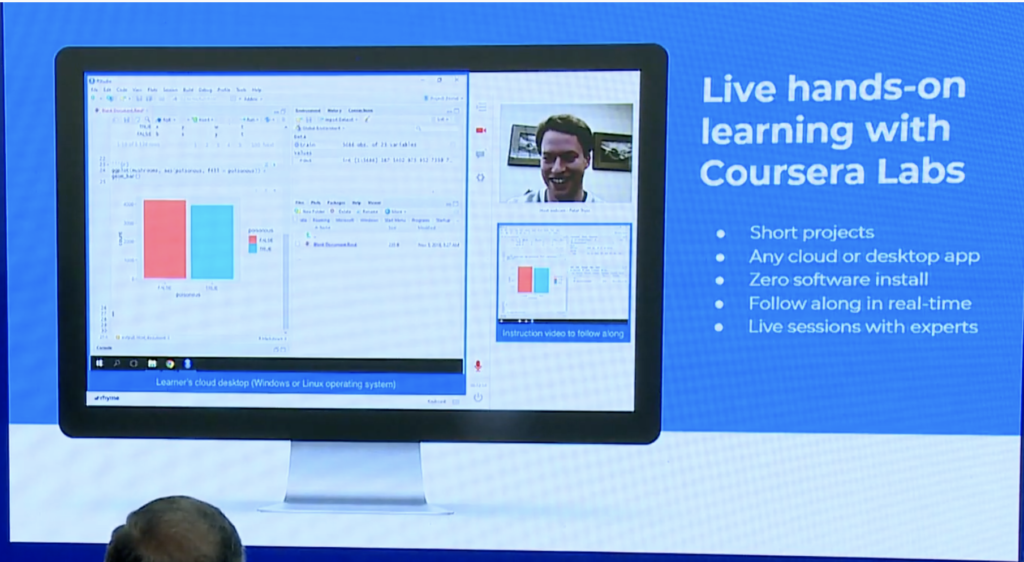
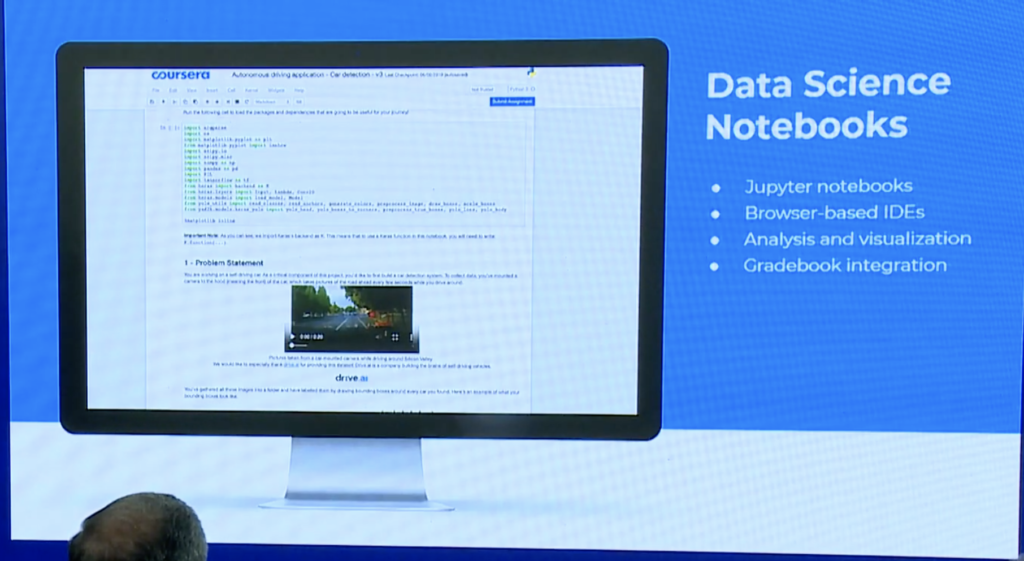
Courseware developers, in contrast, have to optimize for the content. If the subject is software development, then you need an interactive code editor and test engine. If it’s accounting, then you need a test engine that looks like a spreadsheet. If it’s chemistry, then you need a molecule visualizer and manipulator.
Which side of the divide do MOOC platforms land on? Here are a couple of slides from the Coursera on Campus launch:
These subject-specific affordances, plus competency-based analytics, were the platform highlights of the Coursera for Campus presentation. Not the grade book that can do anything. Not the test engine that can provide any kind of feedback. Not announcements or an event feed. This was all about courseware.
“But wait,” you say. “Courseware for Campus lets faculty author their own courses. Isn’t that different?”
Yes. And no.
Way back the better part of a decade ago, when I was at Cengage working on the MindTap platform, the company debated whether to open it up to customers and license it without content. (“We can disrupt the LMS!”) In the end, there were two major barriers. First, as a print-centric company in the midst of a transition, the authoring tools were not remotely faculty-friendly. And second, as a publisher whose bread and butter came from royalties, there was a fear of cannibalization of the business.
Coursera has neither of those problems. It was born as a two-sided market, which means that it never owned the content to begin with and always had an incentive to make authoring as easy as possible. It may have taken some time to fully realize that vision, but we were destined to arrive where we are now.
Further, as textbook publishers increasingly move away from celebrity franchises and toward fee-for-service contracts with their authors, they will have motivation to make similar moves. McGraw-Hill Education doesn’t advertise it widely, but they have been licensing the authoring platform for SmartBooks for several years now. Authoring support can work with a courseware platform as long as the range of course expectations for delivery models can be constrained. And MOOC courseware fits the bill. It’s a genre.
Coursera for Campus is a harbinger of the future, not for the LMS industry but for the textbook industry. And they are an early mover with certain advantages in their business model.
The courseware/OPM convergence
One critical element that I don’t want to lose in all of this is the implications for the OPM market. Let’s not forget that (a) Coursera has been pushing into that market aggressively and successfully and (b) that market has been under massive pressure and upheaval lately. 2U has been the canary in the coal mine, having lost roughly four fifths of its market value since the beginning of the year. ((Disclosure: 2U is a 2019 sponsor of EEP.))
To be clear, I think there’s some noise obscuring the signal. Two of the reasons why 2U took such a big hit are that the stock got way ahead of itself and some self-interested players have been extraordinarily successful at generating FUD around the market category in general.
That said, there is no question that the hype around selling an infinite number of $40K masters degrees has met its demise. There are two barriers to OPM growth, which is another way of saying that there are two barriers to conventional online degree growth, and they have both proven formidable barriers to crack. The obvious one is cost. The less obvious one is geography. It turns out that, even in an era when people can take courses from anywhere in the world, they will tend to take them from their local institution or not at all. For all the talk of “national universities” and “mega universities,” it’s not clear that such beasts really exist. For the most part, big universities have proven exceptionally good at soaking up every ounce of demand for education in their local areas. So the next sustainability play is not so much about reaching students far away as it is about serving students you already reach for 40 years rather than for four.
And interestingly, that is essentially the pitch that the Coursera executives made about Coursera for Campus—even when they were pitching in India. They weren’t making the pitch that the American stereotype would have predicted, of reaching the rural millions. They were talking about lifelong learning. Skilling and reskilling. From an OPM perspective, this pitch gives the company with the large catalog of low-cost and constantly refreshed inventory a competitive advantage.
That said, there was definitely a bit of hand waving going on regarding completion rate. The Coursera executives talked about University of Illinois’ degree program as having over a 90% completion rate as if that remarkable achievement could be solely attributed to the fact that it was a degree program. I suspect there are some hard-working support staff at the University of Illinois who might quibble with that clean of a causal analysis. I don’t think the Coursera folks are directionally wrong, and I don’t think they were intentionally misleading, either. But I do think that they oversimplified, and that running a highly successful program at scale with a 90%+ degree completion rate entails a lot more than just handing out a piece of sheep skin at the end. The reason I bring this up is not because I want to snark on Coursera but because the part that is being glossed over represents a number of support areas that OPMs compete on (and that more traditional OPMs and OPEs pride themselves on excelling at).
The gap between “MOOC” the course model and “MOOC” the courseware model is very much an open question in terms of student success. The MOOC courseware model, particularly as implemented into affordable degrees at scale delivery models by pioneers like Georgia Tech and University of Illinois, are creating an alternative delivery model that could start putting pressure on OPMs supporting more traditional models. Coursera on Campus, in addition to creating an additional revenue stream for the company and putting pressure on courseware providers, potentially ups the ante in the OPM market. But we need to look to those universities which are pioneering affordable degrees at scale to understand the service gaps, marketing gaps, and cost differences between MOOC courseware and the totality of what they are doing in order to understand the what it would take to replicate their success.
In the meantime, consider the implications of the Coursera on Campus model for the future of companies like Pearson and Wiley, which own both courseware and OPM divisions, or McGraw-Hill Education, which has begun experimenting with opening up its platform for content authoring by customers. ((Disclosure: Pearson is a 2019 sponsor of the Empirical Educator Project.)) It’s not necessarily all bad, but it is a potential accelerant to change that is already in the wind.
It’s a wild, wild, wild, wild world, my friends.
Here’s the full launch event for your viewing pleasure:
Matthew makes some valid points, both here and further down in that thread. So I thought it would be worthwhile to take a moment to clarify a couple of the finer points of my post.
First, I absolutely agree that there is a long-running narrative of “MOOCs are dead” that is not productive. My intention wasn’t to reiterate that narrative but rather to say that, given the very evolution of what is “coming next” that Matthew is interested in, the term “MOOC” itself has become meaningless. Design and usage of “MOOCs” have fragmented in really substantial ways as people have learned and tried new things. To call Georgia Tech’s Affordable Degrees at Scale, ASU’s Global Freshman Academy, and the new Coursera on Campus initiative all “MOOCs” or “MOOC-based” is to paper over the critical differences among them that are exactly the experimental factors that we should be attending to. Of these three programs, only Global Freshman Academy was something close to what I would call a MOOC in the original sense.
The point isn’t to get into an academic debate (in the pejorative sense) over a term definition but rather to understand that there are very different kinds of experiments being run. The success or failure of one of these tells us very little about the prospects of the other two. When we call everything a MOOC, we obscure the differences among the experimental conditions and the possible reasons for the different results that are coming in from them. There are lots of interesting experiments happening on MOOC platforms right now. I’m not sure how to tell what works and what doesn’t because we’re not using precise language to disambiguate among the experiments. Die-offs are part of evolution, and we’re trying to understand the process of natural selection.
Second and somewhat separately, I have a bugaboo about the term “disruption” being casually thrown about by ed tech companies. Disruptive innovation is a theory of change. We have lots of data about how the LMS market in particular changes—or doesn’t. At one point, Moodle was supposed to be a disruptive innovator. At another point, OpenClass was supposed to be the disruptive innovator. Both competed against non-consumption with a cheaper, simpler solution. Both got soundly beaten in developed markets by Instructure Canvas and, later, by other commercially hosted cloud-based solutions. There is no particular reason to believe that disruptive innovation works as a theory of change in the LMS market.
Further, if you’re going to claim to be ready to “disrupt” a product category, then you damned well better have good understanding of the needs of the customers in that product category. It’s a matter of respect. There is a long history of vendors failing to show proper care in this regard, which in turn has created trauma and fostered dysfunction on the part of universities going through a procurement process. Those universities tend to develop a cynicism which, at its worst, manifests as a corrosive political nihilism in their approach to picking a product.
Vendors have a responsibility to the sector to be humble. I don’t have any problem at all with Coursera’s ambitions for their Coursera at School offering, at least as far as I understand them. I do have a problem with the way that their executive characterized those ambitions in the EdSurge article. I think the language of disruption is both counter-productive for Coursera and harmful to the kind of conversations we want to foster in general about evaluating innovative offerings. As I said in my original post, it is long past time for companies serving the education market to strike that word from their public vocabularies.
In general, I am spending less time picking at vendor language in this new incarnation of e-Literate, as I try to focus on incentivizing good behavior rather than punishing bad behavior. That especially applies to vendors using unfortunate but relatively inconsequential language. What Coursera is doing is generally much more important that what they are saying about what they are doing. That said, there are times when patterns of language use are genuinely harmful and need to be called out, not to punish a bad actor but to put a halt to counter-productive behavior that retards progress in the sector. This is one of those times.