e-Literate

Present is Prologue

Author: Michael Feldstein

  • Content as an Instrument of Inquiry

    If you’re not writing clearly, then you’re not thinking clearly.

    Mrs. Galligani (My high school English teacher)

    In response to the posts so far in the series, John P. Mayer, Executive Director of the Center for Computer-Assisted Legal Instruction (CALI) tweeted,

    “This article mirrors what @caliorg Lessons are about – and have been for almost 40 years.”

    In the first post of the series, I explained the basic logic of the content design pattern to which John is referring:

    1. Start by articulating what you are trying to help students to learn as clearly as you can.
    2. Then figure out how you are going to be able to tell (or “assess”) whether the students students have, in fact, learned what you are trying to help them learn. Again, be as clear and explicit as you can in this.
    3. After you have taken the first two steps, then design learning activities—reading, watching, discussing, experimenting, and so on—that you believe will help the students to learn what you are trying to help them learn.
    4. As you design these activities and the content that makes it possible (e.g., readings for the reading activity), be sure to embed little low-stakes exercises throughout so that you and the students can track their progress toward learning whatever it is that you are trying to help them to learn. And, if necessary, to adjust the teaching or learning strategies.

    It’s not exactly rocket science.

    In the second post, I showed that we could derive pedagogical benefit when we formalize this content design pattern in digital curricular materials. If every bit of content and every assessment item is labeled with a particular learning objective (or learning goal), then we can track various kinds of student progress toward that learning objective. Have they started any activities related to that learning objective yet? Have they finished them? How well are they scoring on the assessment measures for that particular learning goal? How are they progressing through the stack of learning objectives that make up a larger curricular unit? Are any students stuck on one particular goal? Is the whole class stuck? We can get clearer answers to these questions, for ourselves and for our students by creating well-crafted curricular materials in the design pattern that I described above and creating very simple software capabilities for showing how students are performing on the assessments. Call this much “analytics” is a stretch. Statistical algorithms are optional and often superfluous to get us this far. We’re really just colating and visualizing the student activities and assessment results in ways that the content design enables us to do. In tech speak, we would call these “dashboards” and “visualizations” for the “data.” But your paper grade book (if you still use one) is a dashboard for the same data in a somewhat similar way. Honestly, once you throw in grading on curves, different point schemes, dropping the lowest score, and so on, some instructor grade books are algorithmically more complex than many of the courseware affordances I showed in my last post.

    The value of having many examples

    So far, I have been writing about the content design pattern as a tool for getting the most out of self-study curricular materials. That is still a good frame of reference for thinking about courseware or courseware-like content as static tools for teaching. But this content design pattern also has great value—in the long run, perhaps greater value—as a tool of inquiry for educators who want to improve their teaching craft.

    And this is the moment where I reveal my not-so-hidden agenda.

    My altar ego, Montgomery Burns

    If you thought this series was about courseware, then you were (mostly) wrong. If you thought this post was going to be about machine learning and algorithms and adaptive learning, then you were also (mostly) wrong. I will touch on those topics, but they are means to an end.

    And that end is to talk about increasing literacy and fluency among faculty in evidence based, digitally-enabled pedagogy. Just as the proliferation of commercial courseware provides us with a wide range of examples of professionally designed content which we can study to learn more about trends in curricular materials designs, the proliferation of analytics and adaptive learning provides us with an increasingly wide range of examples of professionally constructed analysis and inference techniques which we can study to learn more about current trends in such techniques.

    We have an ever-growing library of implementations—good, bad, and ugly—which educators could be studying and learning from if only the pedagogical design and function were not either opaque or invisible to them. Forget about the products as products for a minute. Set aside your feelings about the vendors for a moment too. We have digitally-enabled or enhanced teaching design patterns that have been evolving for at least 40 years. We are now are at a point where those patterns have reached critical mass, are proliferating at a rapid rate, and are being employed by academic and commercial course designers alike.

    Somebody should tell the faculty, don’t you think?

    The Empirical Educator Project (EEP) is going to undertake a major literacy effort to help increase awareness, literacy, and fluency in this design pattern, aided by some of the tools that Carnegie Mellon University has made available as part of OpenSimon and by the efforts of the wonderful people and organizations in the EEP network. I’ll have more to say about these efforts in the coming weeks. but for now, I am using this series to explain why I believe this is a fruitful area for educator literacy efforts.

    And it ain’t just about building a better textbook.

    Pedagogy as hypothesis

    Have you ever had one of those days where your carefully crafted lesson doesn’t go the way you thought you did? If you haven’t, then either you haven’t taught much or you’re doing it wrong. Because, given sufficient time in the classroom, every self-aware educator is going to have this experience. Something that you thought would be easy for the students turns out to be hard. An explanation that you thought was crystal clear confuses them. You thought the students were following along great until they bombed the unit test.

    In the classroom, most educators experience these problems and make adjustments as needed. They may not test for these problems programmatically. They may not conduct formal experiments to fix problem spots in their courses. But many, many educators do this in some form to some degree. Whether consciously or unconsciously, deliberately or instinctively, they are teaching by hypothesis. They think something will work, test it, and if they are wrong, they will try something else. Teaching isn’t assembly line work. It’s knowledge work. Done right, it requires an endless amount of creating problem-solving and tinkering.

    In the days of analog textbooks, it was a lot harder to do this kind of tinkering with student self-study work because educators were mostly blind. They couldn’t see what students were doing and they often didn’t even get to directly observe the results. They almost never got a chance to create a rapid feedback cycle with individual students to try a few different things and see what works. That changes with digital—if you have the right content design.

    As with the last post, I’m going to show some examples from Empirical Educator Project sponsors to show this content design pattern makes new teaching insights possible in a digital environment.

    Is your content working?

    Suppose you want to find out if the content in your digital curricular materials is actually helping students to learn what you are trying to help them learn. You could look at page views and other Google Analytics-style information to see what content students are spending time on. And you could look at the assessment scores. Take a moment and think about what you could learn from those two pieces of information.

    Eh, not much.

    Now suppose your curricular materials were created using backward design. For each content item, you know which assessment questions it is designed to prepare students for and which learning objective it is ultimately designed to teach.
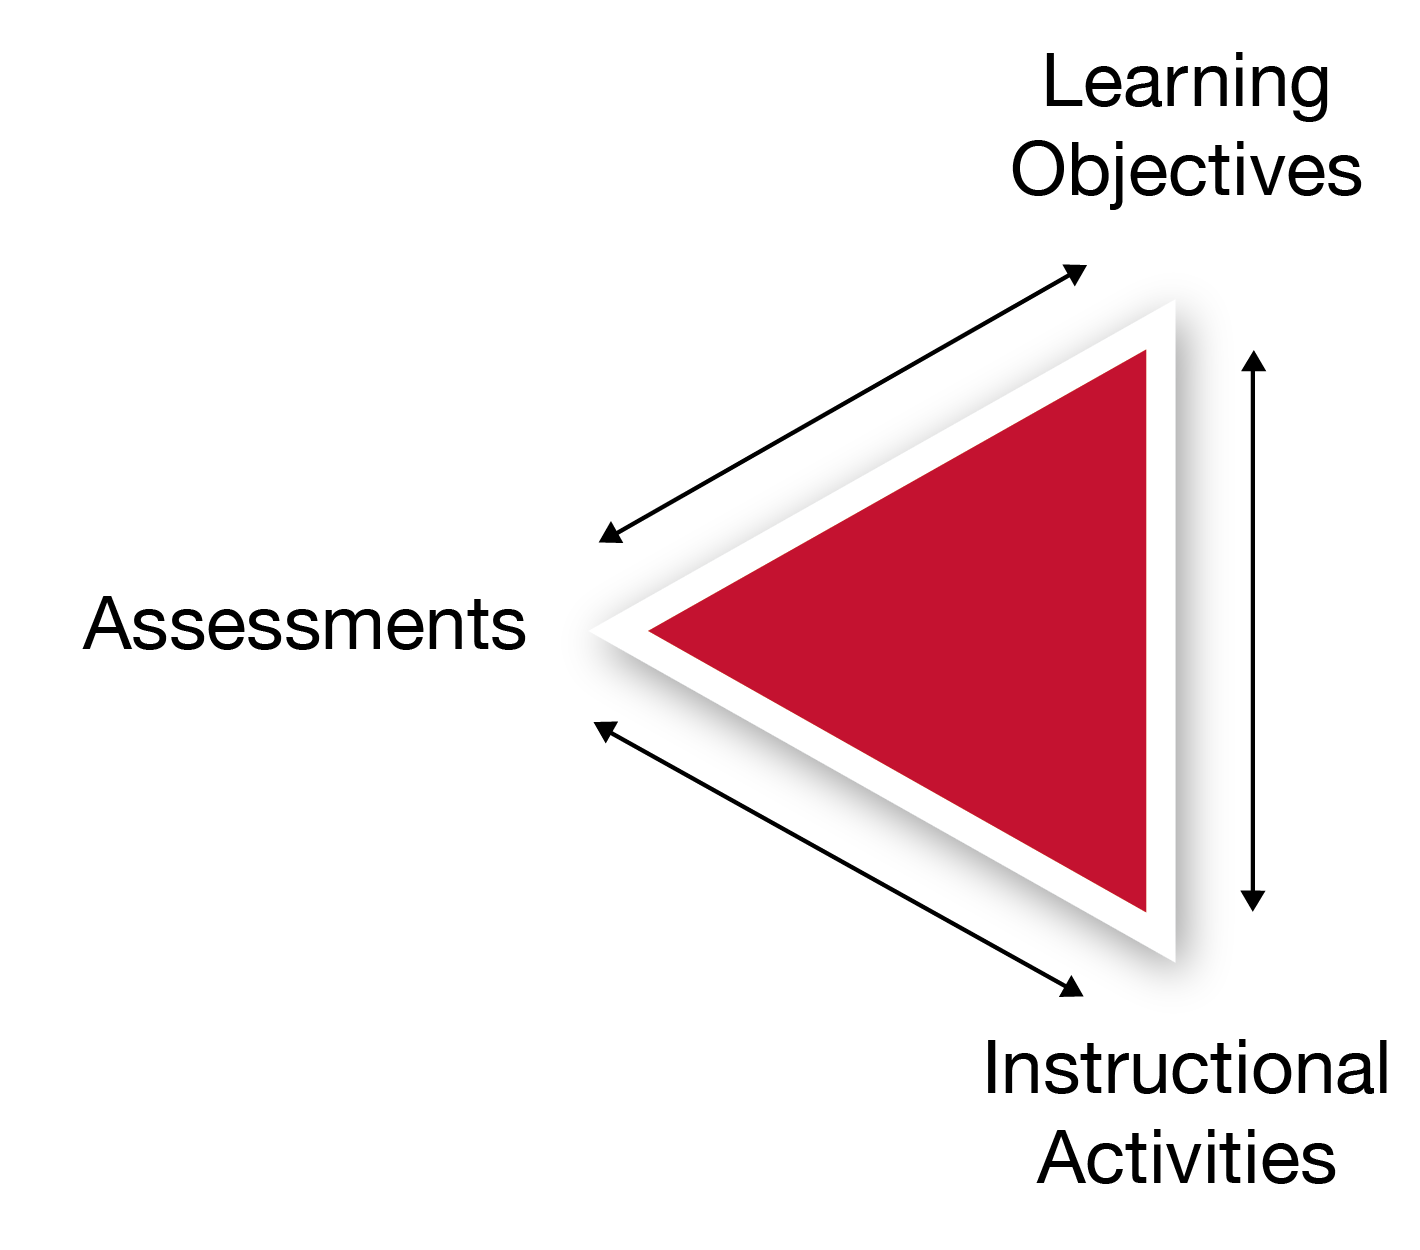
    The golden triangle of instructional design

    You now have the ability to link page views to assessment data (and both to learning goals). Did your students spend a lot of time on a piece of content and still perform poorly on the associated assessments? Then something probably wrong with your design. Did they score well on the assessments while skipping over the associated content? Again, there’s a potential opportunity for improvement.

    What I’ve just described to you is the essence of the RISE framework, which was developed by Lumen Learning. As I described in a previous post, Lumen worked with Carnegie Mellon University to integrate RISE into one of CMU’s open source learning engineering tools. Now, anyone using any platform that can export data about page views and assessment items that are associated with a particular learning objective can generate a simple graph with page views on one axis and assessment performance on the other. It’s a simple and intuitive tool that any educator could use to get insights into whether their curricular materials are as effective as they could be. At last spring’s Empirical Educator Project (EEP) summit, Lumen and CMU demonstrated this process working using content from D2L Brightspace.

    Here’s a panel discussion we had about RISE and CMU’s OpenSimon LearnSphere at the EEP summit:

    RISE and Shine panel at the 2019 Empirical Educator Project summit

    Note that the content doesn’t fix itself through the magic of machine learning. Rather, RISE helps educators focus their attention on areas of potential improvement so that the humans can apply their expertise to the problem. This is true even in the most sophisticated commercial products. However fancy the algorithms may be, behind the scenes, experts are using the data to identify problems that still require humans to solve.

    Publishers that really understand the digital transformation have subject-matter experts who are pouring over the data and making changes on a regular basis. When Pearson announced that they would be moving to a digital-first model so that they could update their products more frequently I wrote,

    [I]n the digital world, there are legitimate reasons for product updates that don’t exist with a print textbook. First, you can actually get good data about whether your content is working so that you can make non-arbitrary improvements. I’m not talking about the sort of fancy machine learning algorithms that seem to be making some folks nervous these days. I’m talking about basic psychometric assessment measures that have been used since before digital but are really hard to gather data on at scale for an analog textbook—how hard are my test questions, and are any of the distractors obviously wrong?—and page analytics on the level that’s not much more sophisticated that I use for this blog—is anybody even reading that lesson? Lumen Learning’s RISE framework is a good, easy-to-understand example of the level of analysis that can be used to continuously improve content in a ho-hum, non-creepy, completely uncontroversial way.

    It would be irresponsible for curricular materials developers not to update their content when they identify a problem area. It would be like continuing to give a lesson in class when you know that lesson never works. But the main point here is that the software helps the human experts perform better. It doesn’t replace them.

    Are your assessments working?

    Just because students are looking at a piece of content and still scoring poorly on the related assessment items doesn’t necessarily mean that the problem is with the content. What if the assessment questions are bad?

    Psychometricians developed statistical methods for evaluating the quality of assessments many decades before the advent of digital courseware. The term of art for the most widely used collection of methods is “item analysis.” Item analysis tools have been built into most mainstream LMSs for quite some time. (If I recall correctly, ANGEL was the first platform to do so.) Here’s an example of an item analysis graph from Brightspace:
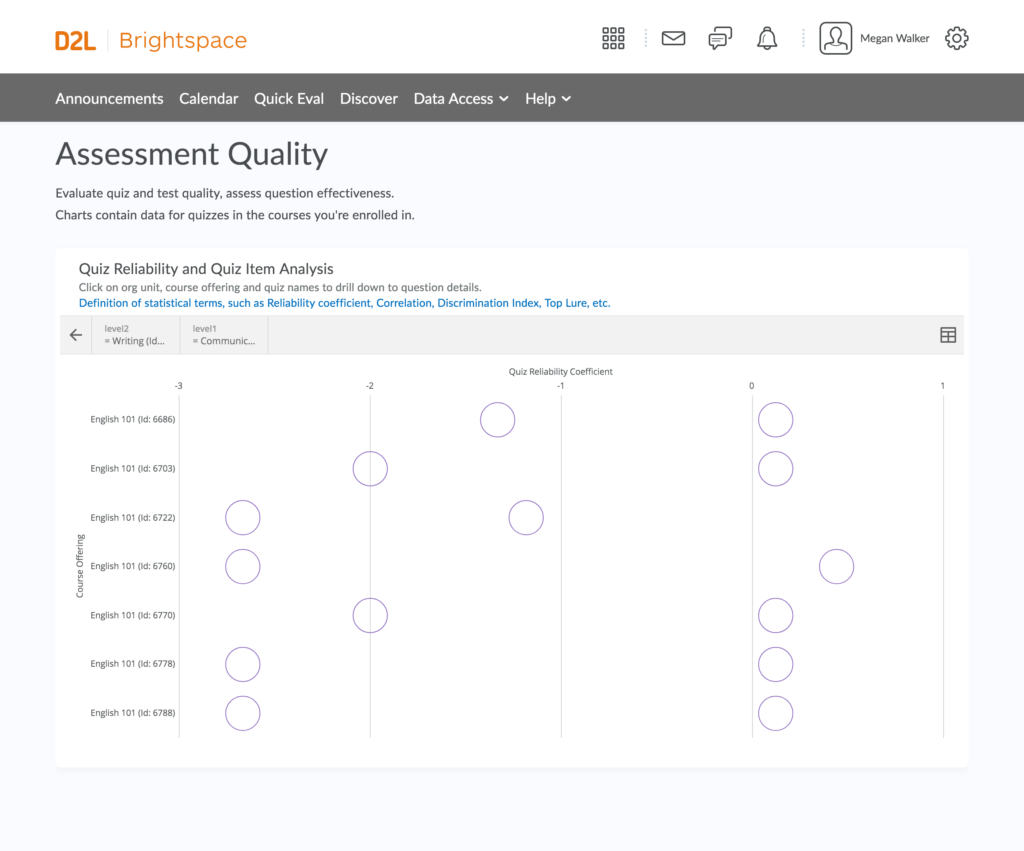
    Brightspace item reliability visualization

    This particular visualization is showing the results of something called a “reliability coefficient.” It tells you how consistent the student answers are to questions within an assessment. I’ll ask you again to think for a moment about how useful that measure would be by itself.

    Now think about how useful it would be to see how consistent student answers are to questions about one particular learning objective. The more interrelated questions are within a group of questions being evaluated this way, the more consistent the student responses should be. If all of the questions assess mastery the same learning objective, then performance across those questions should have a fairly high degree of internal consistency. Yes, some questions may be harder than others. But there should be an overall pattern of consistency among the student answers to questions assessing the same learning goal. If there isn’t, then there may well be something wrong with the assessment.

    And speaking of difficulty, item analysis does provide the ability to assess the difficulty of questions relative to each other. When you design questions to assess a learning goal, you may deliberately write some questions that you believe will be trickier than others. But you may not always be right about that. Sometimes students can get tripped up by the design of question, making it more difficult than you anticipated. Or maybe you unintentionally gave a clue to the answer in the design of your question. Or maybe there’s nothing wrong with your individual questions per se, but the overall difficulty of them for one learning objective is higher than it is for the others in the unit. Or lower. Wouldn’t you like to know those things? Well, you can. Your LMS probably has the tools to help you learn these things about assessments within the LMS. But those tools are a lot more useful if you have grouped your assessment questions by learning objective.

    Are your learning objectives working?

    Maybe the reason that the students are struggling isn’t because your content is confusing, or because your assessments are poorly designed, but because the learning goal you’re assessing isn’t as well defined as it could be. Sometimes you discover that what you think of as one skill actually contains a second skill or knowledge component that you take for granted but that is tripping students up. Here’s how Carnegie Mellon University professor Ken Koedinger puts it:

    Ken Koedinger on hidden prerequisites

    If you have that problem, then there should be evidence in the assessment data. Students who are taking well-designed assessments that cleanly assess one learning goal should show improved performance on assessment questions over time as they progress toward mastery. Here’s an example of what Carnegie Mellon University calls a “learning curve,” showing exactly that trend in student performance in their OLI platform:
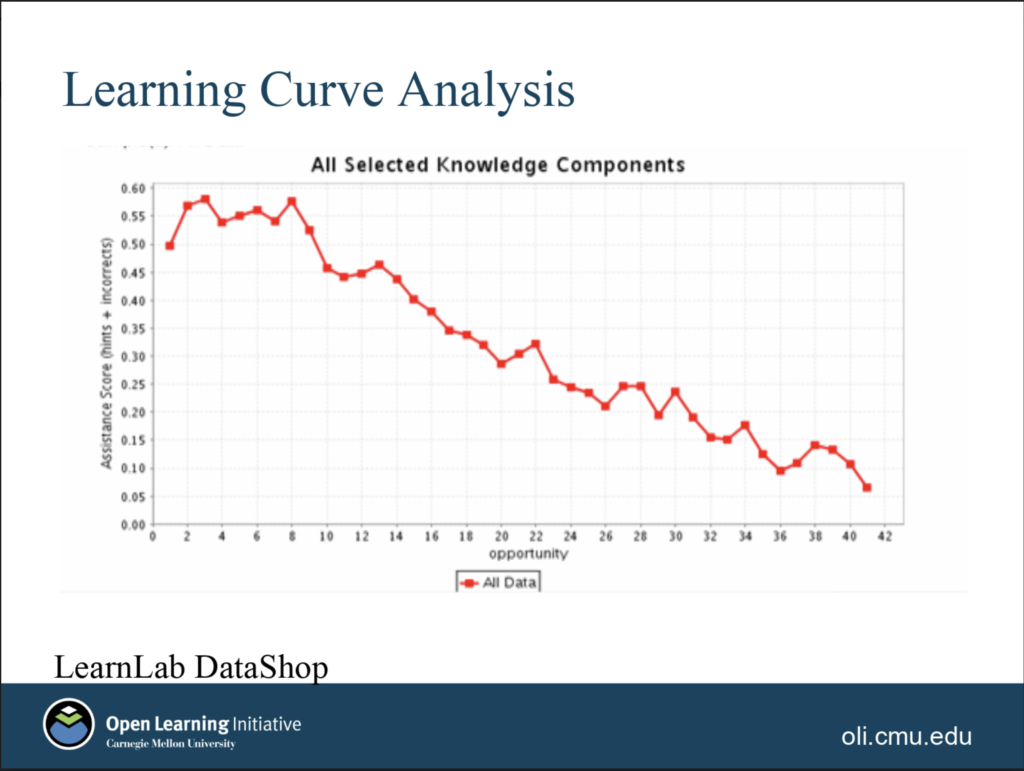
    OLI learning curve

    But what if your learning curve looks like one of these?
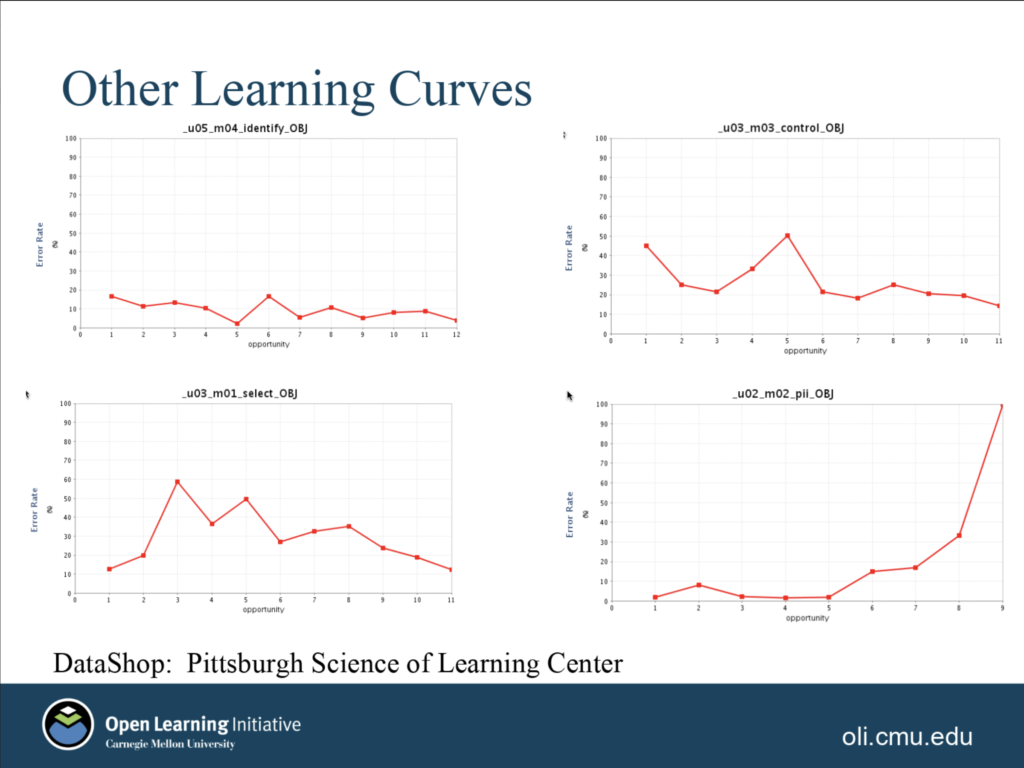
    Anomalous learning curves

    See the blip in the graph on the top right? That could suggest that one or more questions snuck in that test something other than just the intended learning objective. (Or they could have been poorly written questions.) The graph on the top left, on the other hand, may show that students have already mastered a learning objective, or that the questions are two easy. If you take some time to look at each of these graphs, they may suggest different questions to you about your curricular materials design. All of this is possible because assessment questions have been linked to learning objectives in the content design. And again, the solution when one of these anomalies appears is generally to have a human expert figure out what is going on and improve the content design.

    Are your scope and sequence working?

    Implicit in that last section is the notion that it’s possible for even good, experienced educators can miss prerequisite skills in their course designs from time to time. Very often, the algorithms behind skills-based adaptive learning platforms are testing for missing prerequisites. In the marketing, the emphasis is placed on the software’s ability to identify prerequisite skills that individual students may have missed along the way. But it’s important to understand what’s going on under the hood here and how it affects the content design and revision of these products by the human experts. One of the things that this type of adaptive software is really doing is finding correlations between students doing poorly on one skill and them doing poorly on prerequisite skills. In some cases, the prerequisites are well known by the content designers. In those situations, the software is checking to see if the student is struggling on a lesson because she needs to review a previous lesson. In these cases, the “adaptive” part of adaptive learning means that the system automatically provides students with opportunities to review the prerequisite lessons that they need to brush up on. ((This is not the only way that adaptive learning products can work, but it is a common approach.))

    But sometimes the software identifies a correlation between a skill and a previous skill that either the content designers weren’t fully aware was a prerequisite or did not realize how important of a prerequisite it is. The analysis shows that students who struggle to learn Skill F, perhaps surprisingly, often didn’t do so well with Skill B.

    Unfortunately I don’t have any screen shots illustrating this—maybe somebody reading this will send me one—but it’s an easy enough idea to grasp. And once again, the algorithms that drive this analysis only work when content is designed such that assessment questions are tied to specific learning objectives.

    Is your classroom pedagogy working?

    Now I’m going to explore a theoretical affordance made possible by this content design pattern. It’s not one that I’ve seen implemented anywhere. But we can get the outlines of it by looking at Pearson’s efficacy report and educator guide for their Revel psychology product. (Reminder: Pearson has paid me to consult for them on how to make their efficacy reports, including this one, as useful as possible.)

    One of the main efficacy measures in Pearson’s study was, essentially, the size of the improvement students showed from their formative assessments to their summative assessments. This was measured in a class where a professor was implementing specific pedagogical practices that are often lumped together under the heading “flipped classroom.” Teasing this out, we would expect students to experience some benefit from the formative assessments and the curricular materials themselves, and some benefit from the professor’s teaching practices that helped students take maximum advantage of what they could learn about their progress from their formative assessment performance that the courseware was giving them.

    Let’s think about the performance improvement measured in this study as a kind of a benchmark. It shows how much of benefit a class could experience given a particular set of teaching practices and students that tend to take that sort of class in that sort of university using that particular curricular materials product. What you might want to do, as an educator who is interested in active learning and flipped classroom techniques, is evaluate how much of an influence your classroom practices have on the benefit that students can extract from the formative assessments of the product.

    If both the formative and summative assessments are tagged with the same learning objective, then it should be possible to give every instructor with a gauge like the one that Pearson had to create in order to measure the impact of their product under close-to-ideal conditions. But we’d be flipping the analysis on its head. Rather than controlling for the teaching methods to measure the impact of the content, we’d be controlling for the content in order to measure the impact of different teaching methods. Instructors could try different strategies and see if they increase the benefit that students can get from the formative assessments.

    Yet again, this possibility for creating innovative “learning analytics” is becomes apparent once you do some hard thinking about the simple content design pattern and all the different kinds of insights that you can extract from implementing it.

    For the techies reading this, the lesson is that the value of educational metadata generated by human experts for the purpose of supporting their own thinking will exponentially increase the potential for your machine learning algorithms to generate useful educational insights. By itself, even the most sophisticated machine learning techniques will have sharply delimited applicability and severely limited value in a semantically impoverished environment. My favorite high school English teacher used to admonish, “If you’re not writing clearly, then you’re not thinking clearly.” Something like the inverse could be said for learning analytics. Clear writing is not evidence of clear thinking but rather the prerequisite for it. If the content authors do not provide the algorithms with indications of pedagogical intent, then the algorithms will not have the cues they need to make useful inferences. If content is infrastructure, then content metadata is architecture. It is a blueprint.

    For the educators in the audience, I hope it’s clear by now that this design pattern, which is ubiquitous in commercial digital curricular materials and quite possible to implement in platforms like LMSs, is something that educators need to be aware of and understand. We have a literacy challenge and a fluency opportunity.

    The opportunity before us

    In the coming days and weeks, I will be sharing details of several major initiatives from the Empirical Educator Project related to this challenge and opportunity. I haven’t even shared them with the EEP network yet because I am in the process of nailing down a few final details right now. But I am very close to nailing down those details. So close, in fact, that I expect to be able to share some of them with the public in the final installment to this series.

    Stay tuned.

    But also, y’all don’t have to wait for me or EEP. Many of you have deep expertise in this content design pattern and what can be done with it already. I’ve found that my biggest challenge in trying to talk to experts about this challenge is that they so take for granted the concepts I’ve been outlining in these last three posts that it’s hard for them to even think about them as something to be discussed and explored. I hope that this series has clarified the need for and value in talking about the content design explicitly. When we talk about the value of digital content in terms of algorithms and data and functionality and other digital terms, it is easy for educators lose the thread. But when those conversations are grounded in the design of content and courses and pedagogy, then the digital accoutrements become embodiments of teaching strategies that make sense to them and that they can think about critically as experts.

    More of that, please.

  • The Affordances of Content Design

    The Affordances of Content Design

    Content is infrastructure.

    David Wiley

    I opened my first post in this series with a statement about courseware and content design:

    An unbelievable number of words have been written about the technology affordances of courseware—progress indicators, nudges, analytics, adaptive algorithms, and so on. But what seems to have gone completely unnoticed in all this analysis is that the quiet revolution in the design of educational content that makes all of these affordances possible. It is invisible to professional course designers because it is like the air they breathe. They take it for granted, and nobody outside of their domain asks them what they’re doing or why. It’s invisible to everybody else because nobody talks about it. We are distracted by the technology bells and whistle. But make no mistake: There would be no fancy courseware technology without this change in content design. It is the key to everything. Once you understand it, suddenly the technology possibilities and limitations become much clearer.

    That’s all true. But this series isn’t really about courseware. It’s about the capabilities and limitations of digital curricular materials, whether they are products sold by vendors, OER, or faculty-developed. The content design pattern I’m exploring is neither unique to vended courseware products nor invented by commercial courseware providers. In fact, instructional designers and LMS providers have been desperately trying to convince faculty of the value of this course design pattern for a many years. But designing content this way takes a lot of work and lacking good examples of the return on that investment, most instructors have not opted to build their content this way.

    What the proliferation of commercial courseware provides that is new is a wealth of professionally developed examples that we can examine to better understand how this content design pattern works to support certain teaching and learning affordances in digital curricular materials. In this post and the next, I will draw on some of those examples, which happen to come from Empirical Educator Project sponsors, to show the design pattern in action.

    The most important message of this series, for both educators and technologists, is that real advances in educational technology will almost always arise out of and be best understood through our knowledge of teaching and learning. In this case, technological affordances such as learning analytics and adaptive learning are only possible because of the instructional design of the content upon which they operate. And we sometimes forget that “instructional design” means design of instruction. The baseline we are working from is instructional content, generally (but not exclusively) designed for self-study. How much value can students get from it? How far can we push that envelope? Whatever the fancy algorithms may be doing, they are doing it with, to, and around the content. The content is the infrastructure. So if you can develop a rich understanding of the value, uses, and limitations of the content, then you can understand the value, uses, and limitations of the both technologies applied to the content and the pedagogical strategies that the combination of content and technologies afford.

    The role of digital curricular materials

    Let’s start by looking at the holistic role that digital curricular materials play when implemented in a way that the design pattern supports. From there, we’ll back into some of the details.

    I’m going to ask you to watch a short promotional video from Pearson of a psychology professor who participated in one of their efficacy studies shares her experiences and observations about teaching with their courseware products. (You should know that Pearson has engaged me as a consultant to review their efficacy reports, including this one, to provide them with feedback on how to make those reports as useful as possible.) The fact that this professor’s story is part of a larger efficacy study means that it is richly documented in ways that are useful to our current purpose.

    As you watch, pay attention to Dr. Williamson says about the affordances of the content and how those affordances support her pedagogical strategies and objectives:

    Dr. Manda Williamson of University of Nebraska-Lincoln on her courseware experiment

    The first thing she talks about is layered formative assessments. Students are given small chunks of content followed by frequent learning activities. They then are prompted to take formative assessments which, depending on the results and the students’ confidence levels, may result in recommending additional activity. (The one mentioned in the video was “rereading.”) If your anchor point for the value of the product is the readings that you assign for homework, then you can see how interactive content that is well designed in this way might be an improvement over flat, non-interactive readings (or even videos).

    When the students come into class—and this is key—Dr. Williamson engages with them on the results of their formative assessments. She teaches to where the students are, and she knows where they are because she has the data from the formative assessments.

    How does that work?

    Those assessment items are tied to learning objectives. Skills and knowledge that have been clearly articulated. In well designed content, the learning objectives have been articulated first and the assessment questions have been written specifically to align with those learning goals. With this content design work in place, creating a “dashboard” is not technologically complicated or fancy at all. No clever algorithms are necessary.

    Suppose you give students five questions for each learning objective. One way you could create a dashboard is to show a line item for each learning objective and show what percentage of the class got all five questions right, what percentage got four out of five, and so on. I’ll show some example dashboards from other products later in this post. For now, the take-away is that the students are basically taking low-stakes quizzes along with their readings, and the instructor is getting the quiz results before the class starts so that she can teach the students to where they are.

    Hopefully the formative assessments don’t feel like “quizzes;” Dr. Williamson has positioned them as tools to help the students learn, which is how exactly how formative assessments should be positioned. But the main point is that the content includes some assessed activity which enables the teacher to have a clearer understanding of what the students know and what kinds of help they may need.

    As a result of adopting the digital content design and teaching strategies that the content and technology affordances supported, Dr. Williamson’s DFW rate dropped from 44% to 12%. Since her course is a gateway course, that number is particularly important for overall student success. So it’s a dramatic success story. But it’s not magic. If you understand teaching, and if you look at the improvements made in the self-study content and the in-class teaching strategies, you quickly come to see that it’s not technology magic but thoughtful curriculum design, solid product usability and utility, and hard work in the classroom that produced these gains. Technology played a critical but highly circumscribed supporting role.

    You can read more about Pearson’s efficacy study, ranging from an academic account of the research to a more layperson-oriented educator guide, here.

    Design details

    It might help to make this a little more concrete. I’m going to provide a few example screens in this post that are fairly closely tied to the basic affordances that I’ve discussed above, and then I’m going to explore some more complex variations in the next post in this series.

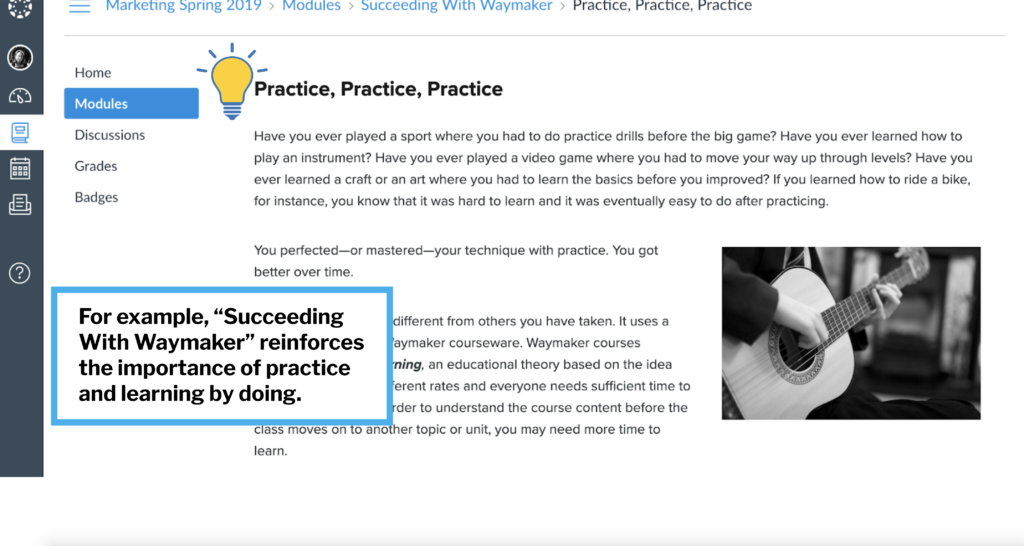
    I mentioned earlier that the formative assessments should function like quizzes but that students should not feel like they are being tested. This idea—that the assessments are to help the students rather than to examine or surveil them—is built into the design of good curricular materials in this style. For example, Lumen Learning’s Waymaker courses has a module that explicitly addresses this idea with the students:

    Lumen Learning “Succeeding With Waymaker” module emphasizes the value of formative assessment.

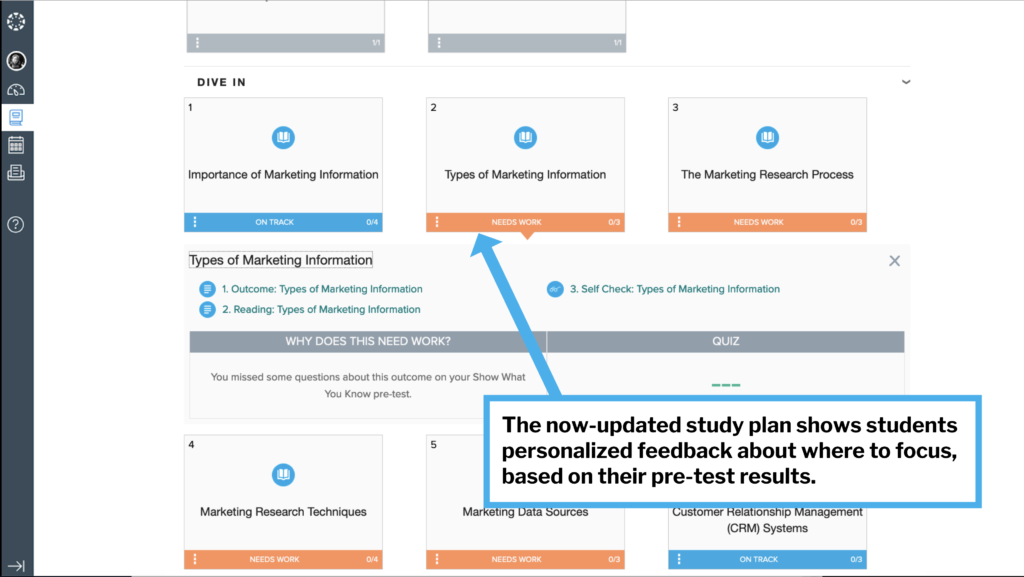
    The Waymaker product then uses the formative assessments the students take, tied to their learning objectives, to show students the associated content areas where they have shown mastery and others where they still need some work. This student dashboard is called the “study plan”:

    Lumen Learning’s study plan updates based on formative assessment scores.

    There are different philosophies about how to provide this kind of feedback. One product designer told me one philosophy he was thinking about is that the best dashboard is no dashboard, meaning that giving student little progress indicators and nudges are better. For educators evaluating different ways to deliver the content, the commonalities provide the tools for evaluating the differences. “Data” are (primarily) the formative student assessment answers. “Analytics” are ways of summing up or extracting insights from the collection of answers, either for an individual student or for a class. “Dashboards,” “nudges,” and “progress indicators” are methods of communicating useful insights in ways that encourage productive action, either on the part of the student or the educator.

    Speaking of the latter, let’s look at some educator dashboards. Let’s look at a dashboard from Soomo Learning’s Webtext platform. Even before you get into how students are performing on their formative assessments, you might want to know how far students have gotten on their assigned work. This might be particularly important in an asynchronous online course or other environment where you have particular reason to expect that students will be moving along at different paces. So this dashboard sorts student by their progress in a chapter:

    Soomo Learning Webtext dashboard shows percentage of questions answered in a chapter.

    Notice that progress here is measured by percentage of questions answered. That tells us something about where the product designers think the value is. A formative assessment isn’t only a measure of learning progress. It is also a learning activity in and of itself. We learn by doing. We learn more effectively by doing and getting instant feedback. So rather than measure pages viewed or time-on-page (although we do see a toggle option for “time” in the upper right-hand corner), the first measure in the dashboard is percentage of questions answered.

    Drilling down, Soomo also shows percentage correct by page:

    Soomo’s Webtext dashboard shows student score by page

    There’s a bit of a rabbit hole that I’m going to point to but avoid going down regarding how cleanly one can separate learning objectives. Does it always make the most sense to present one and only one learning objective per page? And if so, then what’s the best way to present analytics? Rather than explore Soomo’s particular philosophy on that fine point, let’s focus on highlights of the low scores. This is one detail that instructors will want to know at some fairly fine level of granularity. (If two learning objectives are on the same well-designed page, it’s usually because they’re closely related.) This dashboard enables instructors to see which students, both individually and as a group, scored poorly on particular assessments on a page.

    Again, there’s no algorithmic magic here. Let’s assume for the sake of argument that the content and assessments are well designed. Soomo is thinking about what educators would need to know about how students are progressing through the self-study content in order to make good instructional decisions. They are then designing their screens to make that information available at a glance.

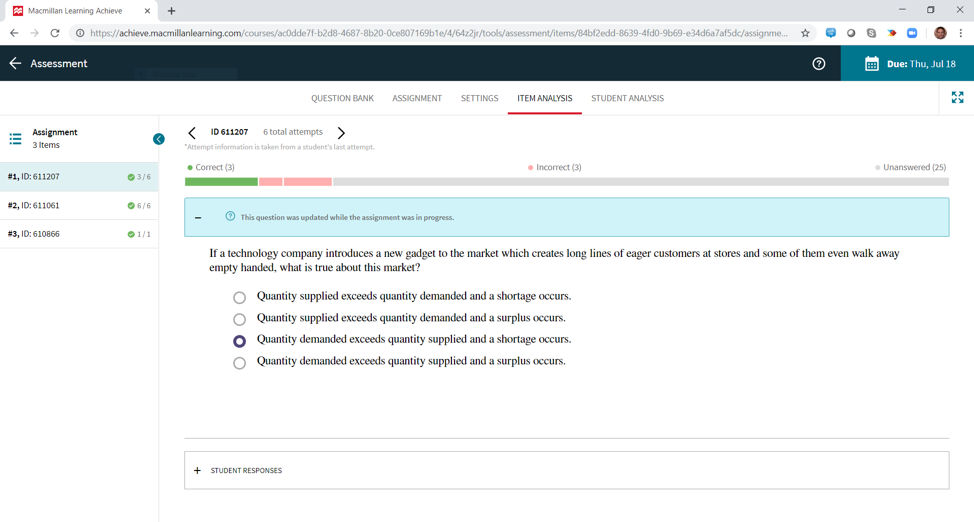
    Now imagine for a moment that you have this kind of increased visibility on how students are doing with their self-study. You see that students are doing well on a learning objective overall, but they’re struggling with one particular question. In the old world of analog homework, you might not catch this sort of thing until a high-stakes test. But with digital curricular materials, where you can give more formative assessment and have it scored for you (within the bounds of what machines are capable of scoring), you might quickly find one particular problem in an assessment that students are struggling with. Is the question poorly written? Is it catching a hidden skill, or a twist that you didn’t realize made the problem difficult? You’d want to drill down. Here’s a drill-down screen from Macmillan’s Achieve formative assessment product:

    Macmillan Achieve question drill-down shows question-by-question performance.

    (You should know that I serve on Macmillan’s Impact Research Advisory Council.)

    This is exactly the sort of clue that an educator might want to look at while preparing for a class. What are the unusual patterns of student performance? What might that tell us about hidden learning challenges and opportunities? And what might it tell us about our course design?

    Hints of what’s coming

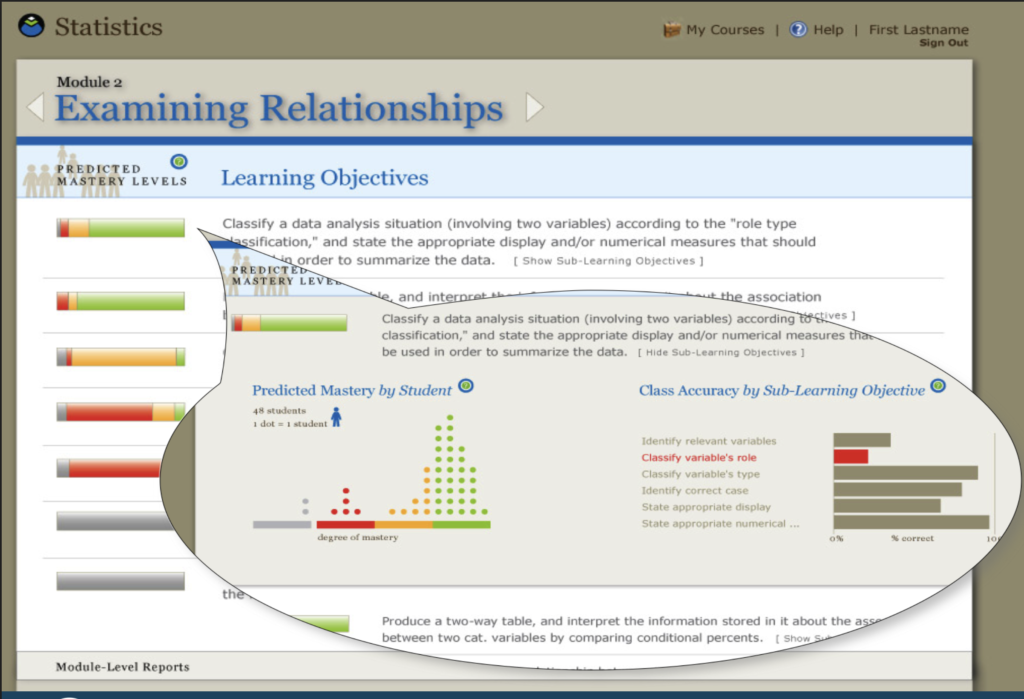
    I’ll share two more screen shots as a way of teasing some of the concepts coming in the next post. This first one is from Carnegie Mellon University’s OLI platform:

    Carnegie Mellon University OLI’s Predicted Mastery learning dashboard

    At first glance, this looks like another learning dashboard. What percentage of the class are green, yellow, or red (or haven’t started) for each learning objective? But notice one little word: “predicted mastery levels.” Predicted. Once you start collecting enough data, by which we mean enough student scores to begin to see meaningful patterns, we can apply statistical analysis to make predictions. There is a certain amount of justifiable anxiety about using predictive algorithms in education, but the problem springs from applying the math without understanding it. That’s what predictive algorithms are, at their most basic. They’re statistical math formulas. And honestly, many of the predictive algorithms used in ed tech are, in fact, basic enough that educators can get the gist of them. We’ve been taught to believe that the magic is in the algorithm. But really, most of the time, the magic is in the content design.

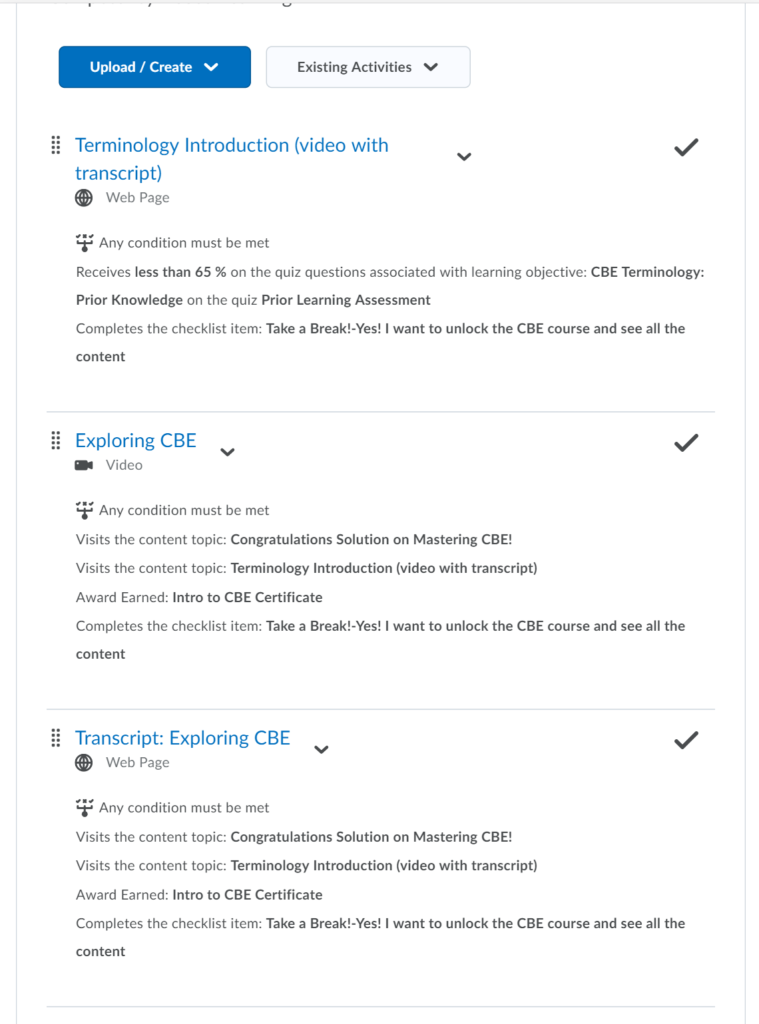
    And here’s a screen from D2L Brightspace:

    Brightspace conditional release tablet view.

    There’s a lot to unpack here, and I won’t be able to get to it all in this post. This is a tablet view of functions that Brightspace has been building up forever and a day. Since long before modern courseware existed as a product category. For starters, you can see in the top box that Brightspace can assign mastery for a learning objective. (In this case, the objective happens to be “CBE Terminology: Prior Knowledge.”) But what follows is a set of simple programming instructions of the form, “If a student meets condition X [e.g., receives less than 65% on a particular assessment] then perform action Y [e.g., show video Z].” In the olden days of personal computers, we would call this a “macro.” In the olden days of LMSs, we would call it “conditional release.” Today’s hot lingo for it is “adaptive learning” or “personalized learning.” Notice in this example that we are still starting with performance against a learning objective. We are still starting with content design.

    (Note also that many of the technology affordances built into vended courseware are also available in content-agnostic products like LMSs and have been for quite some time. Instructors can build content in this design pattern with the tools they have at hand and gain benefits from it.)

    In the next post, I’m going to talk about how advanced statistical techniques, including machine learning techniques, and automation, including what we commonly refer to as adaptive learning, are methods that digital course content designers use to enhance the value of their course content designs. But all of those enhancements still build off of and depend upon that bedrock content design pattern that I described in the first post of this series.

    The atomic unit of digital curricular materials design

  • EEP 2019 Summit Videos Are Up

    It took longer than I had hoped, but you can now see most of the Empirical Educator 2019 summit presentations here. (Unfortunately, the videographers didn’t capture the last couple of presentations on OpenSimon.) I’ll return to these after I finish my series on digital curricular materials design, but in the meantime, the talks are available for your enjoyment.

    Dig in.

  • The Content Revolution

    Content is infrastructure.

    David Wiley

    An unbelievable number of words have been written about the technology affordances of courseware—progress indicators, nudges, analytics, adaptive algorithms, and so on. But what seems to have gone completely unnoticed in all this analysis is that the quiet revolution in the design of educational content that makes all of these affordances possible. It is invisible to professional course designers because it is like the air they breathe. They take it for granted, and nobody outside of their domain asks them what they’re doing or why. It’s invisible to everybody else because nobody talks about it. We are distracted by the technology bells and whistle. But make no mistake: There would be no fancy courseware technology without this change in content design. It is the key to everything. Once you understand it, suddenly the technology possibilities and limitations become much clearer.

    For those familiar with course design lingo, the design pattern I am talking about can be summed up as backward design coupled with programmatic formative assessment. This post is the first in a series in which I will explain this design pattern, it’s possibilities and limitations, and the ways in which it makes possible a whole range of educational technology affordances.

    Backward Design

    “Backward Design” is a term that comes from a larger framework called “Understanding by Design,” (UbD) developed by Grant Wiggins and Jay McTighe and articulated in a book by the same name. While it was developed as K12 curriculum design approach, it has been widely embraced by curriculum and course content designers at all levels. Because the backward design practice as applied in courseware authoring necessarily requires what some might perceive as a “dumbing down” of the approach (for reasons I will get into later in this post), it’s important to understand the philosophical roots of UbD. On one hand, this is an approach that is grounded in the political reality of a K12 world that is driven by curriculum standards. Wiggins and McTighe are unapologetic about having defined curricular goals for students. On the other, UbD is intended to work against the tendency to memorization of facts and rote applications of lower-order skills, fostering critical thinking and knowledge transfer across domains. Three of the seven tenets of UbD (as articulated in this crisply written white paper by Wiggins) are as follows:

    • The UbD framework helps focus curriculum and teaching on the develop- ment and deepening of student understanding and transfer of learning (i.e., the ability to effectively use content knowledge and skill).
    • Understanding is revealed when students autonomously make sense of and transfer their learning through authentic performance. Six facets of under- standing—the capacity to explain, interpret, apply, shift perspective, empa- thize, and self-assess—can serve as indicators of understanding.
    • Teachers are coaches of understanding, not mere purveyors of content knowl- edge, skill, or activity. They focus on ensuring that learning happens, not just teaching (and assuming that what was taught was learned); they always aim and check for successful meaning making and transfer by the learner.

    UbD is explicitly not a paint-by-numbers approach to education. It is, however, a design-intensive approach to teaching that emphasizes the value of preparation and goal-oriented thinking as a key to unlocking teachable moments. This 10-minute video of Wiggins explaining the philosophy is well worth your time and provides a philosophical guide star to keep in sight as we navigate backwards design in general and its application to courseware design in particular:

    Grant Wiggins – Understanding by Design

    The upshot of his message here is that teachers and student continually need to be asking the question, both individually and together—what are the larger learning goals here?

    Backwards Design, at its most basic, is the idea that educators should be asking that question from the moment they start planning their course. Rather than starting with a collection of content and activities and putting it into a sequence, educators should start by articulating the end goals for the students (where an end goal is broad enough to encompass high-level and non-cognitive goals such as “a love of reading”). The three-step process of backward design is as follows:

    1. Identify desired results
    2. Determine acceptable evidence
    3. Plan learning experiences and instruction

    All content and activity choices flow from identifying the desired results and determining acceptable evidence of achievement of those results. This approach is “backwards” from the typical approach of starting with content that needs to be covered.

    Backward Design in courseware development

    Modern courseware, and many of the most highly touted technology affordances that come with it, flow from the Backward Design technique. But there are two additional constraints that are imposed by the medium. First, the activities in the courseware can only be activities that can be facilitated in an online medium—and, since courseware is modeled after the textbook, these are usually (but not always) solo activities by students that look like digital extensions of the kinds of exercises that you would expect from textbooks. Second, since key technological affordances of courseware come from its ability to auto-assess student progress, “acceptable evidence” generally must be machine-gradable evidence.

    Since this is Backward Design, these changes have implications up the chain to the first step in the process. Rather than “identifying desired results,” courseware designers have to think in terms of “learning objectives” that are realistic to achieve and measure given the limitations of the medium. The University of Central Florida (UCF) has posted a learning objective builder tool which, while not limited to the application of courseware design, begins to convey how courseware designers need to think about learning objectives in order to design content that will work in the courseware medium. The learning objective structure in the UCF example has four components:

    1. Condition, e.g., “Given a blank map of the United States…”
    2. Audience, e.g., “…the student…”
    3. Behavior, e.g., “…will identify all 50 states and capitals…”
    4. Degree, e.g., “…with 90% accuracy.”

    In comparison to Wiggins’ framing of UbD, this may feel starkly reductive to you. It’s important to keep in mind that the example was undoubtedly written for clarity rather than to illustrate how creative an educator can be while still staying within the bounds of the format. That said, there is no question that the format is limiting.

    And this, I think, is where a lot of unilluminating argument over the value of courseware originates. On the one hand, if the idea is that courseware will largely replace human instruction, then we have to recognize the gap between the learning objectives which the courseware can assess and the desired educational results which a human teacher can address and assess. On the other hand, it’s very hard to talk about that gap meaningfully and specifically when the entire course hasn’t been backward designed in the first place. If a course has clearly defined desired outcomes and clearly defined acceptable evidence of those outcomes, then it is a straightforward exercise to identify the subset of goals and evidence that courseware can address. But in absence of that larger course blueprint, educators who want to argue that courseware is too reductive start to get hand-wavy pretty quickly. We shouldn’t be surprised that interactive curricular materials are not complete substitutes for a classroom experience, but we should be able to clearly articulate what the gap is and how classroom interactions address that gap in ways that courseware can’t on on a course-by-course basis.

    The atomic unit of courseware content design

    Once we’ve translated the principles of Backward Design to fit the constraints of courseware, we end up with a tightly constructed content design:

    The content triangle of learning objectives, assessments, and instructional activities

    Again, this structure is not limited to courseware; it’s a good distillation of the results of backward design in general, using language that also translates well into courseware design. But when building modern courseware, this design is formal and structural. Every instructional activity (which, in the case of courseware, means interactive or non-interactive content items) and every assessment activity is tagged to correspond with a specific learning objective. As far as the software is concerned, this collection of items and metadata is a formal and atomic unit of instruction. McGraw-Hill Education even went so far as to name this collection a “compound learning object (CLO)“.

    As we will see in detail in the next post in this series, many of the technology affordances of modern courseware depend utterly on this formal structure. And once you understand the design pattern, you can see it everywhere in most curricular materials products and in an increasing number of courses designed on campuses with the help of professional instructional designers. I would go so far as to say that the formalization of this content structure, and not any fancy technology capabilities like adaptive learning algorithms or learning analytics dashboards, is the defining innovation in curricular materials over the last decade. It is the key to everything.

    Programmatic formative assessment

    There is one other defining content feature that is worth talking about before we explore implementation examples in the next post. A key educational affordance of courseware products that is often touted is instantaneous feedback. Since there is strong evidence that timely feedback is critical to the learning process, this is a key benefit (assuming that the feedback is meaningful). But instantaneous feedback on summative assessments—on assessments at the end that measure how much the student has learned before moving on to the next lesson—is not as helpful to students as it might be because…well…they’re moving on to the next lesson. They may or may not take the time to reflect on their incorrect answers. In contrast, feedback on low-stakes assessments, particularly when it is supported by feedback and support from the educator, can be very useful. In fact, I have long argued that this ability to have students practice their skills and test themselves—yes, before they take a summative assessment, but more importantly, before they walk into a class discussion—is a key value proposition for modern courseware. Class preparation.

    This is often billed as a technology affordance, but once again it is utterly dependent on the content design. Their analog…er…analogue is back-of-the-chapter homework problems. Practice problems that are linked to a skill or a bit of knowledge that will ultimately be assessed for a grade is not a new idea. The technology simply improves on the kinds of practice and feedback that were possible with flat textbooks. It can be given more often, in more interactive formats, with more timely feedback.

    Circling back to the Grant Wiggins video at the top of this post, students and educators alike need to constantly be asking the question “Why am I doing this now?” Whatever we are learning—or teaching—we should always also be studying whether our activities are aligned with our goals. Good educators are continually assessing their students in a variety of ways, starting with looking at their faces to see if they look like they are following, bored, confused, etc. They adjust according to what they see. Likewise, students need to be assessing their learning strategies and progress in order to get better at achieving their learning goals. One defining characteristic of modern courseware content design is creating as close to a continuous assessment feedback loop as possible.

    Content as infrastructure

    As I’ve stressed throughout this post, I don’t think it’s possible to overstate the role of this content design pattern—Backward Design plus programmatic formative assessment—in most of the recent innovations in digital curricular materials. In the next posts in this series, I will show concrete examples of how this design pattern makes various technological affordances possible as well as how it opens up new possibilities for tuning both courseware content and teaching strategies for continuous improvement. In the last installation, I will write about the need for and benefits of having content interchange and analytics interoperability standards that are tuned to this ubiquitous yet invisible content design pattern.

  • The Cengage-MHE Merger and Data Danger

    The Cengage-MHE Merger and Data Danger

    EdSurge has a good piece up about the U.S. Public filing submitted by the Scholarly Publishing and Academic Resources Coalition (SPARC) with the U.S. Department of Justice opposing the merger between Cengage and McGraw-Hill. In addition to the expected fare about pricing and reduced competition, there is a surprisingly fulsome argument about the dangers of the merger creating an “enormous data empire.”

    Given that the topic at hand is an anti-trust challenge with the DoJ, I’m going to raise my conflict of interest statement from its normal place in a footnote to the main text: I do consulting work for McGraw-Hill Education and have consulting and sponsorship relationships with several other vendors in the curricular materials industry. For the same reason, I am recusing myself from providing an analysis of the merits of SPARC’s brief.

    Instead, I want to use the data section of their brief as a springboard for a larger conversation. We don’t often get a document that enumerates such a broad list of potential concerns about student data use by educational vendors. SPARC has a specific legal burden that they’re concerned with. I’ll briefly explain it, but then I’m going to set it aside. Again, my goal is not to litigate the merits of the brief on its own terms but rather explore the issues it calls out without being limited by the antitrust arguments that SPARC needs to make in order to achieve their goals.

    Let’s break it down.

    When is bigger worse?

    While I’m sure that PIRG’s concerns about the data are genuine, keep in mind that they have been fighting a long-running battle against textbook prices, and that the primary framing of their brief is about the future price of curricular materials. Their goal is to prevent the merger from going through because they believe it will be bad for future prices. Every other argument that they introduce to the brief, including the data arguments, they are introducing at least in part because they believe it will add to their overall case that the merger will cause, in legal parlance, “irreparable harm.” As such, that has to be the standard for them. It’s not whether we should be worried about misuse of data in general, but about whether this merger of the data pools of two companies makes the situation instantly worse in a way that can’t be undone. That’s pretty high bar. Each of their data arguments needs to be considered in light of that standard.

    But if you’re more concerned with the issues of collecting increasingly large pools of student data in general, and if you can consider solutions other than “stop the merger,” then there is a more nuanced conversation to be had. I’m more interested in provoking that conversation.

    What can be inferred from the data

    One question that we’re going to keep coming back to throughout the post is just how much can be gleaned from the data that the publishers have. This is a tough question to answer for a number of reasons. First, we don’t know exactly everything that all the publishers are gathering today. SPARC’s doesn’t provide us with much help here; they don’t appear to have any inside information, or even to have spent much time gathering publicly available information on this particular topic. I have a pretty good idea of what publishers are collecting in most of their products today, but I certainly don’t have a comprehensive knowledge. And it’s a moving target. New features are being added all the time. I can speak a lot more confidently about what is being gathered today than on what may be gathered a year from now. The further out in time you go, the less sure you can be. Finally, while publishers—like the rest of us—have thus far proven to be relatively bad at extrapolating useful holistic knowledge about students from the data that publishers tend to have, that may not always prove to be the case. So with those generalities in mind, let’s look at SPARC’s first claim:

    Like most modern digital resources, digital courseware can collect vast amounts of data without students even knowing it: where they log in, how fast they read, what time they study, what questions they get right, what sections they highlight, or how attentive they are. This information could be used to infer more sensitive information, like who their study partners or friends are, what their favorite coffee shop is, what time of day they commute from home to school, or what their likely route is.

    How much of that “more sensitive information” that SPARC claims can be inferred really logical to fear right now? Most of the scary stuff they speculate about here is location-related. Unless the application page specifically asks the student’s permission to use geolocation and the student grants it—I’m sure you’ve had web pages ask your permission to know your location before—then the best it can do is know the student’s IP address, which is a pretty crude location method. None of the place-based information is really accessible via any data that is collected through any courseware that I’m aware of today. The only exception I know of is attendance-taking software. How much of an additional privacy risk it is to know the attendance habits of students who are already known to have registered for a class in virtue of the fact that they are taking and using the curricular materials associated with the class is an open question.

    The other risk SPARC references specifically is knowledge of social connections. There are products that do facilitate the finding of study partners. Actually, the LMS market, which is roughly as concentrated as the curricular materials market, may have much more exposure to this particular concern.

    While I certainly wouldn’t want these data to be leaked by the stewards of student learning information, I suspect there is much better quality data of this sort that is more easily obtainable from other sources. Even in the worst case, if they got misappropriated and merged with consumer data sets, the incremental value of this information relative to what someone with ill intent could learn from the average person’s social media activity strikes me as pretty limited.

    Of course, the information value is a separate question from the responsibility of care. Students are responsible for the information that they post on their social media accounts. Educators and educational institutions have a responsibility of care for data in products that they require students to use. That said, we should think about both the responsibility of care and the sensitivity of particular data. Generally speaking, I don’t see the kind of location and and personal association data that publisher applications are likely to have as particularly sensitive.

    Anyway, continuing with SPARC’s brief:

    “We now have real time data, about the content, usage, assessment data, and how different people understand different concepts,” said Cengage CEO Michael E. Hansen in an interview with P​ublishers Weekly​.135 McGraw-Hill claims that its SmartBook program collects 12 billion data points on students. Pearson now allows students to access its Revel digital learning environment through Amazon’s Alexa devices—which have been criticized for gathering data by “listening in” on consumers.

    Once gathered, these millions of data points can be fed into proprietary algorithms that can classify a student’s learning style, assess whether they grasp core concepts, decide whether a student qualifies for extra help, or identify if a student is at risk of dropping out. Linked with other datasets, this information might be used to predict who is most likely to graduate, what their future earnings might be, how a student identifies their race or sexual orientation, who might be at risk of self-harm or substance abuse, or what their political or religious affiliation might be. While these types of processes can be used for positive ends, our society has learned that something as seemingly innocent as an online personality test can evolve into something as far-reaching as the Cambridge Analytica scandal. The possibilities for how educational data could be used and misused are endless.

    I realize that this is a rhetorical flourish in a document designed to persuade, but no, the possibilities really aren’t endless. If you can’t train a robot tutor in the sky by having it watch you solve more geometry problems, then you can’t bring Skynet to sentience that way either. I don’t want to minimize real dangers. Quite the opposite. I want to make sure we aren’t distracted by imaginary dangers so that we can focus on the real ones.

    I’m particularly concerned by the Cambridge Analytica sentence. “Something as seemingly innocent as an online personality test can evolve into something as far-reaching…”. The implication seems to be that Cambridge Analytica inferred enormous amounts of information from an online personality test. But that’s not what happened. The real scandal was that Cambridge Analytica used the personality test to get users to grant them permission to enormous amounts of other data in their profile. The kind of deeply personal data that people put in Facebook but don’t tend to put in their online geometry courseware. I don’t see how that applies here.

    Of course, the data that these companies collect in the future may change, as may our ability to infer more sensitive insights from it. Writ large, we don’t have to make the kind of cut-and-dry, snapshot-in-time decision that a legal brief necessarily advocates. Rather than making a binary choice between either blithely assuming that all current and future uses of student educational data in corporate hands will be fine or assuming the dystopian opposite and denying students access to technology that even SPARC acknowledges could benefit them, the sector should be making a sustained and coordinated investment in student data ethics research. As new potential applications come online and new kinds of data are gathered, we should be pro-actively researching the implications rather than waiting until a disaster happens and hoping we can up the mess afterward.

    Data permission creep

    SPARC next goes on to argue that since (a) students are a captive audience and essentially have no choice but to surrender their rights if they want to get their grades, (b) professors, who would be the ones in a position to protect students’ rights, don’t have a good track record of protecting them from textbook prices, and (c) nobody has a good track record of reading EULAs before clicking away their rights, there is a good chance that, even if the data rights students give agree to give away are reasonable today, there is a high likelihood that they will creep into unreasonableness in the future:

    Students are not only a “captive market” in terms of the cost of textbooks, they are a captive market in terms of their data. The same anticompetitive behavior that arose in the relevant market for course materials is bound to repeat itself in the relevant market for student data.

    As the market shifts toward inclusive access fees and all-access subscriptions, students increasingly will be required to use digital course materials as a condition of enrolling in a course. Even if a student is not automatically subscribed, they may be enrolled in a course using digital homework, where a portion of a student’s grade depends on purchasing an access code, accepting the terms of use, and potentially surrendering data in the process of completing assignments. This is a new dimension of the principal-agent problem. In the same way that it is a foregone conclusion that students will need to purchase assigned materials regardless of the price, it is also a foregone conclusion that they will need to accept the terms of use.

    The graph of textbook prices since 1980 in Section 1.1 illustrates what can happen when publishers engage in coordinated pricing practices in a market where consumers have little power, as we discussed in Section 4.1. The same problem could repeat itself in terms of the ever expanding permissions granted under terms of use. Just as professors are sometimes unaware when the price of a textbook goes up, they may not be aware when the terms of use change in a way that may be unacceptable to their students.

    Therefore, there is potential for publishers to inflate the permissions they require students to grant in exchange for using a digital textbooks in the same way that they have inflated prices through coordinated behavior. Students will not only be paying in dollars and cents, but also in terms of their data.

    I find the permissions creep argument to be compelling for several reasons. First, the question of whether people should have a right to control how their data are used is separable from the question of known harm that abuse of those data could cause. Students should have right to say how their data can be used and shared, regardless of whether that use is deemed harmful by some third party.

    Second, there is an argument that SPARC missed here related to human subjects research. Currently, universities are required by law to get any experimentation with human subjects, including educational technology experiments, approved by an IRB. This includes, but is not limited to, a review of informed consent practices. Companies have no such IRB review requirement under current law. Companies with more data, more platforms, and bigger research departments can conduct more unsupervised research on students. For what it’s worth, my experience is that companies that do conduct research often try to do the right thing. But that should be small comfort, for a number of reasons.

    First, there is no generally agreed upon definition of what “the right thing” is, and it turns out to be very complicated. When is an activity research “on” students, and when is it “on” the software? If, for example, you move a button to test whether doing so makes a feature easier to find, but awareness of that feature turns out to make a difference in student performance, then would the company need IRB approval? If the answer “yes,” and “IRB approval” for companies looks anything remotely like what it does inside universities today, then forget about getting updated software of any significance any time soon. But if the answer is “no,” then where is the line, and who decides? There is basically no shared definition of ethical research for ed tech companies and no way to evaluate company practices. This is not only bad for the universities and students but also for the companies. How can they do the right thing if there is no generally accepted definition of what the right thing is?

    Second, if IRB approval specifically means getting the approval of one or more university-run IRBs, and particularly if it means getting the approval of the IRB of every university for every student whose data will be examined, universities have not yet made that remotely possible to accomplish. Nor could they handle the volume. I believe that we do need companies to be conducting properly designed research into improving educational outcomes, as long as there is appropriate review of the ethical design of their studies. Right now, there is no way of guaranteeing both of these things. That is not the fault of the companies; it’s a flaw in the system.

    Fixing the student privacy permission problem would be hard to do in a holistic way. Some further legislation could potentially help, but I’m not at all confident that we know what that legislation should require at this point. I’ve written before about how federated learning analytics technical standards like IMS Caliper could theoretically enable a technical solution by enabling students to grant or deny permission to different systems that want access to their data, similarly to the way in which we grant or deny access to apps that want access to data on our phones. But that would be a long and difficult road. This is a tough nut to crack.

    The research problem is also tough, but not quite as tough as the privacy permission problem. I’ve been speaking to some of my clients about it in an advisory capacity and working on it through the Empirical Educator Project. It is primarily a matter of political will at this point, and the pressure to solve this problem is rising on all sides.

    More data means more privacy risk

    For our purposes, I won’t quote the entirety of SPARC’s argument on this topic, but here’s the nub of it:

    It is common sense that the more data a company controls, the greater the risk of a breach. Recent experience demonstrates that no company can claim to be immune to the risk of data breaches, even those who can afford the most updated security measures. The size or wealth of a company has proven no obstacle to potential hackers, and in fact larger companies may become more tempting targets. Allowing more student data to become concentrated under a single company’s control increases the risk of a large scale privacy violation.

    As a case in point, Pearson recently made the news for a major data breach. According to reports, the breach affected hundreds of thousands of U.S. students across more than 13,000 school and university accounts. Pearson reports that no social security numbers or financial information was compromised, but this is not the only kind of data that can cause damage. Compromising data on educational performance and personal characteristics can potentially affect students for the rest of their lives if it finds its way to employers, credit agencies, or data brokers.

    While state and federal laws provide some measure of privacy protection for student records, including limiting the disclosure of personally identifiable information, they do not go far enough to prevent the increased risk of commercial exploitation of student data or protect it from potential breaches.

    While we should be very concerned about student data privacy, I don’t think the number of data points an education company has about a student is a good measure of the threat level. Again, a merged Cengage/McGraw-Hill would not have the same kind of data that Facebook would. We have to think very specifically about these data because they are quite different from data on the consumer web. The number of hints a student asked for in a psychology exercise or the number of algebra problems a student solved do not strike me as data that are particularly prone to abuse. These sorts of information bits comprise the bulk of the data that such companies have in their databases today. There may very well be extremely serious data privacy issues lurking here, but they will not be well measured by the volume of data collected (in contrast with, say, Google).

    The point about the gaps in the laws is a much more serious one. Everybody has known for years, for example, that FERPA is badly inadequate. It is only getting worse as it ages. The Fordham paper cited by SPARC has some good suggestions. Now, if only we had a functioning Congress….

    Algorithms

    Again, I’ll excerpt the SPARC filing for our purposes:

    Algorithms are embedded in some digital courseware as well, including the “adaptive learning” products of the merging companies and some of their competitors. These algorithms can be as simple as grading a quiz, or as complex as changing content based its assessment of a student’s personal learning style….

    While algorithms can produce positive outcomes for some students, they also carry extreme risks, as it has become increasingly clear that algorithms are not infallible. A recent program held at the Berkman Klein Center for Internet and Society at Harvard University concluded categorically that “it is impossible to create unbiased AI systems at large scale to fit all people.” Furthermore, proprietary algorithms are frequently black boxes, where it is impossible for consumers to learn what data is being interpreted and how the calculations are made—making it difficult to determine how well it is working, and whether it might have made mistakes that could end in substantial legal or reputational consequences.

    Let’s disambiguate a little here. There are two senses in which an algorithm could be considered a “black box.” Colloquially, educators might refer to an adaptive learning or learning analytics algorithm that way if they, the educators using it, have no way of understanding how the product is making the recommendations. If an algorithm is proprietary, for example, the vendor might know why the algorithm reaches a certain result, but the educator—and student—do not.

    Within the machine learning community, “black box” means something more specific. It means that the results are not explainable by any humans, including the ones who wrote the algorithm. In certain domains, there is a known trade-off between predictive accuracy and the the human interpretability of how the algorithm arrived at the prediction.

    Both kinds of black boxes are very serious problems for education. In my opinion, there should be no tolerance for predictive or analytic algorithms in educational software unless they are published, peer reviewed, and preferably have replicated results by third parties. Educators and qualified researchers should know how these products work, and I do not believe that this an area where the potential benefits of commercial innovation outweigh the potential harm. Companies should not compete on secret and potentially incorrect insights about how students learn and succeed. That knowledge should be considered a public good. Education companies that truly believe in their mission statements can find other grounds for competitive advantage. This is another area that EEP is doing some early work on, though I don’t have anything to announce on it just yet.

    The second kind of black box—algorithms that are published and proven to work but are not explainable by humans—should be called out as such and limited to very specific kinds of low-stakes use like recommending better supplemental content from openly available resources on the internet. We should develop a set of standards for identifying applications in which we’re confident that not understanding how the algorithm arrives at its recommendation does not introduce a substantial ethical risk and does produce substantial educational benefit. If the affirmative case can’t be made, then the algorithm shouldn’t be used.

    Data monopolies

    I’m going to be a little careful with this one because, again, I am recusing myself from commenting on the merits of the brief, and this particular data topic is hardest to address while skirting the question before the DoJ. But I do want to make some light comments on the broader question of when combining different educational data sets is most potent and therefore most vulnerable to abuse.

    From SPARC:

    One lesson learned from the rise of technology giants like Facebook is that preventing platform monopoly from forming is far simpler than breaking one up. Given the vast quantity of data that the combined firm would be in a position to capture and monetize, there is a real potential for it to become the next platform monopoly, which would be catastrophic for student privacy, competition, and choice.

    For decades, the college course material market has been split between three giants. There is a large difference between a market split three ways and a market split two ways. As these companies aggressively push toward digital offerings and data analytics services, a divided market will limit the size and comprehensiveness of the datasets they are able to amass, and therefore the risk they pose to students and the market. So long as publishers are competing to sell the best products to institutions, and there is significantly less risk of too much student data ending up in one company’s hands.

    I won’t characterize the danger of combining publisher data sets beyond what I’ve already covered in this post. What I want to say here is that the bigger opportunity for potential insights, and therefore the bigger area of concern for potential abuse, may be when combining data sets from different kinds of learning platforms. I haven’t yet seen evidence that combining data across courseware subjects yields big gains in understanding regarding individual students. But when you combine data from courseware, the LMS, clickers, the SIS, and the CRM? That combination of data has great potential for both benefit and harm to students because it provides a much richer contextual picture of the student.

    Irreparable harm

    While nothing in this post is intended to comment directly on the matter before the DoJ, the phrase that frames the anti-trust argument—”irreparable harm”—is one that we should think about in the larger context. I believe we have an affirmative obligation to students to develop and employ data-enabled technologies that can help them succeed, but I also believe we have an affirmative obligation to proceed in a way that prioritizes the avoidance of doing damage that can’t be undone. “First, do no harm.” We should be putting much more effort into thinking through ethics, designing policies, and fostering market incentives now. I don’t see it happening yet, and it’s not even entirely clear to me where such efforts would live.

    That should trouble us all.

  • Pearson’s Born-Digital Move and Frequency of Updates

    Pearson’s Born-Digital Move and Frequency of Updates

    There’s been a bit of an uproar over Pearson’s announcement that they are switching entirely to a digital-first model and will be updating their editions more frequently as a result. ((Full disclosure: Pearson is both a current sponsor of the Empirical Educator Project and a current consulting client.)) The prevailing take in the media write-ups so far has been fear of increasing prices. I’m not doing as much of that sort of analysis as I used to anymore. As usual, if you want a clear write-up of it, a good place to check is with PhilonEdTech. I do have a somewhat different take on the economics than the current hand-wringing would suggest and will use a graph from Phil’s post to make a brief point about it. The middle of this post will be about the difference between print and digital and how that drives different reasons for updating an “edition.” And the last part will be about drawing larger lessons from the tendency in ed tech to tell stories that are more based on past traumas than analysis of current situations.

    The horse is out of the barn on pricing

    Phil’s post contains this graph showing the publishers’ competition with other sources for textbook rentals:

    Graph of textbook rental distribution from PhilonEdTech, sourced from NACS

    The textbook publishers have a lot to gain by controlling the distribution channel for their products. If they can cut out Amazon and Chegg, then they can get a larger percentage of each sale. So they definitely have a lot to gain economically from this.

    But I don’t get the sense that any of the major publishers believe they can raise prices again. They all read the OER faculty attitude surveys very carefully. The prevailing sense in the industry is that, in addition to the strong price sensitivity and ingenuity that has existed among students for some time, there is now increasing price awareness and sensitivity among academics that is not going away. I don’t think this is about that.

    In fact, while there are immediate economic reasons for publishers to make this move—if remember correctly, McGraw Hill made the same move a while ago—there are also product-related reasons for doing so.

    Analog vs digital updates

    Many folks in the sector have a reflex reaction to the phrase “textbook edition” based on the old print tradition of updating a book every three years whether it needed updating or not. In some subjects, a three-year update is warranted. Programming languages change, for example. Linear algebra, on the other hand? Not so much. Textbook publishers gained a somewhat justified reputation for updating books every three years just to thwart the used book market. Which they then reinforced by raising prices every year, driving students to the used book market and giving publishers further incentives to update editions for purely economic reasons.

    That said, in the digital world, there are legitimate reasons for product updates that don’t exist with a print textbook. First, you can actually get good data about whether your content is working so that you can make non-arbitrary improvements. I’m not talking about the sort of fancy machine learning algorithms that seem to be making some folks nervous these days. I’m talking about basic psychometric assessment measures that have been used since before digital but are really hard to gather data on at scale for an analog textbook—how hard are my test questions, and are any of the distractors obviously wrong?—and page analytics on the level that’s not much more sophisticated that I use for this blog—is anybody even reading that lesson? Lumen Learning’s RISE framework is a good, easy-to-understand example of the level of analysis that can be used to continuously improve content in a ho-hum, non-creepy, completely uncontroversial way.

    (I stress this because there’s been an elevated level of concern about intrusive analytics among a segment of the e-Literate readership and I want to be clear that one can do quite a bit without coming anywhere near the touchy areas.)

    At the same time, unlike paper books, digital products have functionality, and there is always a continuous list of features that students and teachers want or need. Just keeping up with accessibility requirements is a never-ending job. Then, instructors in different subjects want different quiz question types. Or the ability to author those question types. Or different configurations on the number of tries that students can have for the questions. Or the number of hints they can have. Or integration with some discipline-specific tool that they like to use. Or a tool that the students like to use. It goes on and on and on.

    Are all of these updates good updates? That’s an impossible generalization to make. People who have no use for a software product category in the first place generally tend to think that the updates to a pointless product are pointless. So if you’re already cynical about courseware, you’ll probably be cynical about courseware functionality updates. If you find courseware useful, then your attitude will be closer to that of any other software user, which is to say that you’ll look at whether the particular update fits your need. Since functionality in courseware platform often is differentially useful across disciplines, chances are that you will like some updates a lot and find others completely uninteresting (or even a step backwards for your particular needs). If you are a builder of digital platforms that need to support a wide range of academic disciplines, as Pearson now is, you have a lot of surface area that you have to cover. Hence the need for frequent updates.

    Motivation

    Ed tech news cycles often feel like fighting the last war to me. We’re always building our Maginot Line. Some vendor does something, and everybody rushes to write the hand-wringing story about how this might be just like the last disaster. The last trauma. Nobody asks, “What’s changed since then?”

    Analogously to default story trope with the LMS vendors, the default story tropes about the publishers all come from past traumas about pricing and don’t take into account how the economics of the industry have changed completely in the last decade, or how going from print to digital changes what it even means to update an edition.

    Nor do these trauma stories take into account what is changeable. They are typically written as if vendors are implacable forces of nature or all-powerful multi-national corporations. Pearson, one of the largest companies in the sector, is just 2.5% the size of Exxon Mobil. Even assuming the worst regarding the intent of the company management, the industry could not have maintained such high price points if faculty had simply started to select books based on price. Vendors respond to the signals customers send about what matters to them.

    Faculty had the power to change the industry. Whether knowingly or not, they chose not to exercise it. They chose not to even ask about the price in the majority of cases for many, many years. This is not to let companies off the hook for their decisions but rather to say that when we choose to retell trauma stories without interrogating them, we may miss opportunities to choose to play roles other than victims. And if you are going to choose to have a relationship with a vendor, why wouldn’t you choose for that relationship to be something other than victim?

    Five years ago, I wrote a post about how people who complained bitterly about how unhappy they were with their LMS vendors tended to ignore the procurement practices of their colleagues and their institution that all but guaranteed their dissatisfaction. That post was called Dammit, the LMS. It received quite a bit of attention. Even people who hated it admitted to me that they thought it was correct.

    Sadly, not much has changed since then.

  • Instructure DIG and Student Early Warning Systems

    Instructure DIG and Student Early Warning Systems

    EdSurge‘s Tony Wan is first out of the blocks with an Instructurecon coverage article this year. (Because of my recent change in professional focus, I will not be on the LMS conference circuit this year.) Tony broke some news in his interview with CEO Dan Goldsmith with this tidbit about the forthcoming DIG analytics product:

    One example with DIG is around student success and student risk. We can predict, to a pretty high accuracy, what a likely outcome for a student in a course is, even before they set foot in the classroom. Throughout that class, or even at the beginning, we can make recommendations to the teacher or student on things they can do to increase their chances of success.

    Instructure CEO Dan Goldsmith

    There isn’t a whole lot of detail to go on here, so I don’t want to speculate too much. But the phrase “before they even set foot in the classroom” is a clue as to what this might be. I suspect that the particular functionality he is talking about is what’s known as an “student retention early warning system.”

    Or maybe not. Time will tell.

    Either way, it provides me with the thin pretext I was looking for to write a post on student retention early warning systems. It seems like a good time to review the history, anatomy, and challenges of the product category since I haven’t written about them in quite a while and they’ve become something of a fixture. The product category is also a good case study in why tool that could be tremendously useful in supporting students who need help the most often fails to live up to either its educational or commercial potential.

    The archetype: Purdue Course Signals

    The first retention early warning system that I know of was Purdue Course Signals. It was an experiment undertaken by Purdue University to—you guessed it—increase student retention, particularly in the first year of college, when students tend to drop out most often. The leader of the project, John Campbell, and his fellow researchers Kim Arnold and Matthew Pistilli, looked at data from their Student Information System (SIS) as well as the LMS to see if they could predict and influence students. Their first goal was to prevent them from dropping courses, but they ultimately wanted to prevent those students from dropping out.

    They looked at quite a few variables from both systems, but the main results they found are fairly intuitive. On the LMS side, the four biggest predictors they found for students staying in the class (or, conversely, for falling through the cracks) where

    1. Student logins (i.e., whether they are showing up for class)
    2. Student assignments (i.e., whether they are turning in their work)
    3. Student grades (i.e., whether their work is passing)
    4. Student discussion participation (i.e., are they participating in class)

    All four of these variables were compared to the class average, because not all instructors were using the LMS in the same way. If, for example, the instructor wasn’t conducting class discussions online, then the fact that a student wasn’t posting on the discussion board wouldn’t be a meaningful indicator.

    These are basically four of the same very generic criteria that any instructor would look at to determine whether a student is starting to get in trouble. The system is just more objective and vigilant in applying these criteria than instructors can be at times, particularly in large classes (which is likely to be the norm for many first-year students). The sensitivity with which Course Signals would respond to those factors would be modified by what the system “knew” about the students from their longitudinal data—their prior course grades, their SAT or ACT scores, their biographical and demographic data, and so on. For example, the system would be less “concerned” about an honors student living on campus who doesn’t log in for a week than about a student on academic probation who lives off-campus.

    In the latter case, the data used by the system might not normally be accessible, or even legal, for the instructor to look at. For example, a disability could be a student retention risk factor for which there are laws governing the conditions under which faculty can be informed. Of course, instructors don’t have to be informed in order for the early warning system to be influenced by the risk factor. One way to think about a way that this sensitive information could be handled is like a credit score. There is some composite score that informs the instructor that the student is at increased risk based on a variety of factors, some of which are private to the student. The people who are authorized to see the data can verify that the model works and that there is legitimate reason to be concerned about the student, but the people who are not authorize are only told that the student is considered at-risk.

    Already, we are in a bit of an ethical rabbit hole here. Note that this is not caused by the technology. At least in my state, the great Commonwealth of Massachusetts, instructors are not permitted to ask students about their disabilities, even though that knowledge could be very helpful in teaching those students. (I should know whether that’s a Federal law, but I don’t.) Colleges and universities face complicated challenges today, in the analog world, with the tensions between their obligation to protect student privacy and their affirmative obligation to help the students based on what they know about what the students need. And this is exactly the way John Campbell characterized the problem when he talked about it. This is not a “Facebook” problem. It’s a genuine educational ethical dilemma.

    Some of you may remember some controversy around the Purdue research. The details matter here. Purdue’s original study, which showed increased course completion and improved course grades, particularly for “C” and “D” students, was never questioned. It still stands. A subsequent study, which purported to show that student gains persisted in subsequent classes, was later called into question. You can read the details of that drama here. (e-Literate played a minor role in that drama by helping to amplify the voices of the people who caught the problem in the research.)

    But if you remember the controversy, it’s important to remember three things about it. First, the original research about persistence was not ever called into question. Second, the subsequent finding was not disproven; rather, there was a null hypothesis. We have proof neither for nor against the hypothesis that the Perdue system can produce longer term effects. And finally, the biggest problem that controversy exposed was with university IR departments releasing non-peer-reviewed research papers that staff researchers have no power to respond to on their own when they get criticized. That’s worth exploring further some other time, but for now, the point is that the process problem was the real story. The controversy didn’t invalidate the fundamental idea behind the software.

    Since then

    Since then, we’ve seen lots of tinkering with the model on both the LMS and SIS sides of the equation. Predictive models have gotten better. Both Blackboard and D2L have some sort of retention early warning products, as do Hobsons, Civitas, EAB, and HelioCampus, among others. There were some early problems related to a generational shift in data analytics technologies; most LMSs and SISs were originally architected well before the era when systems were expected to provide the kind of high-volume transactional data flows needed to perform near-real-time early warning analytics. Those problems have increasingly been either ironed out or, at least, worked around. So in one sense, this is a relatively mature product category. We have a pretty good sense of what a solution looks like and there are a number of providers in the market right now with variations on on the theme.

    In a second sense, the product category hasn’t fundamentally changed since Purdue created Course Signals over a decade ago. We’ve seen incremental improvements to the model, but no fundamental changes to it. Maybe that’s because the Purdue folks pretty much nailed the basic model for a single institution on the first try. What’s left are three challenges that share the common characteristic of becoming harder when converted from an experiment by a single university to a product model supported by a third-party company. At the same time, They fall on different places on the spectrum between being primarily human challenges and primarily technology challenges. The first, the aforementioned privacy dilemma, is mostly a human challenge. It’s a university policy issue that can be supported by software affordances. The second, model tuning, is on the opposite end of the spectrum. It’s all about the software. And the third, which is the last mile problem from good analytics to actual impact, is somewhere in the messy middle.

    Three significant challenges

    I’ve already spent some time on the student data privacy challenge specific to these systems, so I won’t spend much more time on it here. The macro issue is that these systems sometimes rely on privacy-sensitive data to determine—with demonstrated accuracy—which students are most likely to need extra attention to make sure they don’t fall through the cracks. This is an academic (and legal) problem that can only be resolved by academic (and legal) stakeholders. The role of the technologists is to make the effectiveness and the privacy consequences of various software settings both clear and clearly in the control of the appropriate stakeholders. In other words, the software should support and enable appropriate policy decisions rather than obscuring or impeding them. At Purdue, where Course Signals was not a product that was purchased but a research initiative that had active, high-level buy-in from academic leadership, these issues could be worked through. But a company selling the product into as many universities as possible with differing levels of sophistication and policy-making capability in this area, the best the vendor can do is build a transparent product and try to educate their customers as best as they can. You can lead a horse to water and all that.

    On the other end of the human/technology spectrum, there is an open question about the degree to which these systems can be made accurate without individual hand tuning of the algorithms for each institution. Purdue was building a system for exactly one university, so it didn’t face this problem. We don’t have good public data on how well its commercial successors work out of the box. I am not a data scientist, but I have had this question raised by some of the folks who I trust the most in this field. That, in turn, means that each installation of the product would require a significant services component, which would raise the cost and make these systems less affordable to the access-oriented institutions that need them the most. This is not a settled question; the jury is still out. I would like to see more public proof points that have undergone some form of peer review.

    And in the middle, there’s the question of what to do with the predictions in order to produce positive results. Suppose you know which students are more likely to fail the course on Day 1. Suppose your confidence level is high. Maybe not Minority Report-level stuff—although, if I remember the movie correctly, they got a big case wrong, didn’t they?—but pretty accurately. What then? At my recent IMS conference visit, I heard one panelists on learning analytics (depressingly) say, “We’re getting really good at predicting which students are likely to fail, but we’re not getting much better at preventing them from failing.”

    Purdue had both a specific theory of action for helping students and good connections among the various program offices that would need to execute that theory of action. Campell et al believed, based on prior academic research, that students who struggle academically in their first year of college are likely to be weak in a skill called “help-seeking behavior.” Academically at risk students often are not good at knowing when they need help and they are not good at knowing how to get it. Course Signals would send students carefully crafted and increasingly insistent emails urging them to go to the tutoring center, where staff would track which students actually came. The IR department would analyze the results. Over time, the academic IT department that owned the Course Signals system itself experimented with different email messages, in collaboration with IR, and figured out which ones were the most effective at motivating students to take action and seek help.

    Notice two critical features to Purdue’s method. First, they had a theory about student learning—in this case, learning about productive study behaviors—that could be supported or disproven by evidence. Second, they used data science to test a learning intervention that they believed would help students based on their theory of what is going on inside the students’ heads. This is learning engineering. It also explains why the Purdue folks had reason to hypothesize that the effects of using Course Signals might persist with students after they stopped using the product. They believed that students might learn the skill from the product. The fact that the experimental design of their follow-up study was flawed doesn’t mean that their hypothesis was a bad one.

    When Blackboard built their first version of a retention early warning system—one, it should be noted, that is substantially different from their current product in a number of ways—they didn’t choose Purdue’s theory of change. Instead, gave the risk information to the instructors and let them decide what to do with it. As have many other designers of these systems. While everybody that I know of copied Purdue’s basic analytics design, nobody that I know—at least no commercial product developers that I know of—copied Purdue’s decision to put so much emphasis on student empowerment first. Some of this has started to enter product design in more recent years now that “nudges” have made the leap from behavioral economics into consumer software design. (Fitbit, anyone?) But the faculty and administrators remain the primary personas in the design process for many of these products. (For non-software designers, a “persona” is an idealized person that you imagine that you’re designing the software for.)

    Why? Two reasons. First, students don’t buy enterprise academic software. So however much the companies that design these products may genuinely want to serve students well, their relationship with them is inherently mediated. The second reason is the same as with the previous two challenges in scaling Purdue’s solution. Individual institutions can do things that companies can’t. Purdue was able to foster extensive coordination between academic IT, institutional research, and the tutoring center, even though those three organizations live on completely different branches of the organizational chart in pretty much every college and university that I know. An LMS vendor has no way of compelling such inter-departmental coordination in its customers. The best they can do is give information to a single stakeholder who is most likely to be in a position to take action and hope that person does something. In this case, the instructor.

    One could imagine different kinds of vendor relationships with a service component—a consultancy or an OPM, for example—where this kind of coordination would be supported. One could also imagine colleges and universities reorganizing themselves and learning new skills to become better at the sort of cross-functional cooperation for serving students. If academia is going to survive and thrive in the changing environment it finds itself in, both of these possibilities will have to become far more common. The kinds of scaling problems I just described in retention early warning systems are far from unique to that category. Before higher education can develop and apply the new techniques and enabling technologies it needs to serve students more effectively with high ethical standards, we first need to cultivate an academic ecosystem that can make proper use of better tools.

    Given a hammer, everything looks pretty frustrating if you don’t have an opposable thumb.