The “Ed Tech” category includes posts about educational technology products themselves, including LMSs and other learning platforms, adaptive learning and other digital curricular materials products, learning analytics, and educational apps of all types. It also includes technical aspects of ed tech products, especially interoperability.
I’m deeply saddened to tell you that Argos Education is winding down. The current venture funding market conditions proved too difficult for us to raise the money that we needed. Venture investments as a whole are down nearly 60% from their peak a year ago. Early-stage EdTech investments are practically non-existent with no change on the horizon. We are forced to face economic realities regardless of how much we still believe in Argos. Our employees are departing with a couple of us continuing on part-time on a volunteer basis to ensure continuity of support for our customers through this transition. The company is effectively being put into hibernation.
I have learned many lessons on this two-year journey, some of which I may share sooner, some later, and some not at all, at least in a public forum. This is not the time for that. Right now, I want to talk about how the work continues and about what comes next for the Argos team, including me.
Our legacy
The Argos team is proud of what we have accomplished. We helped create and coordinate an open-source coalition that preserved tens of millions of dollars worth of grant-funded courseware that would have been stranded when Smart Sparrow was end-of-lifed. That content will now continue to serve tens of thousands of students every year. Because the platform is open-source, these carefully crafted learning experiences will not be stranded regardless of what happens to Argos.
On the contrary, the future is bright for the platform, called OLI Torus. During the migration of ASU’s Inspark and Infiniscope programs from Smart Sparrow to Argos, we served more than 35,000 enrollments and 350 educators on 90 campuses. Because of the highly interactive nature of these courses, we served more than 15 million scored assessments—an average of about 450 per student. That is what continuous formative assessment looks like. Going forward, the ASU programs are 100% migrated going forward while Carnegie Mellon’s OLI program is beginning its own migration. By this time next year, the platform will be serving over 100,000 annual enrollments at over 450 colleges and universities, plus K12. The platform remains under active development and the collaborators continue to attract grant money for new features and new courses. They are jointly building an equity-minded Chemistry course. And OLI will continue the grant work we started together to build end-to-end experimental design, delivery, and data capabilities right into the platform.
All of this is being built on the backbone of the next generation of the OLI platform and the 20 years of research and applied learning science knowledge it represents. The combination of this knowledge embodied in its new and highly innovative architecture, the addition of the design concepts from Sparrow, and some innovative thinking that was inspired by the fusion have led to a platform unlike any I have seen on the market. It is, without a doubt, a third-wave EdTech platform. (If I write about Argos in the near future, this will likely be one of the topics.)
It’s a bittersweet moment. While I am absolutely crushed that my colleagues and I will not be able to continue working together toward our larger vision, I am equally mindful that many failed startup founders end with nothing to show but debt, exhaustion, and sadness. My co-founder Curtiss Barnes and I have all this, for sure, but we also have the knowledge that we and our Argos colleagues were midwives for something new and important that will last beyond our active facilitation of it. We also proved that it is possible to build a biodegradable EdTech company. While we believe that Argos could have continued to catalyze major positive change, we have protected our academic partners from catastrophic harm due to our business failure. This was always a design goal for us.
What’s next?
What comes next? The short answer is that I don’t know. Argos CTO Eric Hilfer has, thankfully, already found another position. Chief Research Officer Anita Delahay and Senior Advisors Nicole Sullivan and Brandi Robinson may still be available. This is the best team I’ve ever worked with. They crawled over broken glass for us. They made me a better manager, a better collaborator, and a better person. Anyone who is interested in any of them should feel free to reach out to me or to Curtiss. We’ll both gladly give them our strongest endorsements.
As for Curtiss and me, we’re at a crossroads. I’ll speak for myself here, although the two of us have talked extensively about this and I believe we are in similar places. In the short term, we’re looking for consulting work so we can bring some money in the door. If that turns into something more lasting, I’m open to it. I’ve worked with Curtiss a few times and, especially this last time, we’ve been through the fire together. I’d be up for another round. That said, as I enter what may be the last decade of my career, I find myself looking at the world differently even as the world looks increasingly different. I am opening myself up to the universe in the hopes that the next adventure finds me, whatever it may be.
If you happen to have any ideas or opportunities for any of us, please don’t be afraid to reach out.
So long and thanks for all the fish
Curtiss and I are profoundly grateful to every member of the Argos team, our friends and partners at Unicon, our friends and partners within Carnegie Mellon and ASU, our investors, and all the good people who have helped us along the way or cheered us on. The future has yet to be written. But regardless of what happens next, we believe Argos has helped make it a little brighter.
I know I’ve been on a bit of a tear lately about artificial intelligence (AI). I promise e-Literate won’t turn into the “all AI all the time” blog. That said, since I have identified it as a potential factor in a coming tipping point for education, I think it’s important that we sharpen our intuitions about what we can and can’t expect to get from it.
Plus, it’s fun.
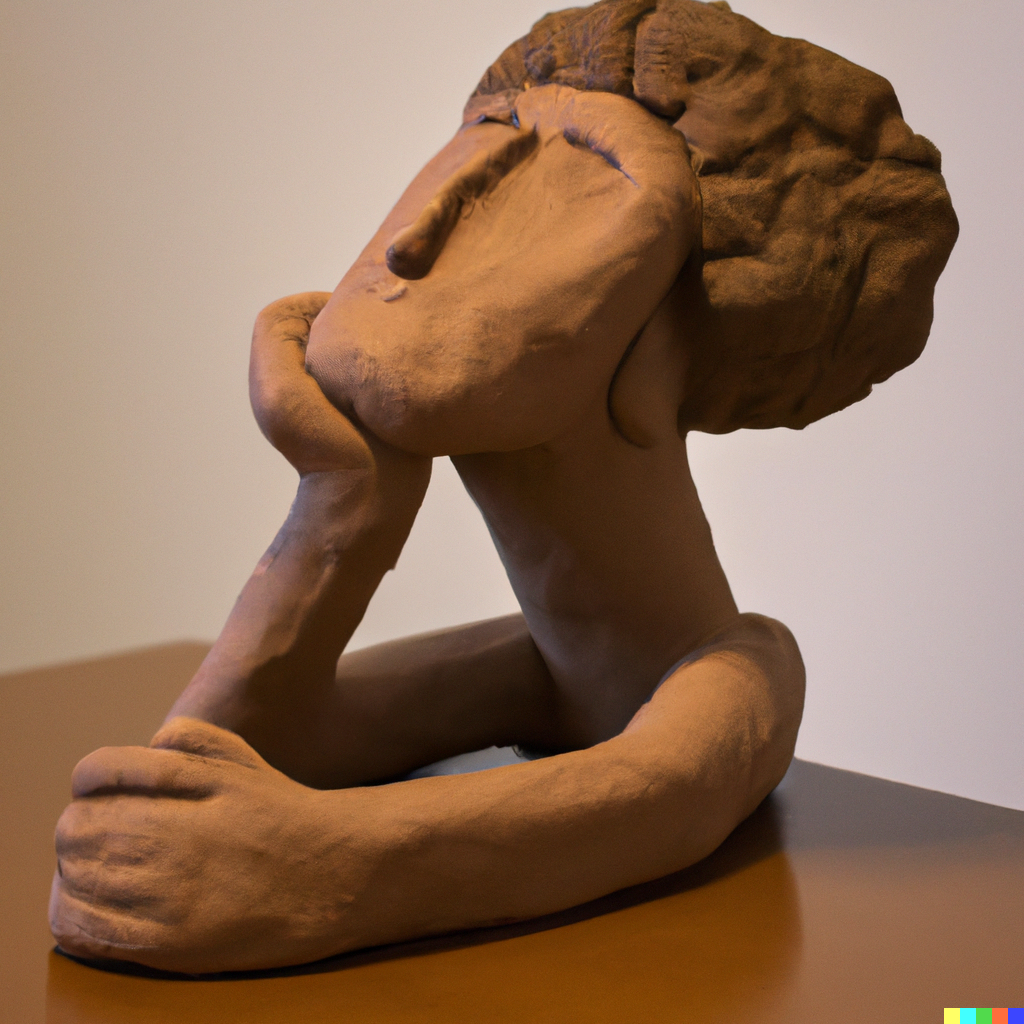
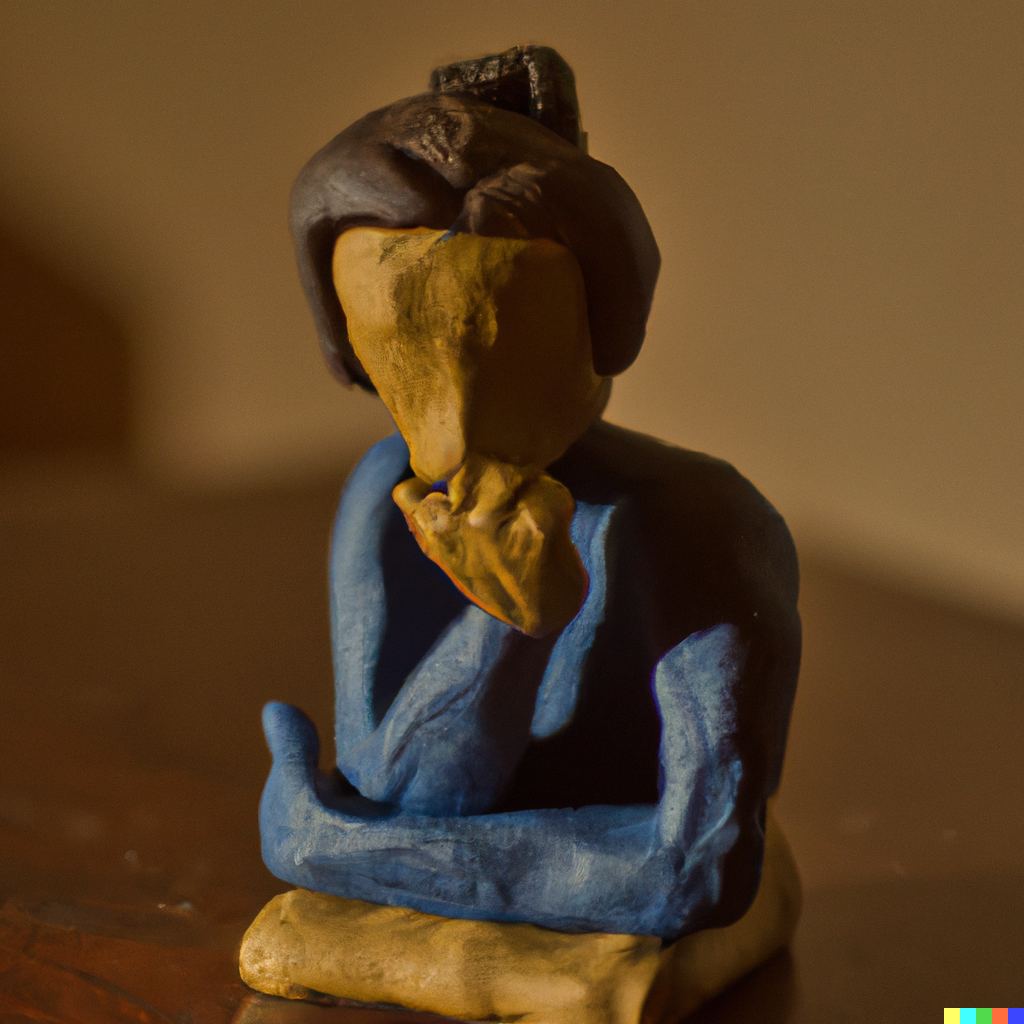
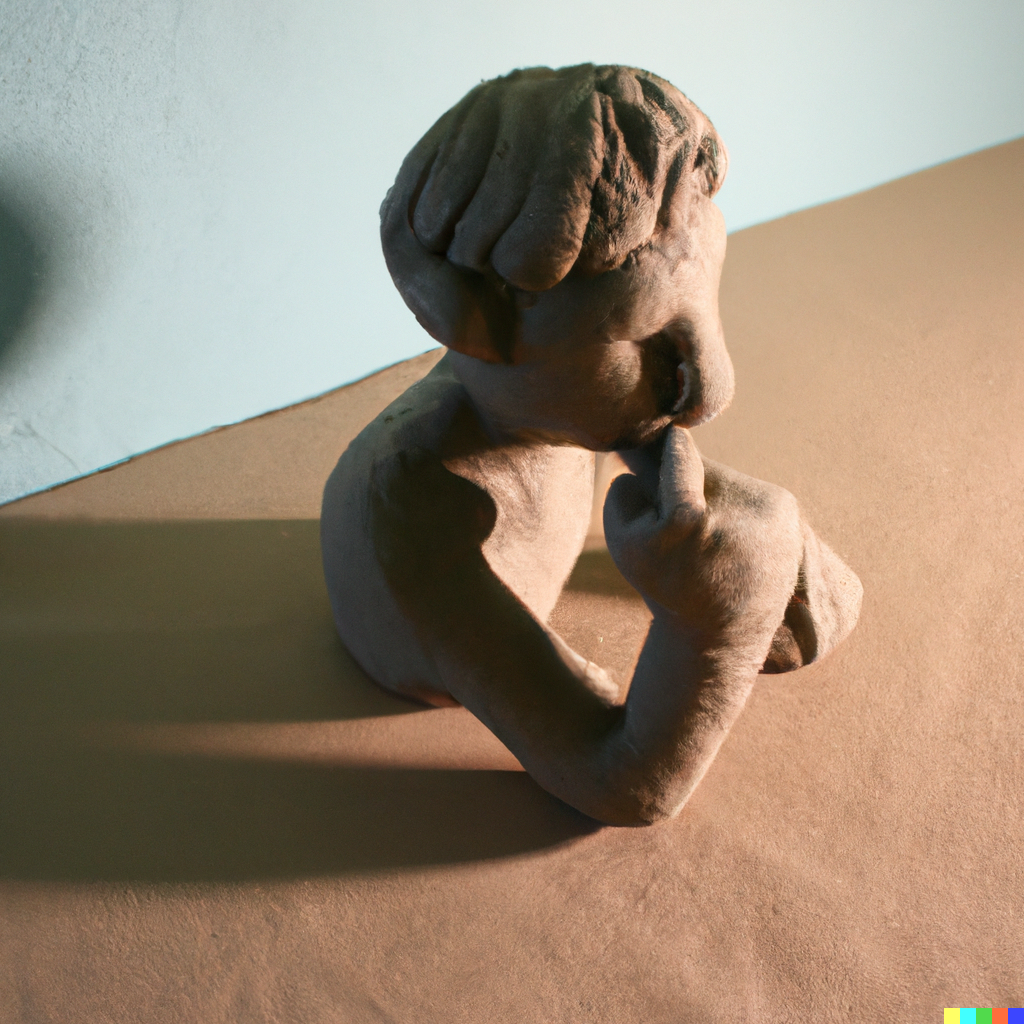
In a recent post, I quoted an interview with experts in the field who were talking about playing with AI tools that can generate images from text descriptions as a way of expressing their creativity. And in my last post, I included an image from one such tool, DALL-E 2, created from the prompt “A copy of the sculpture “The Thinker” made by a third grader using clay.”
A copy of the sculpture “The Thinker” made by a third grader using clay as interpreted by DALL-E 2
In this post, I will use this image and the tool it created as a jumping-off point for exploring the promise and limitations of large cutting-edge AI models.
Interpreting art
To say that I lack well-developed visual skills would be an understatement. When I’m thinking, which is generally whenever I’m awake, I am usually looking at the inside of my skull. I’ve been known to walk into fire hydrants and street signs with some regularity.
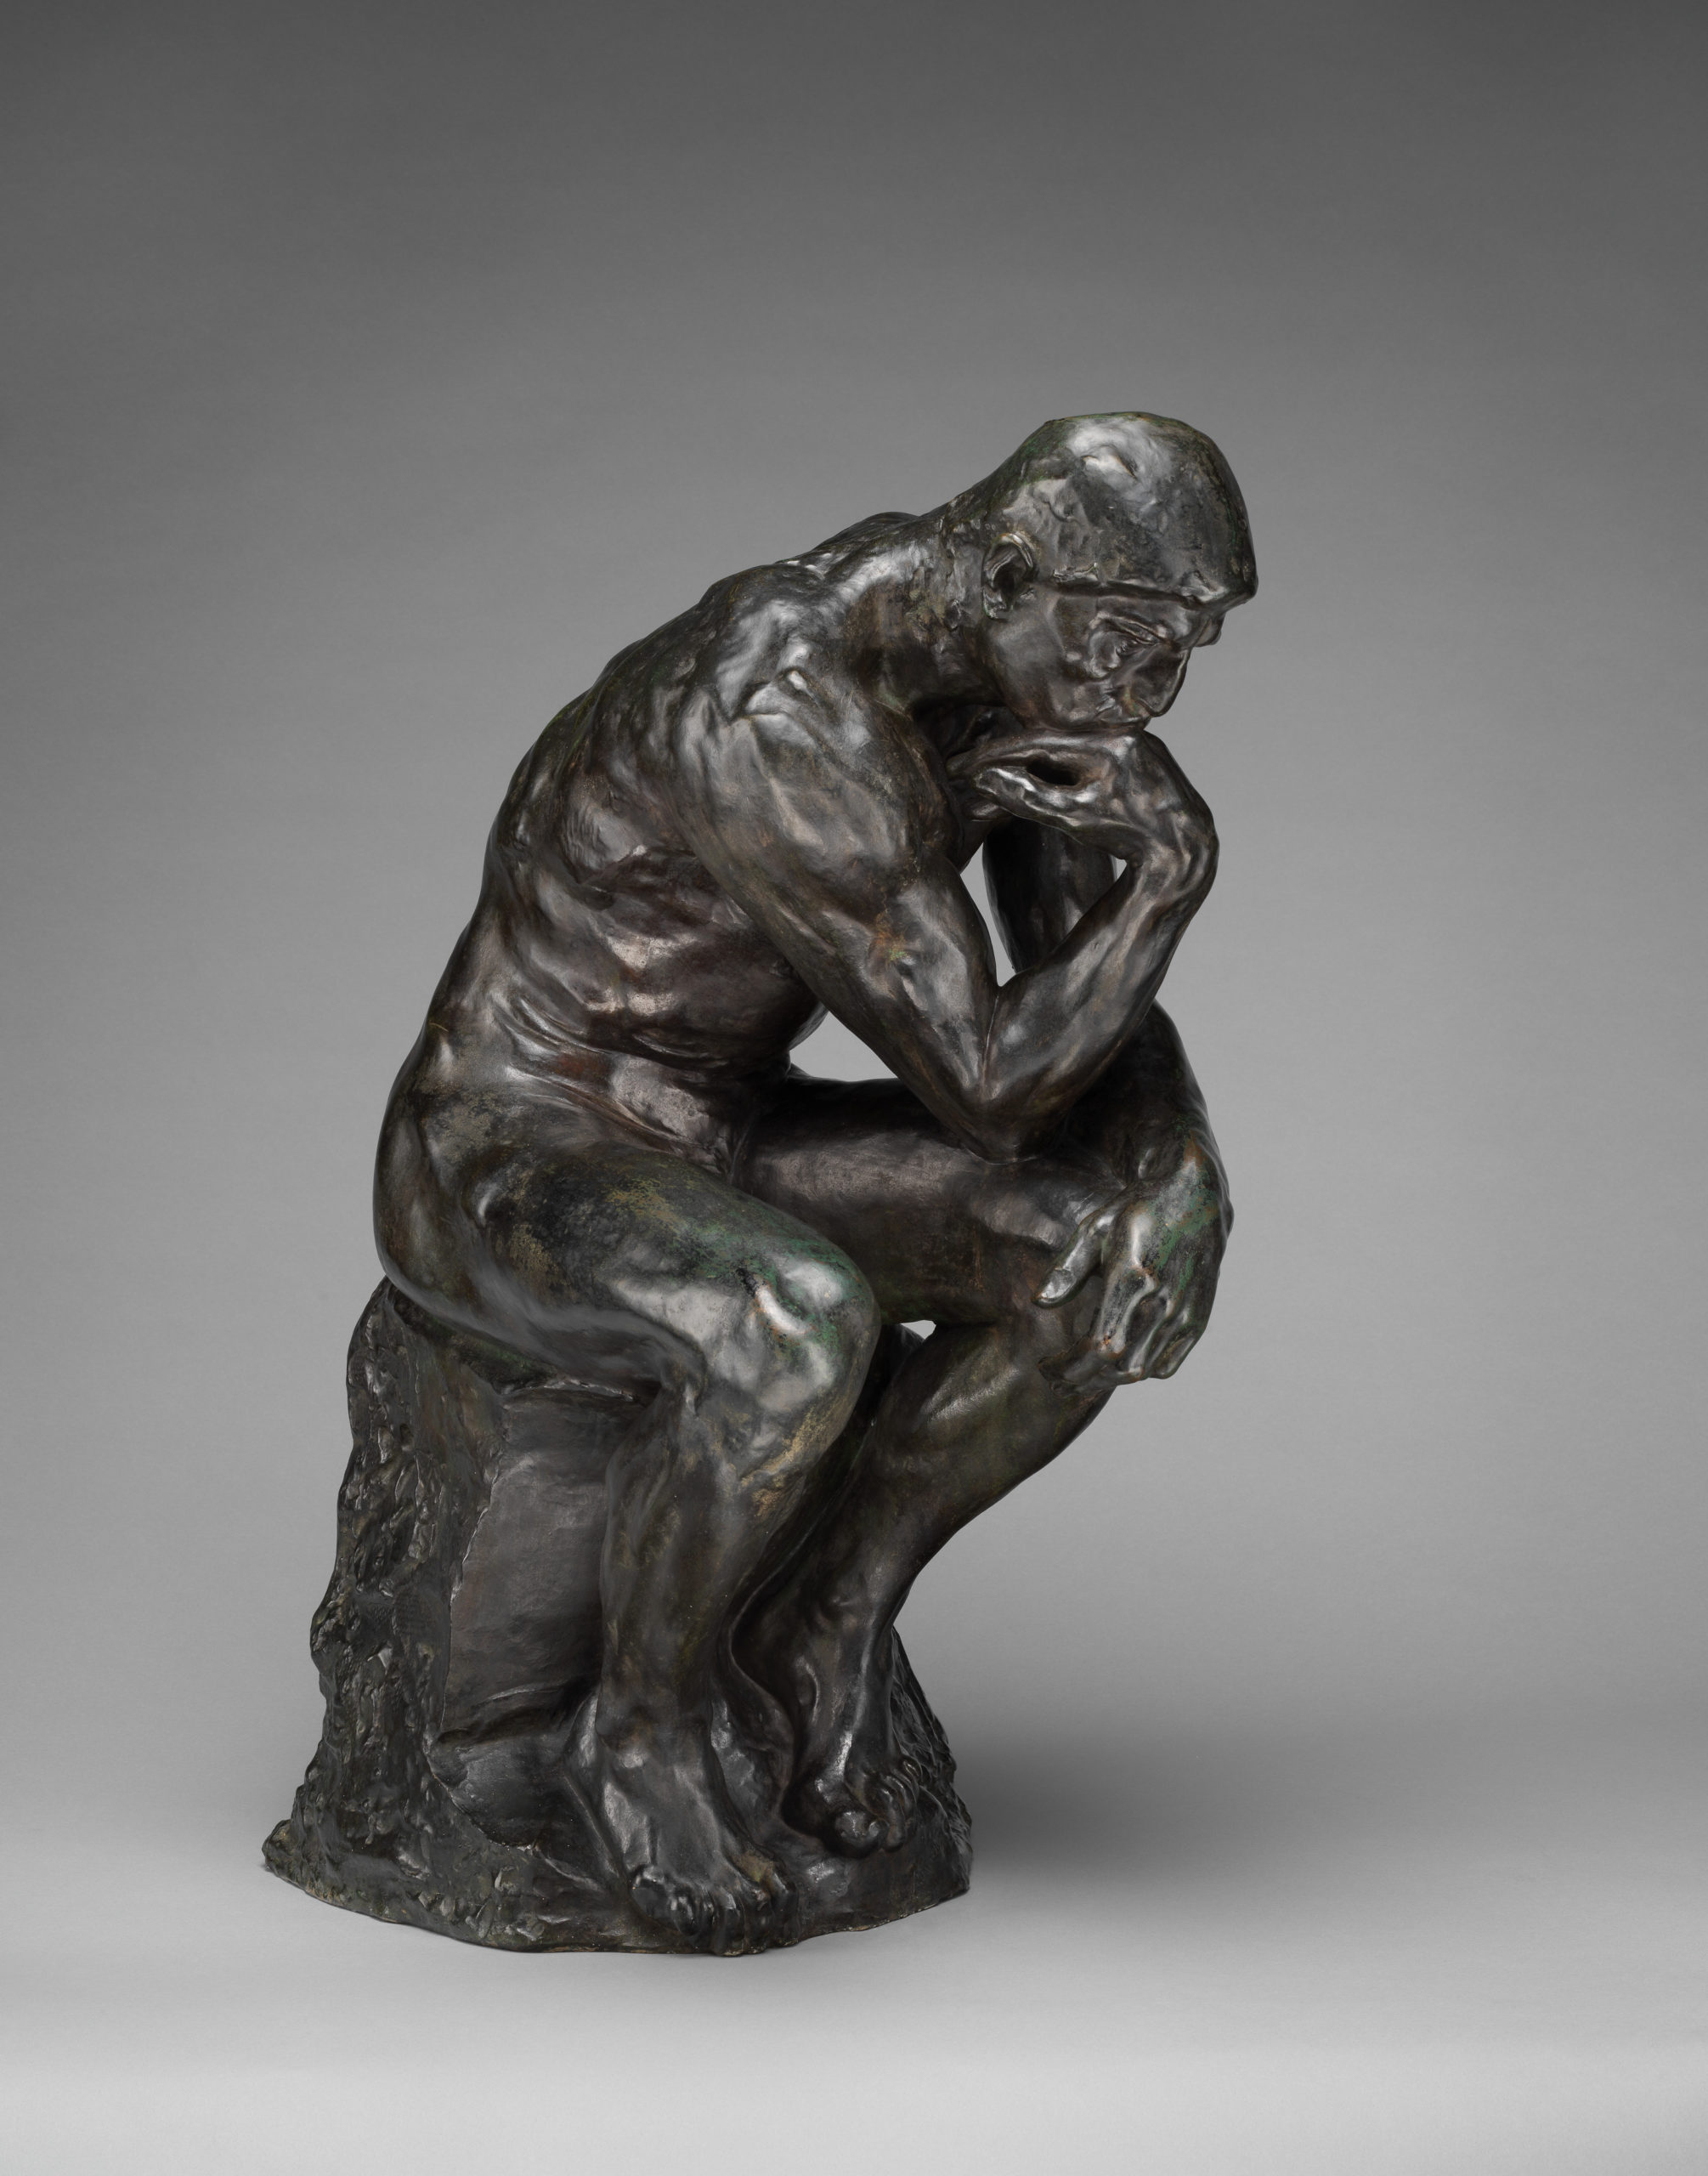
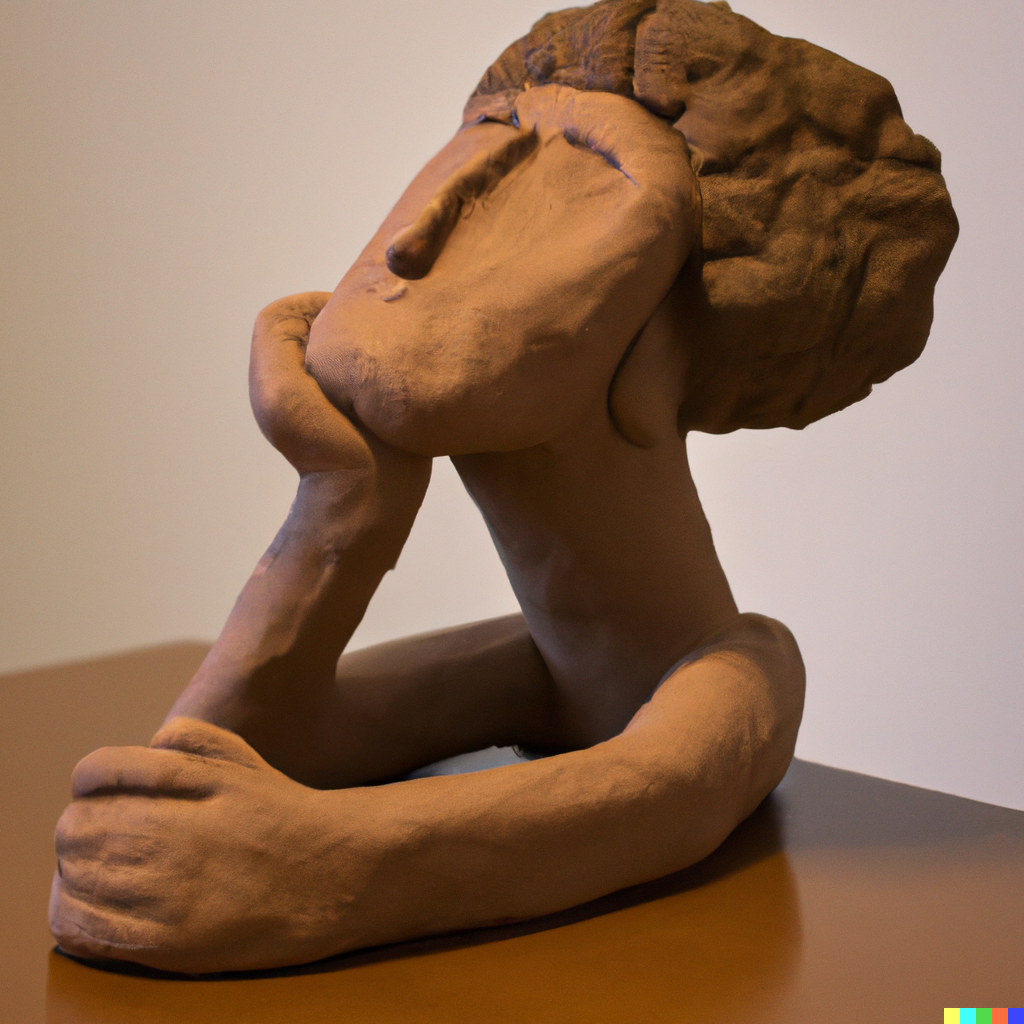
My wife, on the other hand, has an eye. She took private sculpture lessons in high school from Stanley Bleifeld. She did a brief stint at art school before turning to English. She teaches our grandchildren art. And she loves Rodin, the sculptor who created the thinker. I picked the image for the post mainly because I liked it. Her reaction to it was, “That looks nothing at all like the original. Where are the hunched shoulders? The crossed elbow? Where’s the tension in the figure? And what’s with the hair? That’s not what a third grader would make.”
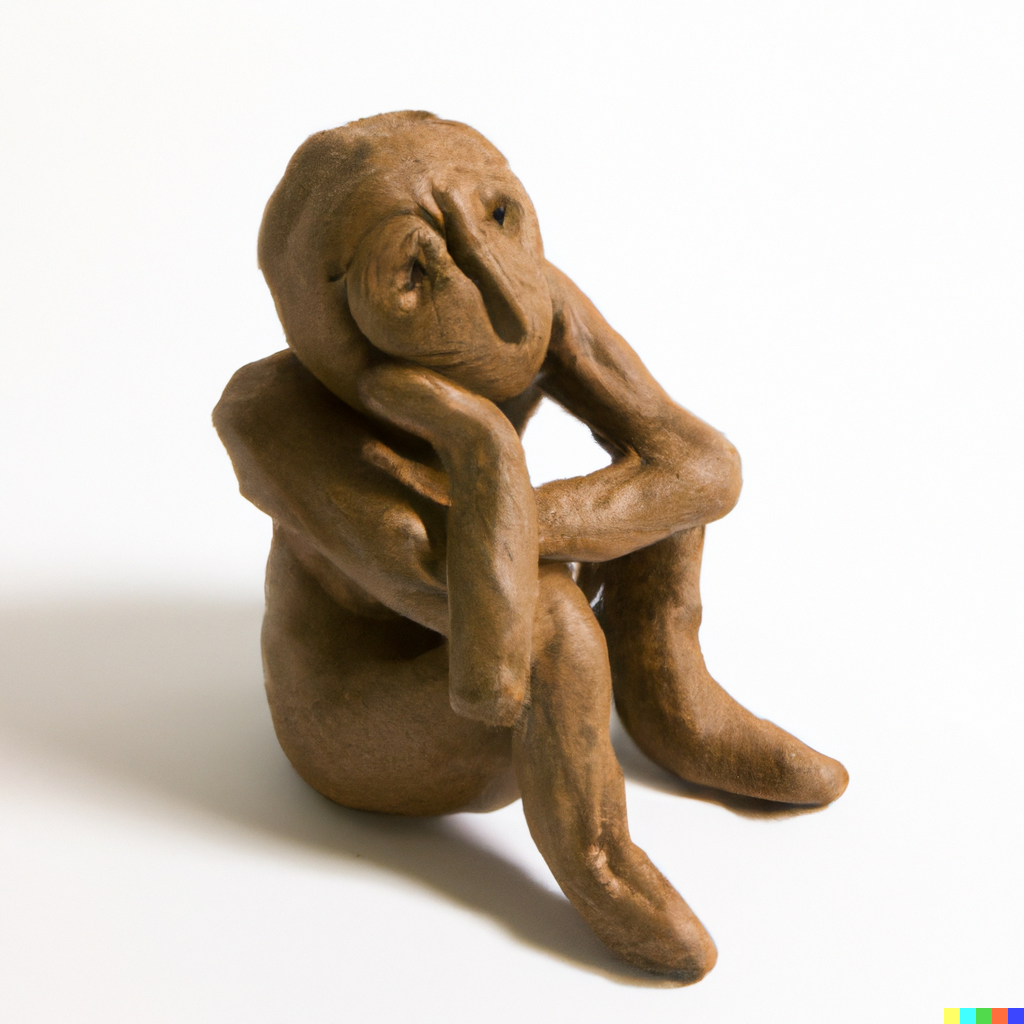
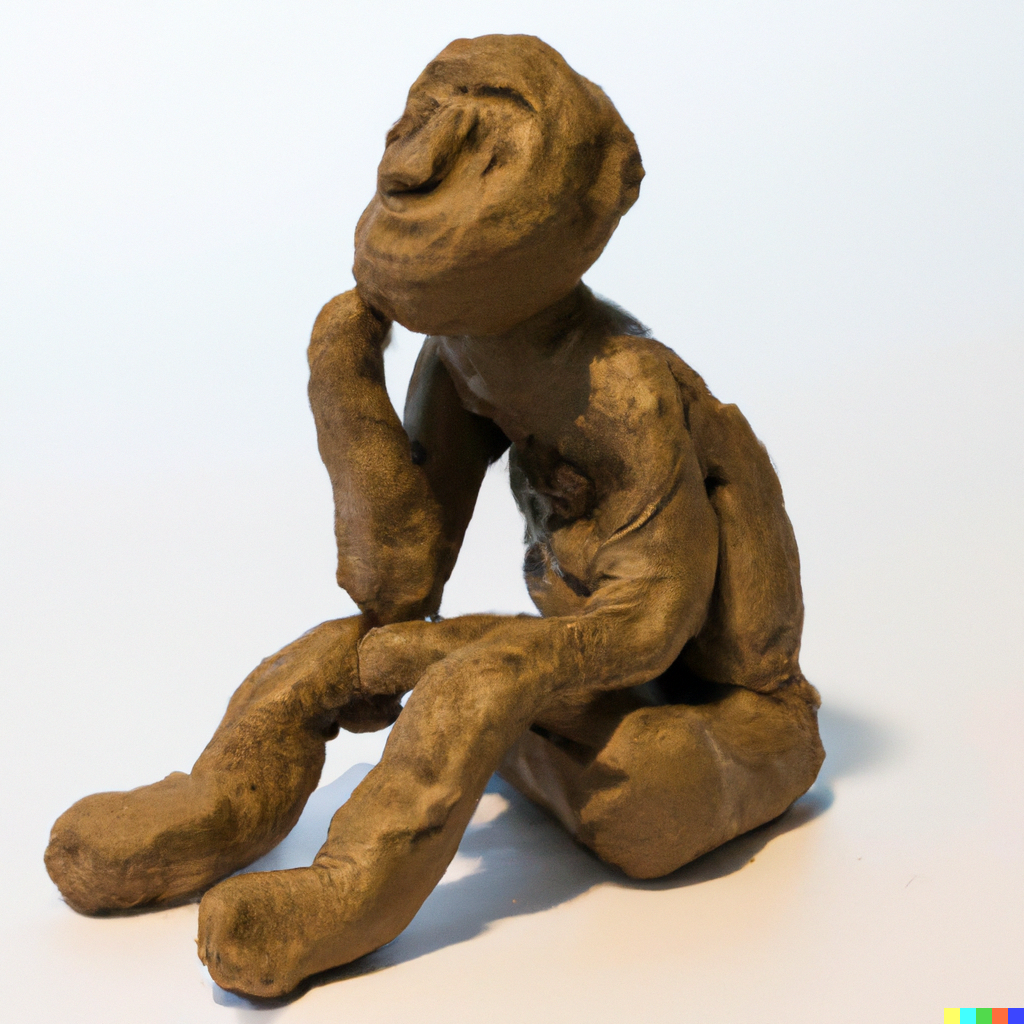
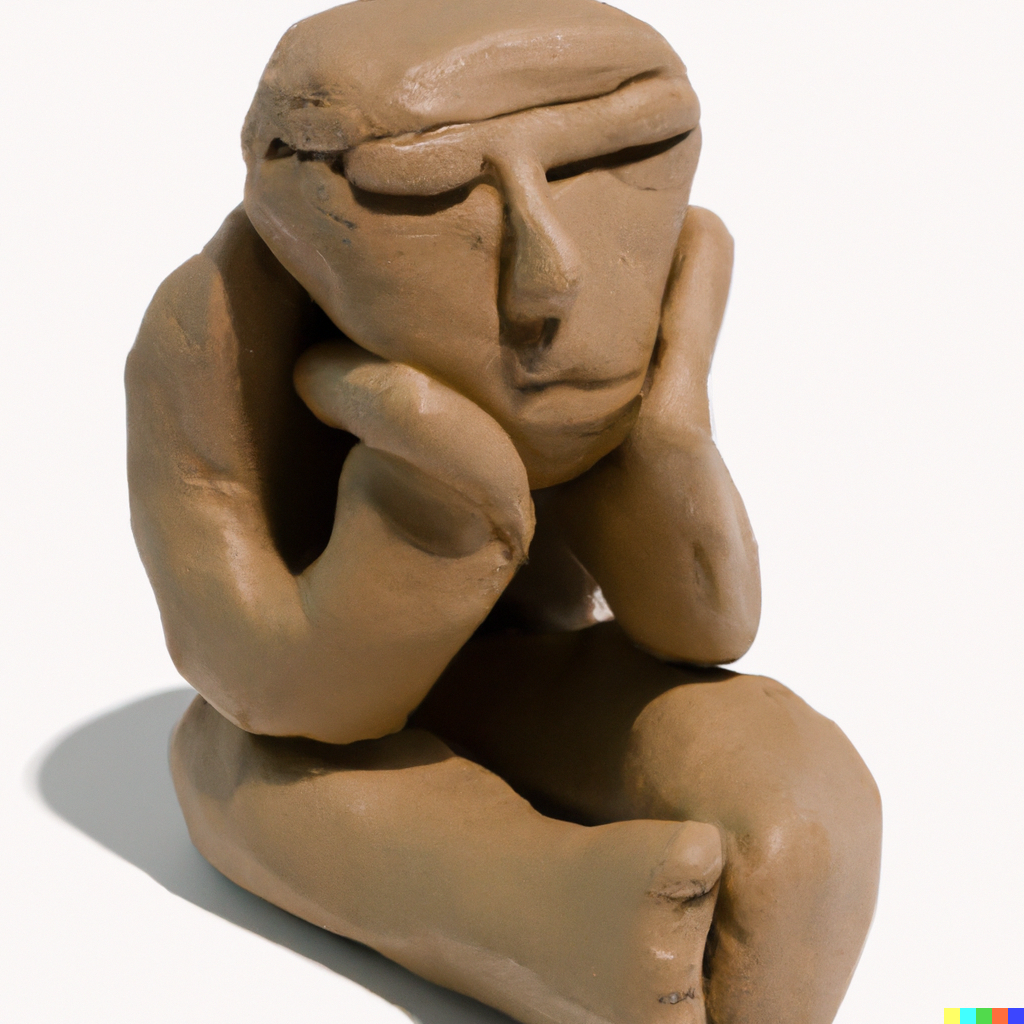
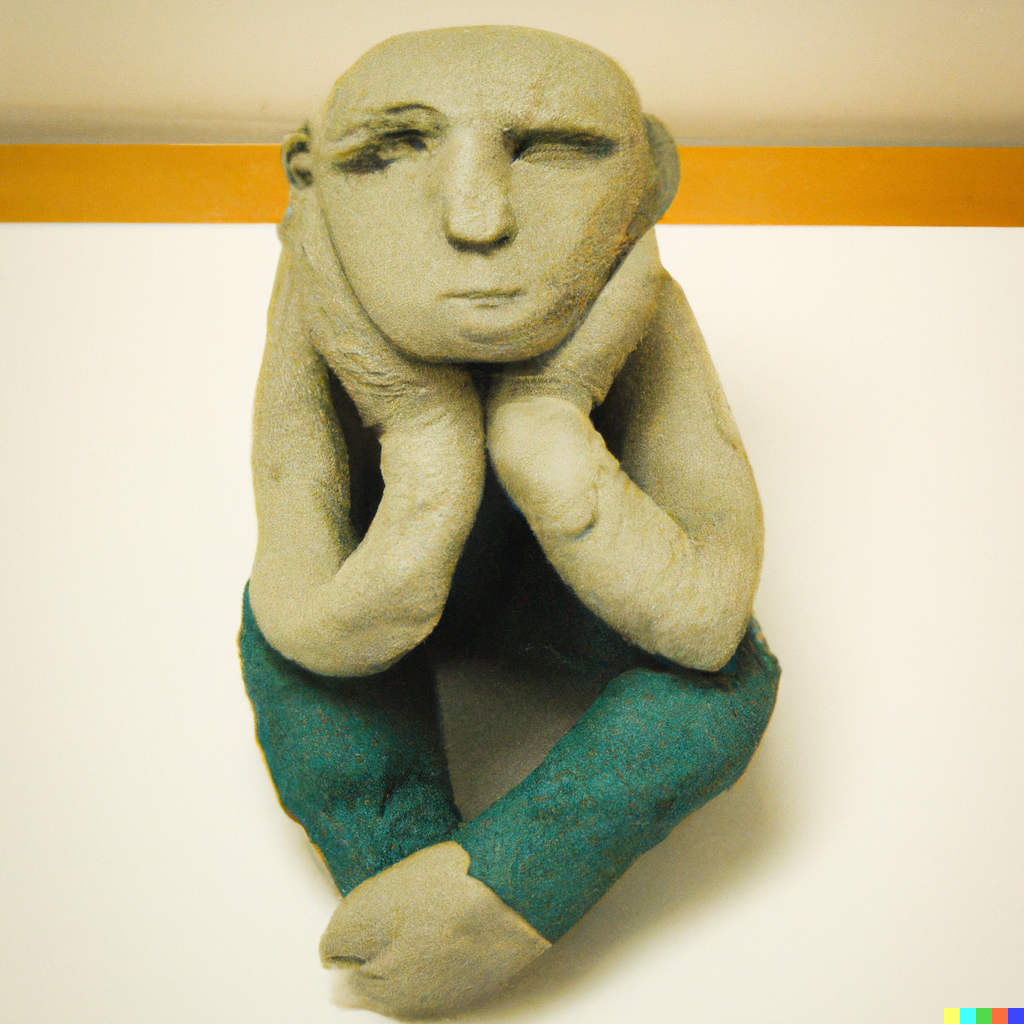
So we looked at other options. DALL-E 2 generates four options for each prompt, which you can further play with. Here are the four options that my prompt generated:
The bottom one is the one she thought best captured the original and is most like what a third grader would produce.
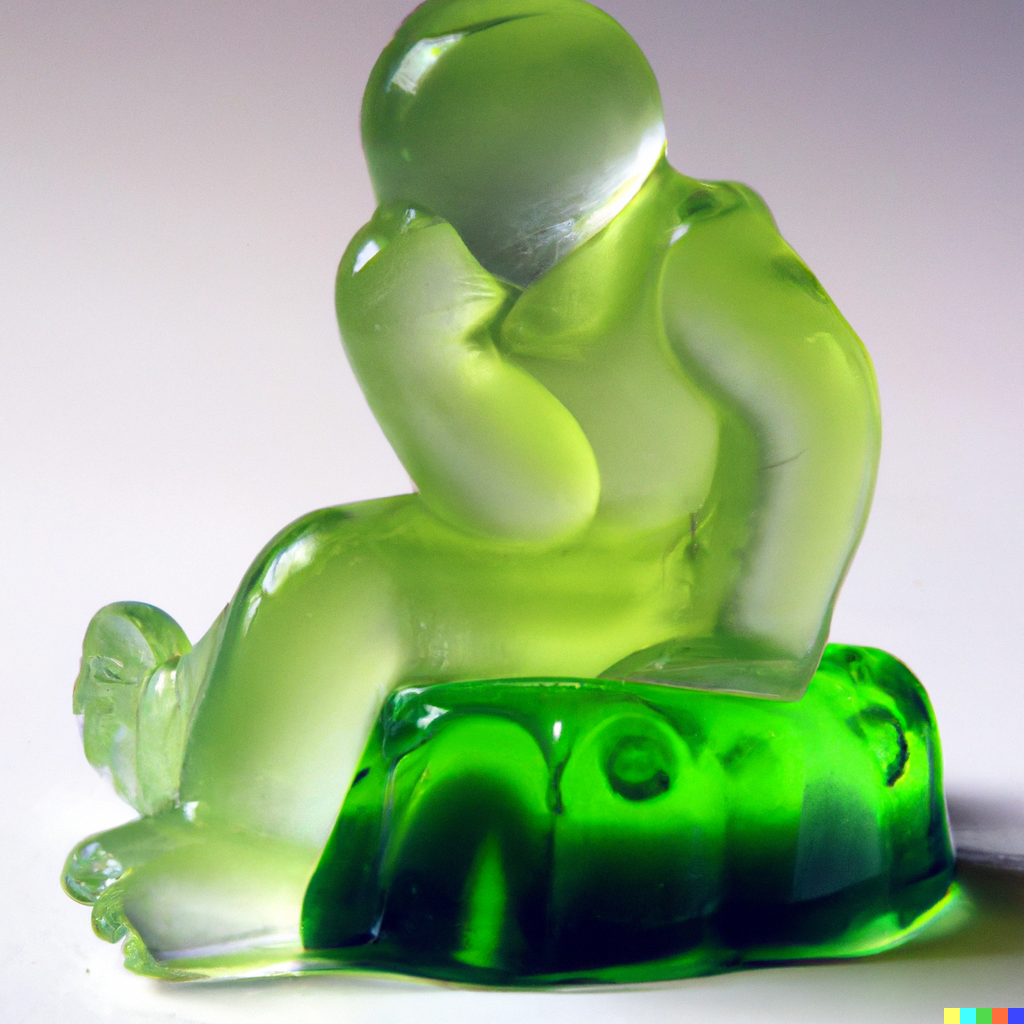
The model did well with “clay.” I tested its understanding of materials by asking it to copy the famous sculpture in Jell-O. In all four cases, it captured what Jell-O looks like very well. Here’s the best image I got:
A copy of the sculpture “The Thinker” made in green Jell-O as interpreted by DALL-E 2.
The AI clearly knows what green Jell-O looks like, down to the different shades that can come from light and food coloring. (The Jello-O mold as the seat is a nice touch.) That’s not surprising. The AI likely had many examples of well-labeled images of Jello-O on the internet.
It struggled with two aspects of the problem I gave it to solve. First, what are the salient features of The Thinker in terms of its artistic merit? Which details matter the most? And second, how would artists at different ages and developmental stages see and capture those features?
Let’s look at each in turn.
Artistic detail
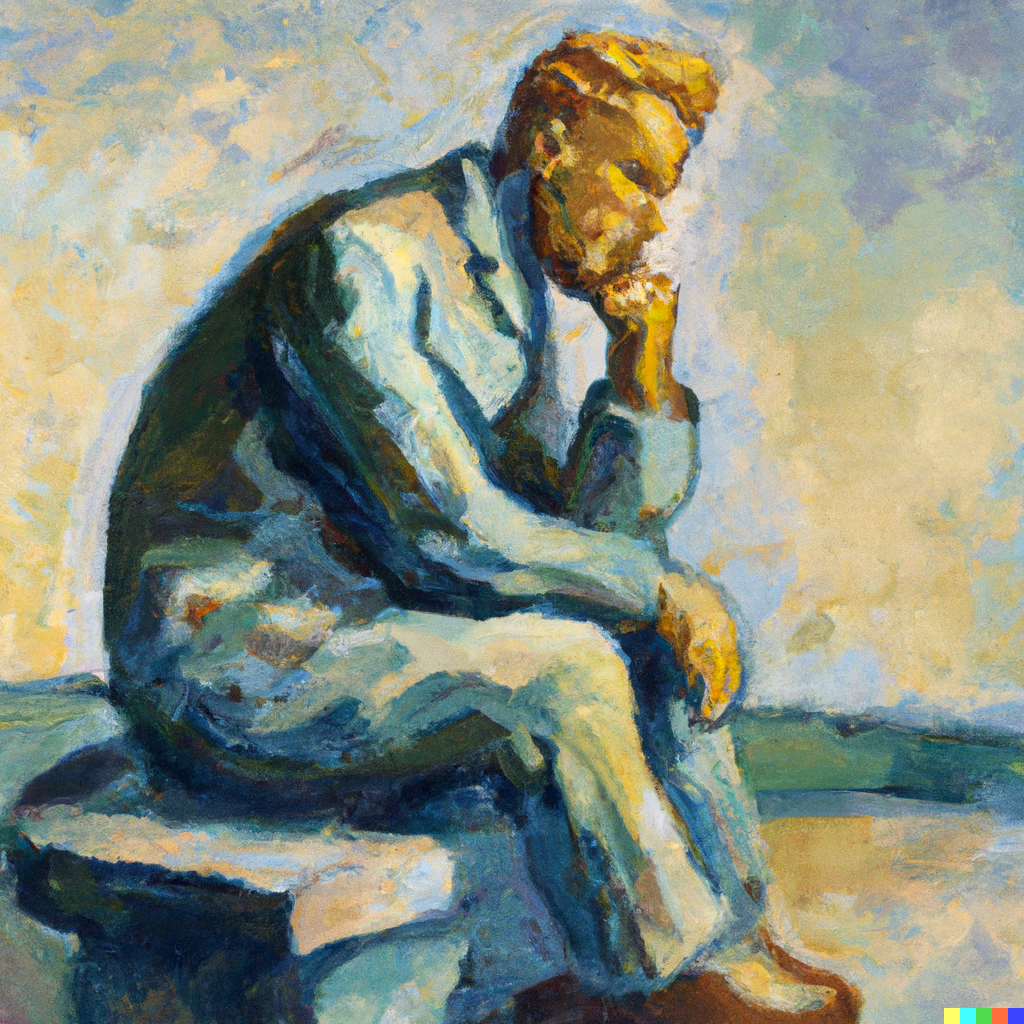
My wife has already given us a pretty good list of some salient features of the sculpture. The subject is literally and figuratively pensive. (Puns intended.) Can we get the AI to capture the art in work? My first experiment was to try asking it to interpret the sculpture through the lens of another artist. So, for example, here’s what I got when I asked it to show me a painting of the sculpture by Van Gogh:
Painting of the sculpture The Thinker by Vincent Van Gogh as interpreted by DALL-E 2.
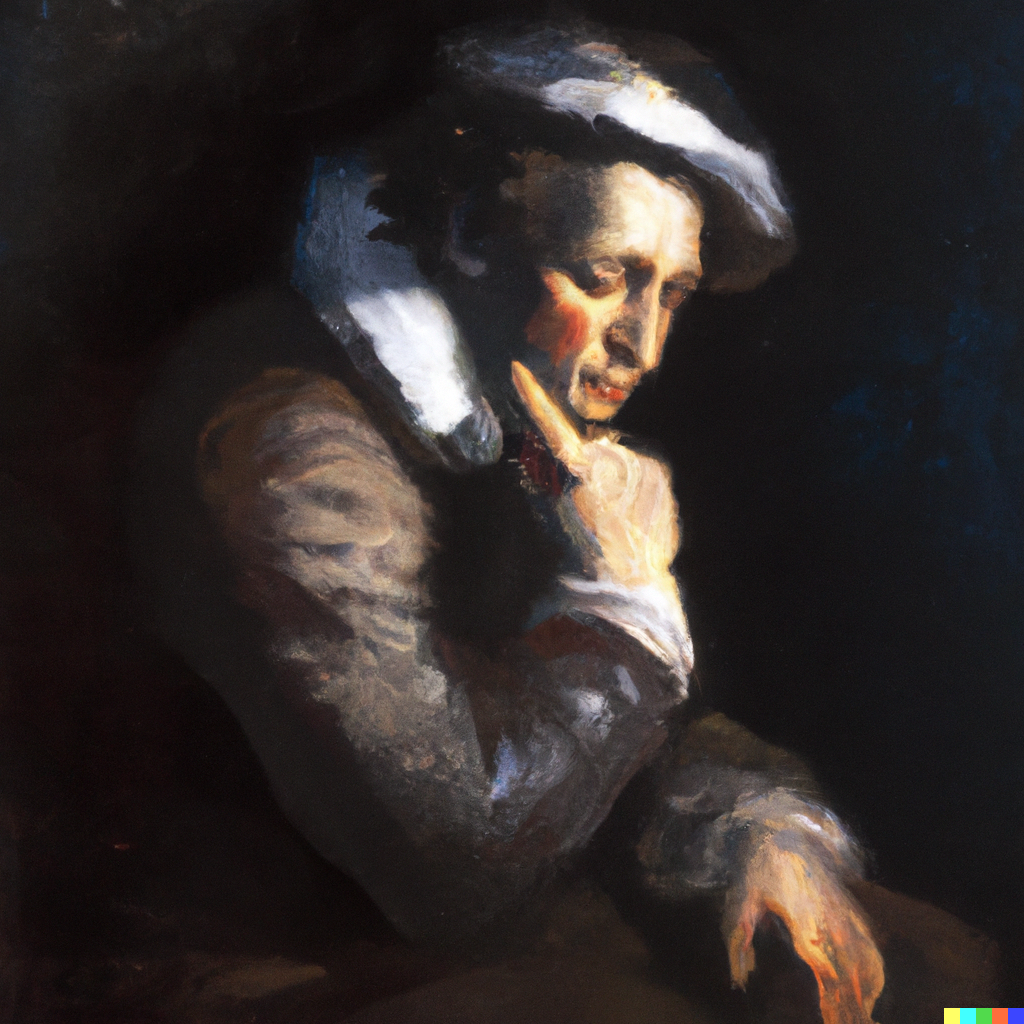
Interesting. It gets some of the tension and some of the balance between detail and lack of detail (although that balance is also consistent with Impressionist painting). But all four of the thinker images I got back for this prompt had Van Gogh’s head on them. This is probably because Van Gogh’s famous portraiture is self-portraiture. What if we tried a renowned portrait artist like Rembrandt?
Painting of the sculpture The Thinker by Rembrandt as interpreted by DALL-E 2.
I’m not sure I would describe this figure as pensive, exactly. To my (poor) eye, the tension isn’t there. Also, all four examples came back with the same white hat and ruffle. The AI has fixated on those details as essential to Rembrandt’s portraits.
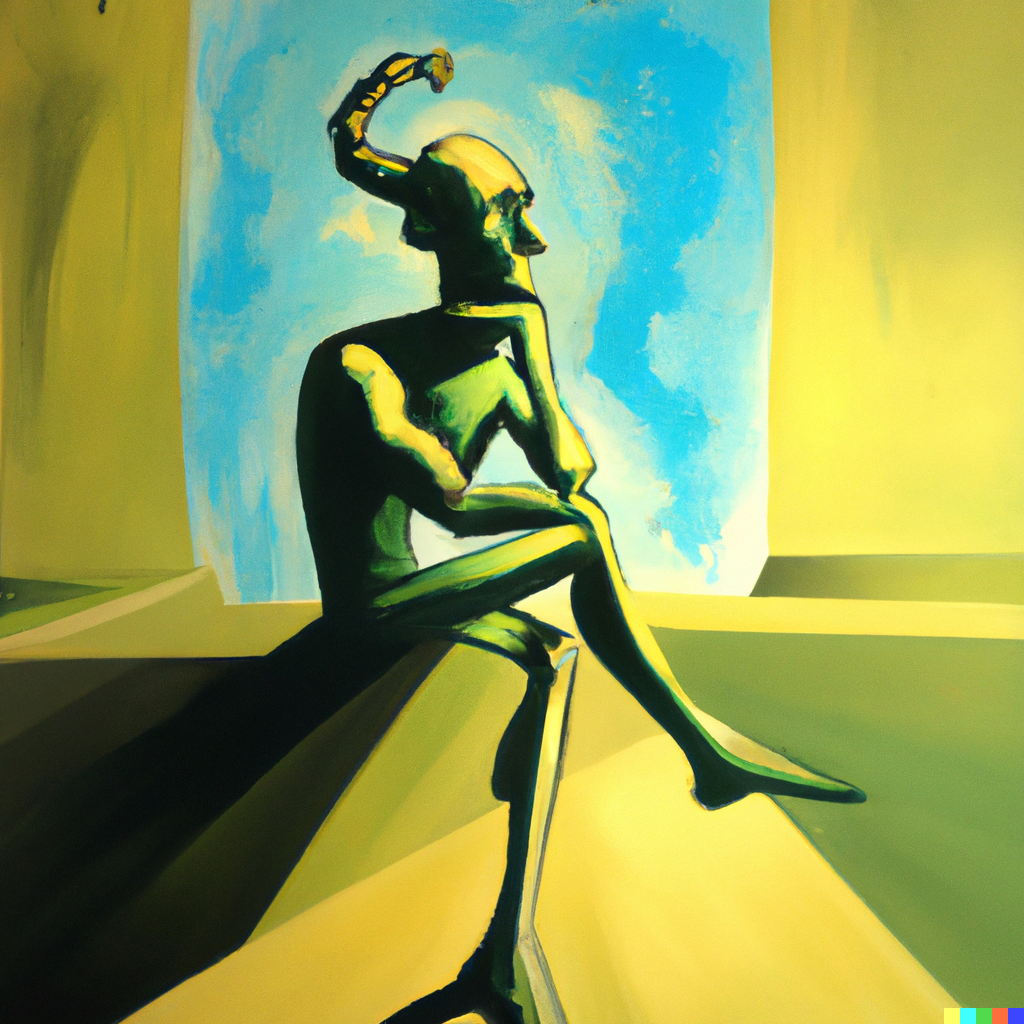
What if we stretched the model a bit by trying a less conventional artist? Here’s an example using Salvador Dalí as the artist:
Painting of the sculpture The Thinker by Salvador Dalí as interpreted by DALL-E 2.
Hmm. I’ll leave it to more visual folks to comment on this one. It doesn’t help me. I will note that all four images the AI gave me had that strange tail coming out of the back of the head. It has made a generalization about Dalí’s portraiture.
I won’t show you DALL-E 2’s interpretation of Hieronymus Bosch’s version of The Thinker, not because it’s gross but because it just didn’t work at all.
DALL-E 2 is a language model tacked onto an image model. It’s interpreting the words of the prompt based on analyzing a large corpus of text (e.g., the internet) and mashing that up with visual features it’s learned from analyzing a large corpus of images (e.g., the internet). But the connection between the two is loose. For example, even though it’s probably digested many descriptions and analyses of The Thinker, it doesn’t translate that information to the visual model. My guess is that if I built a chatbot using the underlying GPT-3 language model and asked it about the features that are considered important in The Thinker as a work of art, it could tell me. DALL-E 2 doesn’t translate that information about salient features into images.
How could you fix this if you wanted to build an application that can visually re-interpret works of art while preserving the essential features of the original? I’m going to speculate here because this gets beyond my competence. These models can be tuned by training them on special corpi of information. I’m told they’re not easy to tune; they’re so complex that their behavior can be unpredictable. But, for example, you could try to amplify the art history analyses in the information that gets sent from the language model to the visual model. I’m not sure how one would get the salient features picked up by the former to be interpreted by the latter. Maybe it could elaborate on your prompt to include details that you didn’t. I don’t know. Remember my post about the miracle, the grind, and the wall in AI? This would be the grind. It would be a lot of hard work.
Artistic development
Getting the salient details of art is hard enough. But I also asked it to interpret those details not through the eyes of a specific artist but through the eyes of a person at a particular developmental level. A third grader. GPT-3 does have a model of sorts for this. If you ask it to give answers that are appropriate for a tenth grader, you will get a different result than if you ask it to respond to a first-year college student. Much of the content it was trained on undoubtedly was labeled for grade level and/or reading level. It doesn’t “know” how tenth graders think but it’s seen a lot of text that it “knows” were written for tenth graders. It can imitate that. But how does it translate that into artistic development?
Here’s what I got when I asked DALL-E 2 to show me clay copies of The Thinker created by “an artistic eighth grader”:
These are, on the whole, worse. We want to see sculptures that more accurately capture the artistically salient features of the original. Instead, we get more hair and more paint.
How could you get the model to capture artistic development? Again, I’ll speculate as a layperson. The root of the problem may well be in the training data. The internet has many, many images. But it doesn’t have a large and well-labeled set of images showing the same source image (like the Rodin sculpture) being copied by students at different age levels using different media (e.g., clay, watercolors, etc.). If so, then we’ve hit the wall. Generating that set of training data may very well be out of reach for the software developers.
Language is weird
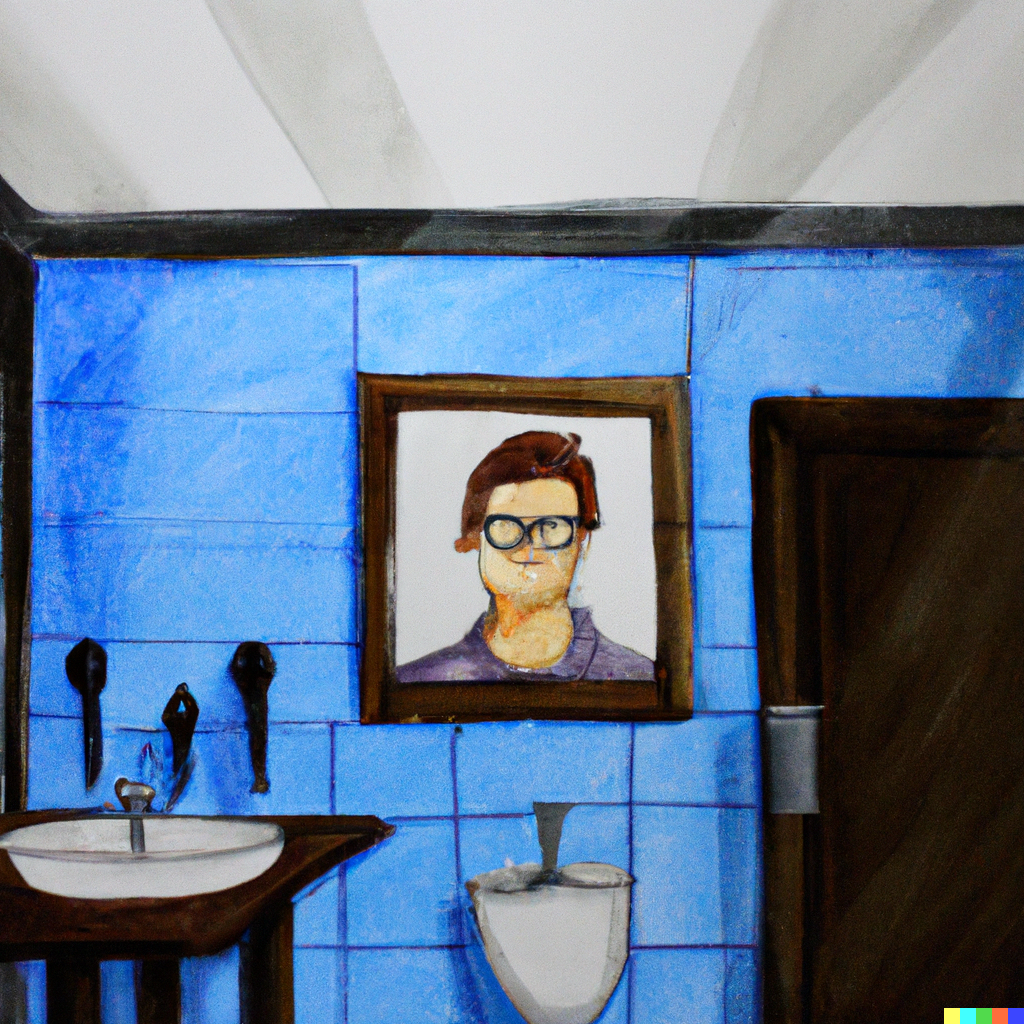
I’ll throw one more example in just for fun. By this point in my experiment, I had gotten bored with The Thinker and was just messing around. I asked the AI to show me “a watercolor painting of Harry Potter in a public restroom.” Now, there are two ways of parsing this sentence. I could have been asking for “(a watercolor painting of Harry Potter) in a public restroom” or “a watercolor painting of (Harry Potter in a public restroom)”. DALL-E 2 couldn’t decide which one I was asking for, so it gave me both in one image:
A watercolor painting of Harry Potter in a public restroom as interpreted by DALL-E 2
These models are tricky to work with because it’s very easy for us to wander into territory where we’re recruiting multiple complex aspects of human cognition such as visual processing, language processing, and domain knowledge. It’s hard to anticipate the edge cases. That’s why most practical AI tools today do not use free-form prompts. Instead, they limit the user’s choices through the user interface to ensure that the request is one that the AI has a reasonable chance of responding to in a useful way. And even then, it’s tricky stuff.
I’ve always written about whatever interested me at the time. It could have been driven by the work I was doing, a hot product category, or something that bothered me. That won’t change. But what interests me now is that significant changes finally seem afoot for education.
I’ve always been fascinated by the evolutionary biology concept of punctuated equilibrium. An ecosystem can seem remarkably stable and resilient for a very long time. But when just the right pressures come along, it can shift suddenly and dramatically until it finds a new equilibrium. For example, when Europeans came on ships to Australia, New Zealand, and the surrounding islands, the ships brought rats with them. Those rats killed off entire species of flightless and ground-nesting birds. Those birds interacted with other species. For example, they may have helped spread seeds of trees and bushes, as birds often do. So an environmental system that was stable for thousands of years suddenly underwent a rapid and cascading series of changes until it reached a new point of stability that could accommodate the invasive species.
Systems thinking provides a complementary way of approaching the same phenomenon. Using this lens, we see the world in terms of negative and positive feedback loops. A negative feedback loop compensates to stabilize change. For example, if the temperature drops in the house too much, then the thermostat turns on the heat. Once the temperature is back to the setting on the thermostat, the heat turns off. Positive feedback loops are the opposite. They reinforce. For example, when you cut yourself, the injured tissue at the cut issues a chemical call to attract platelets. The platelets arrive and issue chemical calls for more platelets. As this process builds, your blood clots. These positive feedback loops can sometimes run amok. For example, when the rats ate the easy prey of the ground-nesting birds in the previous example, more rats survived to produce more litters of rats, which ate more birds. This sped up the change that was underway.
I think we’ve reached a tipping point in US higher education and elsewhere. We’re entering a period of rapid and unpredictable change. As a result, some topics that didn’t interest me before because I didn’t think they would lead to change are now more interesting to me. Topics outside my “beat” as an analyst are now interesting because old boundaries are becoming weaker and more porous. In the remainder of this post, I will offer a preliminary list of topics I’ll be paying more attention to. I have no grand theory of change at this point. I’m not a Futurist. But I am looking to write more about some forces that drive change and early indicators of where change might be happening.
A copy of the sculpture “The Thinker” made by a third grader using clay as interpreted by DALL-E 2
Enrollment shift
For decades, predictions that an enrollment cliff was coming in US higher education failed to pan out. This time feels different. Yes, the demographic shift is looming, although it’s not fully here yet. Other factors seem more urgent. Traditional students and their parents have been increasingly priced out of college or just questioning the price-to-value of it. The shift to remote learning over the pandemic followed by the red-hot job market have driven more students to defer college in favor of a job. Traditionally, that has meant they are a lot less likely to come back. As the economy moves toward a likely recession, we don’t know whether the usual counter-cyclical effect of more students enrolling in college will hold this time. If it doesn’t, there will be trouble for the institutions on the bottom half of the financial health spectrum.
Other changes are in play too. First, the growth slow-down of OPMs is one indicator that traditional means of growing enrollment may be increasing played out for colleges and universities. Meanwhile, the growing numbers of people in the workforce without college degrees means more people who will eventually want to go back to school for the skills they need to advance their careers. Likewise the acceleration in job market changes and job skills requirements means that the long-awaited move toward lifelong learning seems to finally be picking up steam. But these are different students with different needs than the ones higher education traditionally serves.
And even “traditional” 18- to 21-year-old students are likely to look more and more like post-traditionals. More are already looking for career-focused educations. More are expressing openness to or even preference for hybrid, blended, and online learning. More are working while going to school.
To sum up, if we’re looking for a place where positive feedback loops are likely to cause sudden and dramatic change, enrollment shift is a good candidate. Since I’m not steeped in these details or expert at the quantitative analysis that’s necessary to track enrollment shift, I will likely be responding to writing by experts, teasing out implications, and looking for knock-on effects in areas that I am better equipped to analyze. For example, while I’ve been a skeptic of the long-predicted “Great Unbundling” up until now, I think the current conditions are more fertile for microcredentials, competency-based education (CBE), and alternative credential providers to take root.
AI/ML
Up until now, I’ve viewed artificial intelligence and machine learning (AI/ML) in EdTech as part scam, part niche, and part interesting but esoteric research. (I’m referring specifically to the application of these technologies to help with education; the increasing demand for people with these job skills is beyond question.) Three factors have me looking at this topic afresh. First, the undeniably rapid advance in these techniques, coupled with their increasing availability, has led to applications starting to show up on the market that have solid evidence of impact. And EdTech is behind the curve in figuring out how to apply these techniques even as the possibilities increase rapidly. Second, these technologies are going to be increasingly important in serving the new student population in the enrollment shift, who are likely to be harder to reach, harder to retain, and need more and more varied support. Last but not least, I anticipate the possibility of major changes in the fundamental ways that colleges and the people who work at them perform their jobs. Many workflows may need to be fundamentally redesigned. AI/ML can be very useful in making those shifts more efficient, effective, and economical. While I risk reinforcing a mindless cliché by writing this, AI/ML can be a highly disruptive force under the right circumstances. While it could drive major change all by itself, the odds that it will be decisive rise significantly when combined with the other themes I’m outlining in this blog post.
My sense is that the current approaches to applying AI/ML to education often lack imagination and are focused on solving the wrong problems. That said, I haven’t been paying as close attention in the past as I will be going forward.
Workplace and lifelong learning
The connection between workplace learning and higher education has already started moving from being sporadic and opportunistic toward becoming strategic and programmatic. A company like Guild Education couldn’t have existed at anything like its current scale five or ten years ago. If the enrollment shift continues to grow as I think is likely, then this connection is likely to get stronger. How quickly this shifts will depend on a multitude of factors. But to the degree that it shifts quickly, it will both reinforce and be reinforced by other positive feedback loops that drive rapid change.
Separately, I wrote a couple of trial balloon posts that drew on my knowledge as a corporate consultant in the late 1990s and early 2000s to see if I still have anything of value to contribute to that space. The reactions I received suggested to me that I do. In fact, much of the knowledge I’ve gained working in EdTech for higher education transfers rather well. So, while I anticipate that e-Literate will remain anchored in higher education, I will be looking more at workplace and lifelong learning as well, especially where the topics intersect with higher education.
Growth of international markets
Frankly, I’m not quite sure what to do with this one. EdTech has been anticipating the growth of global markets for a long time. I remember Oracle trying to push into Asia into the late 2000s while I was working there. The transition has been slow but digitally-enabled education is finally arriving at meaningful scale in an increasing number of geographies. And this change, in turn, is already impacting EdTech investment as well as the thinking of US universities that can afford to recruit students from overseas. (Especially the ones that have already been doing so for some time.) This could be another force that precipitates rapid change.
This is a difficult theme for a single US-based analyst to cover adequately. So, while I’m keeping an eye on it, I can’t cover it with any depth or regularity unless something significant shifts for me.
Third-Wave EdTech
All of the above leads me to the conclusion that we may be in the early stages of a coming wave of what I think of as the third wave of EdTech. The first wave focused on making existing university processes more efficient and scalable. The major product categories that came out of that wave were the LMS, the SIS, and the digital homework platform. Second-wave was about expanding traditional enrollments and trying to reach new ones through direct-to-consumer approaches. MOOCs and OPMs were the major new product categories in this area, followed by bootcamps and similar supplemental credential companies.
Neither of these waves is going to disappear. First-wave products have generally become staid infrastructure with heavy private equity ownership, although ironically the SIS is seeing some new life as incumbents and new competition vie to handle shorter terms, CBE, and novel credential types to meet the needs of the changing enrollments. Second-wave is in the process of transitioning to a status closer to where first-wave is. Valuations and growth rates of these companies are both coming down. Consolidation, leadership changes, and increasing private equity involvement are likely in the cards.
Third-wave EdTech will respond to the trends I’ve outlined above, particularly in areas where the companies from the earlier waves either have trouble adapting or have nothing to offer. Guild is one of the early third-wave giants. That said, Guild isn’t a teaching and learning company. That’s not a knock on them; it’s just a factual statement about where they currently add value. I haven’t yet seen any Guild-sized third-wave EdTech companies focused on teaching and learning (with the possible exception of K12, which is different enough and complex enough that I won’t be covering it with any regularity). But one lesson I’ve learned over the past couple of years is that venture capital tends to lag behind the trends. If we are indeed entering a period of rapid change, then some of the money that has been flocking to India and to second-wave workplace learning companies will shift.
Third-wave EdTech, if it comes as I think it might, is the trend that I have the most expertise to cover on this list. But since it’s a downstream effect of the other factors, and since I only care about EdTech to the degree that it actually improves access to and quality of education, it will be important for me to widen the view on e-Literate more going forward.
I will stick with the topic of artificial intelligence and machine learning (AI/ML) for today’s post because I keep getting feedback suggesting there’s a lot of interest in it. Since I’m on a bit of a streak, I feel compelled to make some caveats before jumping in.
First, I am not a software engineer or an AI/ML expert. In fact, I’m not an expert in many of the topics I write about. I just happen to be pretty good at making inferences from a small amount of information and understanding. I write about what I’m learning rather than what I know. For many years, the tagline for this blog was “What I’m learning about online learning.” ((“What I’m learning about stuff that interests me and is in some way relevant to digitally-enabled learning” seemed too long.)) Since this blog is about learning rather than knowing, the corollary is that I invite you to educate me if you know something I don’t. Please tell me if I’m wrong, if I’m missing something, or even if you think I’m right.
Second, I’ll be writing again about the big new AI language models that have been taking the world by storm lately. On the one hand, I risk adding to misperceptions with this focus. A lot of folks are writing about these models now because they’re so sexy, surprising and, frankly, potentially dangerous. In reality, AI/ML is a large, diverse, and ever-growing family of computational techniques, many of which have very different characteristics from each other. On the other hand, the big models are useful to write about precisely because they are on the extreme end of the spectrum regarding their alienness. They highlight some problems that may be more subtle and harder to see in other techniques.
My last caveat is that I will be responding to an interview conducted by the great Ben Thompson of Stratechery. Specifically, I’ll be quoting from one of his subscription-only articles. Since this is his bread and butter, I’m mindful of putting too much of his paid content on the public internet. Luckily, it’s a very long article and I’ll only be quoting a small fraction of it. While I think it likely meets the criteria of fair use, more importantly, I’m hoping Ben will see it as an advertisement. I’m a fan. I don’t pay for many newsletters. I do pay for his. If you want to understand the intersection of tech and business, you should too. He’s a fantastic writer and an original thinker.
This post happens to be an interview, which is unusual for Stratechery. The interviewees are Daniel Gross and Nat Friedman. Ben identifies them first as VCs, but their salient credentials are that they both worked extensively in tech and are real experts in AI/ML. His post is fascinating in its entirety. I’m going to focus on a few aspects that are salient for EdTech and that resonate with my recent screeds on AI/ML.
Spooky and kooky
In my post about using GPT-3 to create a philosophy tutor chatbot, I wrote about the miracle, the grind, and the wall. First, these models do something that blows your mind. That gets you excited. As you try to turn that moment of exhilaration into a reliable and scalable piece of software, you discover that reliable and scalable are both arduous work. Eventually, you hit a wall you can’t get past. And it’s hard to predict in advance where that wall will be.
Nat Friedman oversaw the creation of GitHub Copilot, which uses a version of GPT-3 to suggest code to developers in real-time as they are writing software. Here’s what he said about what it was like:
he thing I would always say with those models is that they alternate between spooky and kooky. So half the time or some fraction of the time, they’re so good, it’s spooky like, “How did it figure that out? It’s incredible. It’s reading my mind,” or “It knows this code better than I do.” Then sometimes it’s kooky, it’s just so wrong, it’s nonsense, it’s ridiculous. So when it was wrong, it was really wrong. It turned out from testing it in the Q&A scenario that when you actually asked the thing a question and it gave you more often than not a wrong answer, you got very irritated by it — this was an extremely bad interaction. So we knew that it couldn’t be some explicit Q&A interaction. It couldn’t be something where you ask a question and then 70 percent of the time you get a useless answer. It had to be some product where it was serving you suggestions when it has high confidence, but it wasn’t something you were asking for and then getting disappointed by….
[I]t turns out in retrospect, we know this now and we didn’t know it at the time, the question that we were trying to answer was, “How do you take a model which is actually pretty frequently wrong and still make that useful”? So you need to develop a UI which allows the user to get a sense and intuition themselves for when to pay attention to the suggestions and when not to, and to be able to automatically notice, “Oh, this is probably good. I’m writing boilerplate code,” or “I don’t know this API very well. It probably knows it better than I do,” and to just ignore it the rest of the time.
Friedman’s comments highlight that even Microsoft, using one of the most advanced AI models on the planet, could only get a useful answer from the AI about 30% of the time after carefully training it on the vast body of software code in GitHub that had been tested and validated as working.
There isn’t even a moment’s consideration given to having the model replace the programmer. It’s wrong 70% of the time. That might not be true always and forever but it’s true now with an army of skilled engineers using one of the best models available. The product is called Copilot. Not only is there a human in the loop; the human is in charge. A lot of thought went into designing the software so that expert humans will feel comfortable ignoring it and not annoyed that it’s wrong so often:
So it’s funny because a lot of the ideas we had about AI previously were this idea of dialogue. The AI is this agent on the other side of the table, you’re thinking about the task you want to do, you’re formulating it into a question, you’re asking, and you’re getting a response, you’re in dialogue with it. The Copilot idea is the opposite. There’s a little robot sitting on your shoulder, you’re on the same side of the table, you’re looking at the same thing, and when it can it’s trying to help out automatically. That turned out to be the right user interface….
So from the June realization that we should do something, I think it was end of summer, maybe early-September by the time we concluded chatbots weren’t it. Then it really wasn’t until February of the next year that we had the head exploding moment when we realized this is a product, this is exactly how it should work…. So now, it’s very obvious. It seems like the most obvious product and a way to build, but at the time, lots of smart people were wandering in the dark looking for the answer.
This is not the way a lot of EdTech is designed. The industry tends to develop models that automate various aspects of course design, teaching, or support and shoot it straight to the students without much thought about how those students will handle or even recognize, errors. Even when there’s a human in the loop, we’re not typically designing these products for expert humans. Instead, we’re using the humans to review—which might mean spot check—the machine-generated output or tool, which is intended for use by explicitly non-expert humans.
“A Robot Tutor in the Sky,” by the DALL-E 2 algorithm
The best systems using tech that is extremely useful but highly unreliable are designed to make the role of human judgment obvious to see and easy to apply. As Friedman notes, getting this right is very hard.
Getting the interaction model right
Thompson’s response to Friedman was characteristically insightful:
The reason is that people want to anthropomorphize everything and they want to put everything in human terms. The whole point of a computer is it just operates utterly and completely different than humans do. At the end of the day, it’s still calculating ones and zeros. So everything has to be distilled to that and it just does it at tremendously fast speed, unimaginable speed, but that is so completely different than the way that a human mind works that that’s how whatever was kooky or spooky I’m sure was completely and utterly logical to the computer. It strikes me that this is why the chat interface was wrong, because what it was doing was it was taking this intelligence, and it was actually accentuating the extent to which it was different than humans by trying to put it as a human, as if you’re talking to someone, and it was actually essential to come up with a completely different interface that acknowledged and celebrated the fact that this intelligence actually functions completely and utterly differently than humans do.
The three lessons here are (1) make the AI visible, (2) make it clear that the AI is not some simulacrum of human intelligence but rather is a tool that works imperfectly, and (3) create an experience that encourages users to exercise judgment when evaluating the output of the AI.
Here’s Friedman again about Copilot:
The thing that Copilot gave us that we, again, only realized in retrospect was this randomized psychological reward. It’s like a slot machine where the ongoing cost of using it at any given moment is not very high, but then periodically you hit this jackpot where it generates a whole function for you and you’re utterly delighted. You can’t believe it, it just saved you 25 minutes of Googling and Stack Overflow and testing. That happens at random intervals, so you’re ready for the next randomized reward, it has this addictive quality as a result. Whereas people frequently have ideas that are like, “Oh, the agent is going to write a huge pull request for you and it’s going to write a huge set of changes across your code, you’re going to review that.”
Copilot turns a bug into a feature. The unreliability leaves you delighted when the product gives you something useful rather than angry when it doesn’t. This only works because the user explicitly understands that the product is 70% unreliable but finds it helpful—and delightful—anyway.
Again, that’s not how EdTech typically is designed and it’s certainly not how it’s usually sold. We often present the tech to non-expert users as a virtual helper that’s positioned as a tutor or advisor.
It doesn’t have to be that way. First, we should spend more energy in EdTech using AI/ML to help expert users—i.e., the educators—more efficiently and effectively leverage their expertise to help the non-expert users—i.e., the students. Second, we can create interfaces for non-expert users that turn the unreliability of AI models from a bug into a feature. One portion of the interview turns to new models that enable users to generate novel images from text. Friedman talks about people using one such model, called Midjourney, that they access through a discussion forum called Discord:
if you ever watch a really creative person sit over their shoulder and watch them use Midjourney for an hour, you find that what they’re doing is not one text-to-image. They’re writing a prompt, they’re generating a bunch of images, they’re generating variance of those images, they’re remixing ideas, they might be riffing off someone else in the Discord channel, they’re exploring a space, you’re exploring latent space in a way, and then pinning the elements of it that you like, and you’re using that for creativity and ideas, but also to zero in on an artifact or an output that you’re trying to produce, and those are different modes.
This was similar to my experience trying to write a philosophy tutor. It was creative and fun. It felt a bit like teaching a student with strengths and limitations that I was trying to understand. I would probe, adjust, and probe again. I loved it. And when I had reached my limit with the chatbot, yes, I was tempted to throw it out and start fresh with another idea.
Friedman, noting the popularity of Midjourney on Discord, described an example user he heard about from the company’s founder:
There was one David was telling me about recently who’s a trucker, who when he stops at truck stops, he canceled his Netflix, and now what he does is he just makes images for a couple hours before bed, and he’s utterly transfixed by this. To me, that seems like it’s just objectively better than watching Netflix and binging a show; it’s exploring the space of your own ideas and creativity and seeing them fed back to you. So it turns out there’s a lot of people who have this creative impulse and just didn’t have the tools, the manual skills to express it and to create art, and something like Midjourney or something like Stable Diffusion gives them that, and that’s incredibly exciting.
In education, we discuss the need to expose our students to AI/ML and develop some literacy. This is equally true in the workforce, by the way. And yet, when we do expose students to the tech, make it as we tend to make it invisible as possible.
The bottom line
Some readers have interpreted me as an AI/ML skeptic, at least as applied to EdTech. The opposite is true. I’m enthusiastic about its potential and some of the current uses I’ve seen. I simply believe that we are immature in our thinking about how to apply it constructively to our domain. While we’re hardly alone in that, we have an extra responsibility of care as educators. We should be looking for new models that previously weren’t possible rather than just trying to automate and accelerate old models. In doing so, we should embrace the limitations of the technology and let them inspire fresh thinking.
My recent post on the challenges of using artificial intelligence and machine learning (AI/ML) in EdTech received various responses. Both some positive and some negative responses gave me the sense that focusing on the one rather extreme example of an open-ended chatbot suggested to some readers that I was arguing that all AI/ML is equally fraught, whether they agreed or disagreed with that proposition. As an antidote, I thought it might be helpful to provide snapshot analyses of different applications of AI/ML I’ve seen in EdTech. While it’s far from comprehensive, I hope it will illustrate some patterns:
In general, AI/ML can be beneficial for supporting professional educators’ work (including learning designers, learning engineers, etc.) and directly impacting learner success.
AI and ML are not magic. They have limitations that are both technology- and problem-domain-specific. Relatedly, AI/ML is not a monolith. That bucket consists of a large array of different techniques with different limitations and which, to make matters more complicated, are increasingly used in concert with each other.
EdTech seems to go light on a strategy called “human-in-the-loop,” which means that expert humans review the algorithm’s output on a routine basis as a safety and quality check. This is bad.
I’m most familiar with work developing “courseware,” i.e., self-paced didactic or training materials, although I have a smattering of exposure to other areas. I’ll focus on courseware first and then provide some other examples.
It’s never quite what we imagined…
Courseware
For the last decade, the emphasis in courseware has been on “adaptive learning” or “personalized learning,” where the algorithm adjusts to each student’s learning needs. More recently, efforts have broadened into using AI/ML to reduce time and lower the costs of producing new courseware. I’ll cover both areas and describe briefly how they overlap.
Adaptive Learning
The two most widely adopted and evidence-backed methods of algorithmic adaptive learning are memory-focused and skill-focused. Memory-focused is the more straightforward of the two. The easiest way to think about this family of techniques is as smart flashcards, even though the user experience doesn’t always present this way. We know a lot about how memory works that lends itself well to algorithms. For example, we know the most effective amount of time to wait before quizzing students again on a given fact to be memorized. This is called “spaced practice.” We know something about the best way to mix various topics for memorization, which is called “interleaving.” Writing an algorithm that uses this information to quiz students and then adjusts its strategy based on how well the students perform is a relatively straightforward, effective, and safe application of the technology. It’s mainly been applied to memorization, although it can be used to help learners check to see if they remember new skills they learned.
Skill-focused adaptive learning is more complicated. First, you have to be able to break down the skills into a tree, which has traditionally been an arduous process that can be harder than it sounds. For example, it turns out that when students learn to calculate the slope of a line, they first learn how to work with upward-sloping lines and downward-sloping lines separately. Then they learn to integrate these skills. To make matters worse, this process is generally unconscious to the student and invisible to the instructor. Skill acquisition, even in highly procedural subjects like math, is tricky because we can’t directly observe learning and because humans have sophisticated and often unconscious learning processes that evolved rather than being designed. They are continually surprising. That said, the line-slope-learning quirk was discovered by humans using a machine learning algorithm to identify patterns in the ways that many students progressed through many formative assessment questions.
In higher education, skill-based adaptive learning has shown the most benefit in STEM subjects, where the knowledge is often more overtly procedural. Implementation is often a problem. Neither learner nor educator always knows why the algorithm routes the students a particular way. And students can get stuck in a loop that the educators are powerless to free them from. The problem arises because many of these systems were not designed as educator-in-the-loop. On the contrary, they were intended to either reduce the number of educators required or “teacher-proof” courses against educators whose skills are not trusted. But like any other black box, when something breaks inside, you can’t fix it. In fact, it can be hard to anticipate where problems are likely to arise because you don’t always know what the box is doing.
I mentioned that mapping out skills for adaptive learning or other purposes has been a complex and labor-intensive process. That is starting to change. Emerging AI/ML models appear to be highly effective at mapping skills represented in content and then improved through input from experts and analysis of student data over time. This combination of methods, which utilizes multiple AI/ML strategies, shows promise to develop courseware more quickly, at higher quality, using less labor, and improving over time with human-in-the-loop supervision.
Having human experts involved is critical even in cases where adaptive learning is not employed. Adaptive learning is analytics plus automation. First, the system analyzes the student’s level of mastery. Then it automates the response. These days, most systems that lack automation, i.e., algorithmic adaptive learning, still have analytics. And mastery analytics are keyed to the skills in the skill map. If the algorithm misidentifies skills then the analytics, the progress indicators, will be wrong.
Increasing production efficiency
The skill mapping example demonstrates both quality improvements and production efficiencies. The trick is not to lose track of quality improvement while chasing production efficiency. Because you can easily make quality worse rather than better if you’re not careful.
Publishers are increasingly turning to AI/ML to generate assessment questions. For typical question types like multiple choice or fill-in-the-blank, the accuracy of these algorithms seems to hit a hard ceiling of 80%-85% accuracy. Some companies are deploying these questions directly to students without humans in the loop, arguing that their accuracy rate is the same as that of human-written textbooks. I’m personally uncomfortable with that. Adding a button for students to report questions they think are wrong is a kind of human-in-the-loop strategy, but it’s after the fact. The damage has been done. How much damage depends on various factors, like whether the assessment is formative or summative and whether the student has the self-confidence to question the computer program. We have to get more creative about developing new methods for including humans in the loop at scale.
Even common assessment types like the humble multiple choice question have tricky bits. Distractors—wrong answers—are essential for diagnosing why a learner may be stuck on a problem. Research tells us that hints (combined with the right machine learning algorithm) can also tell us a lot about how well a learner is progressing if they are written properly. I’m aware of efforts to generate distractors and hints algorithmically, but I don’t know how accurate they are.
Opportunities become more interesting—and squirrely—when we move beyond the usual machine-graded question types to more novel ones. For example, in a webinar by Walden University and Google Cloud about a new Google-powered tutor Walden is piloting, the presenters describe an interesting paraphrasing question type in which the system uses multiple AI/ML methods to check whether a student’s rephrasing of a concept in the course materials is both original enough that it shouldn’t be considered copying and close enough in meaning that the student is correctly paraphrasing.
To the degree that it works, it’s a wonderful addition to the toolbox. That said, I’d like to see efficacy studies, both for a general population of students and disagregated subpopulations of weak writers and second language learners. Like many of these innovations, it could make learning worse rather than better for some or all students. We shouldn’t feel confident we know until we’ve conducted rigorous research.
To be clear, I don’t know the existing literature on this particular AI/ML application and I also don’t know what research Walden and Google have conducted or are conducting. That question wasn’t asked in the recorded Q&A. More generally, this is another danger with AI/ML. Because the tech is so dazzling and there’s so much talk about data, it’s easy to assume that we know how well the innovation works with learners. But we can’t be sure until we’ve conducted multiple well-designed experiments at scale. For the same reason that AI/ML can speed up drug discovery but drug approval is still slow, we can’t responsibly implement new AI/ML EdTech as fast as it is developed.
Anyway, these are the mainstream applications that I’m aware of for courseware. More cutting-edge applications exist in niches where there is money to spend on VR, movement tracking, and other tech that is too expensive to be mainstream at the moment. I won’t cover these in this post other than to acknowledge that they exist.
A couple of other examples
Of course, courseware is far from the only application of AI/ML in EdTech. Chatbots are used quite a bit, though they are usually designed using AI/ML technologies that are quite different from the one I described in my previous post. For example, many use an algorithm closer to (or identical to) the one in Amazon’s Alexa. It’s not trying to have a conversation with you. It’s just trying to interpret what you’re asking for. As described to me by the co-founder of Mainstay (formerly known as AdmitHub), a student who needs financial aid may express that need to the chatbot as “I need money.”
On the back end, the answer returned by a chatbot may be as simple as an automated FAQ or use some other AI/ML techniques to provide a more tailored and conversational experience. I’m not sure what Mainstay does at this point—the product evolves, as products do—but the company has conducted multiple randomized controlled trials (in collaboration with university customers like Georgia State) demonstrating that they can help students navigate the college enrollment process.
Then there’s conversational analysis. One example I like, partly because it integrates into real-time videoconferencing and partly because I know and trust the founder, is Riff Analytics. Riff plugs into video conferencing software and provides real-time and after-the-fact metrics like who is talking the most, who is interrupting, whose comments are getting the most affirmation, and so on. If you think about that last metric—who is getting the most affirmation—you can easily see that multiple AI/ML techniques must be in play. First, the speech has to be converted to text. Then it must be analyzed for sentiment. (When I say “must,” that means I’m making an educated guess.)
From here, it would be easy to go down the rabbit hole and talk about, for example, how my friends at Discourse Analytics are improving nudges. AI/ML techniques in EdTech are far more pervasive, varied, and rapidly developing than is visible on the surface.
And that’s fine. These are tools. They are not automatically good or bad. The trick is in how you use them. Here’s my advice:
Carrying over a point from my previous blog post, don’t assume your intuitions about your AI/ML application that you gleaned from early results will prove accurate once you try to scale. This tech can be deceiving.
Think hard about innovative ways to include humans in the loop. These new technologies bring with them the requirement and the opportunity to radically rethink how we work together, including how we work on learning design together.
Don’t assume that data from your product’s analytics satisfies the high standard of proof we should require before putting new technologies in front of learners. Follow the research and, when necessary or possible, conduct your own. Once again, this is an opportunity for us to innovate in how we work together.
I had a conversation with a friend last night about the counter-intuitive challenges of working with AI/ML and the implications for using them in EdTech. I decided it might be useful to share my thinking more broadly in a blog post.
Essentially, I see three stages in working with artificial intelligence and machine learning (AI/ML). I call them the miracle, the grind, and the wall. These stages can have implications for both how we can get seduced by these technologies and how we can get bitten by them. The ethical implications are important.
The Miracle
One challenge with AI/ML is how deceptively easy it is to produce mind-blowing demos with these tools. For example, I spent some time playing with GPT-3 as a learning exercise. GPT-3 is one of several gigantic AI models that can do some pretty miraculous things with natural language. (Google has the other prominent gigantic model.) One reason I started with GPT-3 is that it can be programmed using natural language. For example, you can tell it, “You are a helpful chatbot that teaches first-year college students about philosophy” and voila! You have a helpful philosophy-teaching chatbot.
It’s not quite that simple. For example, I found that GPT-3’s idea of what a first-year college student understands about philosophy differed from mine. I got better results when I asked it to target 11th grade. I couldn’t have known that in advance. GPT-3 is a neural network of 175 billion parameters. It has indexed large swathes of the internet and many books. But it doesn’t store all that information, exactly. It distills it in very complex ways. In fact, GPT-3 and similar models are so complex that even the programmers who made them can’t explain why they produce specific responses to instructions or questions. So I had to figure out how to “program” my chatbot through a bit of trial and error.
Not all AI/ML algorithms are this complex. Some of them are much easier to understand. It’s a spectrum, and GPT-3 is on the far end of that spectrum.
Anyway, after a few days of intermittent tinkering, I was able to produce a chatbot that could carry out a sustained and informative conversation about David Hume’s theory of epistemology, to the point where it gave me new insights into the subject. I accomplished this by tinkering over a few days, as a layperson, using plain English.
I had reached the miracle stage of AI/ML.
But there were problems. First of all, the chatbot would end the conversation just when it got really interesting. It suddenly would insist on saying goodbye and could not be persuaded to continue talking. It turns out that this kind of AI model has a strict memory limitation. When you hit it, the chatbot suddenly forgets your entire conversation. My new philosophy tutor friend also sometimes gave weird answers. I knew when to ignore them but they would have confused some students.
GPT-3 has a community of developers who are incredibly helpful, particularly when the topic is something idealistic like education. I was able to find a very knowledgeable programmer who was generous with his time and helped me understand what I would need to do in order to take my tutor to the next level.
The grind
The first thing I’d need to do is learn to program in Python since I had reached the limits of programming in plain English. And for the 9,781st time, I was momentarily tempted to learn a little programming. But then he explained what I’d need to do.
For the memory problem, I’d need to chain portions of the conversation together. But since GPT-3 doesn’t actually remember large chunks of information so much as it distills them, the chatbot wouldn’t literally be able to recall our entire conversation. You can quickly see where this could become problematic. If the student says something like, “When you said earlier that…”, it’s hard to predict how the chatbot would respond.
And so we enter the grind phase. It could also be called the whack-a-mole phase, since you’re finding a problem, writing a solution, and then looking for unintended consequences elsewhere. Also, since the model isn’t knowably deterministic and the questions students will ask also aren’t knowably deterministic, it’s probably impossible to test all the possible scenarios.
Which is why you don’t see chatbots that are this open-ended and ambitious. Translating that initial miracle into a reliable response is a daunting if not impossible task. Today’s chatbot designers use UX and context tricks to make the inputs from the students more predictable and they also use less complex algorithms with outputs that they can predict and debug more easily. They tend to reserve the usage of models like GPT-3 for limited and specific applications. And even when they’re careful, producing a chatbot that is rock-solid reliable takes a lot of hard work, including difficult debugging that’s often quite different from debugging traditional software.
This brings us to the final phase: The wall.
The wall
Sooner or later you reach the limit of what your tech can do for you. Predicting that limit in advance takes tremendous skill, often requiring extensive domain knowledge of both the tech itself and the problem it’s being applied to, whether that’s detecting manufacturing defects, discovering new drugs, or tutoring students. There are always nooks and crannies of knowledge and skill that are a poor match for the technology’s capabilities or the data it can access.
Think about spelling and grammar checkers. They’ve been around since 1961, believe it or not. Even as recently as five or six years ago, Microsoft Word’s spell checker was so bad that I always turned it off. Today, I use Grammarly Pro, which checks spelling, and grammar, and now even makes suggestions on effective sentence structures. I love it. It makes me a better writer.
But it still makes mistakes in spelling. It makes more mistakes in grammar. And it’s writing style suggestions, while pretty good, make the sentence worse or even change it’s meaning fairly often. The reasons for these limitations are often not obvious to the layperson. For example, Wikipedia notes this eye-opening fact about spell checkers:
It might seem logical that where spell-checking dictionaries are concerned, “the bigger, the better,” so that correct words are not marked as incorrect. In practice, however, an optimal size for English appears to be around 90,000 entries. If there are more than this, incorrectly spelled words may be skipped because they are mistaken for others. For example, a linguist might determine on the basis of corpus linguistics that the word baht is more frequently a misspelling of bath or bat than a reference to the Thai currency. Hence, it would typically be more useful if a few people who write about Thai currency were slightly inconvenienced than if the spelling errors of the many more people who discuss baths were overlooked.
The tech has a non-obvious fundamental limitation. And in this case, not only is more data not better; more data is worse. So the idea that all AI/ML problems can be fixed with big data is flat-out false. Sometimes better data is better.
Grammar is significantly more complex than spelling and writing for clarity is significantly more complex than grammar. Each of these functions will likely hit a wall. It might not be a permanent wall, since technology improves over time. But it might be, since sometimes the limitation isn’t the tech but the nature of the problem or the data available in a form that is accessible to the tech.
Ethical implications
The rush I felt when I learned something about philosophy from the chatbot I wrote myself is indescribable. I was a philosophy major with a particular interest in anything related to the mind or knowledge. While I don’t have an advanced degree, I certainly knew something about David Hume’s epistemology when I started the dialogue. I was certain I was seeing the future.
And maybe I was. But it isn’t the near future. When I think about the much more mature technology of the grammar checker, I wouldn’t trust it with weak writers, and certainly not with ESL students. The checker would be more prone to make mistakes and the students would be less likely, on average, to have the confidence and knowledge necessary to know when to ignore the machine. In order for me to change my mind, I’d want to see some quality IRB-approved, peer-reviewed studies showing that grammar checkers help these students rather than harm them.
We’re in a heady moment with AI/ML. I see a lot of projects rushing headlong into heavy use of the tech, often putting it into production with students without the kind of careful oversight necessary to fulfill the EdTech Hippocratic oath: First, do no harm.
EdSurge’s Daniel Mollencamp has published a piece called “What a Homework Help Site’s Move to Host Open Educational Resources Could Mean” about Lumen Learning’s deal with Course Hero to transfer hosting of those OER textbooks from Lumen’s site to Course Hero’s. The article contains a fair bit of speculation quotes from folks who I believe miss the mark on some basic facts and implications. I confess that I will engage in some informed speculation here in the sense that I have not engaged with on-the-ground reporting to confirm what I believe I know. Nevertheless, I believe I know some facts that contradict some of the speculation in the piece and put the transaction in a somewhat different light.
For most of this piece, I’m going to stick with what I believe to be the facts. I will take a little time in the last section to provide my own point of view. That said, there are strong feelings in pockets of the educational community about both of these companies. I will be treading lightly. If you want to read vehement critiques of these companies, their business models, and their values, you can find them elsewhere on the web.
The basic facts as I understand them
Here’s what I believe to be true:
Lumen has had two branded lines of OER-based products:
Waymaker is their flagship product line. They invest in editorial work and research to improve the content and software development to improve the underlying platform on which it is hosted.
Candela are OER products that were contributed by the community but not actively maintained and improved by Lumen. They were hosted on a less capable platform. And, to my knowledge, they were free.
Lumen transferred Candela products, but not Waymaker products, to Course Hero.
Lumen received quite a bit of traffic to those free OER content. I seem to recall Kim telling me the number was in the millions of visits. That’s great for education but is also an expense for a small company. While I know some will dismiss the cost of hosting web pages on the internet, the cost of hosting content with that much traffic and keeping it accessible can add up over time.
The business value of Candela courses to Lumen was far from clear. It’s not like students using the content for free were likely to become paying customers or convert their faculty to adopting Waymaker products. Again, hosting the content is a good thing to do. But every company has a limit of how much they can afford to invest in public-good work. I don’t know how much Candela costs to host and maintain relative to Lumen’s total revenues. I speculate that it was non-trivial.
On the other hand, Course Hero’s primary clientele is students. Every user of Candela is a potential subscriber to Course Hero’s paid services. And Course Hero is a vastly bigger company. So the relative cost of hosting the content was smaller to them than to Lumen and the potential business benefit was larger.
As I alluded to in my introduction, both companies have vocal detractors.
In Lumen’s case, their primary critics tend to be within a subsection of the OER community and relate to which business models in relation to OER are considered “legitimate” or support the values of the OER community.
In the case of Course Hero, the controversy is more widespread. They are criticized as being a “cheat site.” Some universities are blocking access to Course Hero from school networks and I hear periodic rumors of plans for legal action against the company, although I am not aware of any actual litigation.
[Update] I have heard multiple complaints that Candela students were redirected from Lumen’s site to Course Hero’s site with no notification to instructors or universities, including paying customers. (See the correction below for more detail on “paying customers.”)
I do not believe the content was editable on either site. I’m certain it’s not currently editable on Course Hero’s site and I’m fairly confident that it was not editable in Candela on Lumen’s site.
Corrections: A source informed me that I was mistaken on two fronts. First, Lumen did charge a low price for the version of Candela that integrated with LMSs. I do not believe it was a money maker for Lumen, and I’m confident that the free, non-integrated version got significant traffic. While this doesn’t change the overall business implications, I got the facts wrong. Unfortunately, this also means that some of those affected by the switch were paying customers.
Second, Candela did support editing.
Implications
First, the business logic for both companies is clear. Hosting OER content for free is a public service that has non-zero cost, particularly if it is successful at attracting significant volume. Hosting a catalog of free online textbooks simply costs less and buys more for a company like Course Hero than it does for a company like Lumen. I make not value judgment here, one way or the other. These are simple economics.
By I suspect—and this is pure speculation on my part—that Course Hero did pay Lumen, at least to cover the costs of supporting the content transfer. I don’t know the details of any potential transaction but I don’t see any ethical red flags with it, at least as a stand-alone issue. I’d have to see somesign of some other, ethically problematic quid pro quo which is not evident in the reporting.
Second, these details (assuming their accuracy) tend to cut against some of the commentary in the article. For example, while I respect Bryan Alexander, I don’t think the facts support the speculation that “Lumen handing over the content to Course Hero seems like it could plausibly be them agreeing with those who think there’s no good business case for OER.”
Likewise, Steel Wagstaff from Pressbooks, in my opinion, missed the mark on a couple of points. The first was when he suggested that “Although the content has an open license, it’s conceivable that it will be harder for technical reasons to edit and make copies of the content on Course Hero’s platform, depending on what Course Hero is doing to host the content.” My understanding is that it is neither easier nor harder. Neither platform supports native editing. To change the content, one would have to copy and paste the content in a platform that does support editing such as Google Docs or Pressbooks.
Correction: Steel was correct. Candela, unlike Waymaker, did allow for editing. (I’m not sure if it was available in the free version of the product; see the correction above.)
Wagstaff is also paraphrased in the article as saying, “If your main interest in OER is to adopt a book for free, then the hosting change isn’t such a big deal, except perhaps that people “feel scuzzy” about Course Hero being the ones hosting the content[.]”
This is where things get messy. And sometimes nasty.
Course Hero’s reputation and some circumscribed commentary
“Scuzzy” vastly understates the breadth and depth of feeling currently swirling around Course Hero. And that concern is likely the reason this transfer of free content between two companies generated enough noise to get the attention of EdSurge.
Before I get into further commentary, I want to state my priors here. I know the leadership of both companies. In Lumen’s case, I’ve known CEO Kim Thanos and her co-founder, David Wiley, for many years. I consider them to be friends. I trust their values even when I don’t agree with particular decisions. I know Course Hero CEO Andrew Grauer and his leadership team less well. But I have had a number of interactions with them, spent some time vetting them, and came away feeling good about the humans in charge. My best read on them, given the caveat that I don’t know them terribly well, is that they want to be constructive partners in supporting education. I have worked with both companies in the past (though not recently) and have no qualms or regrets about having done so. With that in mind, here’s my take on the story:
Currently, Course Hero is widely and often vehemently viewed as a bad actor that helps students cheat within a significant slice of university educators and administrators. It’s not particularly easy to get your website blocked by a major public university and yet I personally know of a handful that have blocked Course Hero. EdSurge likewise states that “some campus networks have actually blocked Course Hero’s core service domains”.
This state of affairs, combined with the companies’ mutual decision to roll out the change quietly, had two serious implications. First, universities that have encouraged students to use free OER hosted by Lumen suddenly started hearing from their students that they cannot access these resources. Second, students could not access those resources because the content has been quietly moved to a web site that important university stakeholders decided was harmful enough that they blocked it from university networks. They believe that Course Hero undermines their policies and contributes to students’ failure to learn. To add insult to injury, I heard from folks at several of these universities that they first heard about the switch from panicked students who couldn’t access their course materials after the term had started rather than from Lumen or Course Hero beforehand. These leaders feel blindsided.
Both companies appear to have been taken by surprise at the level of backlash. In fact, Course Hero’s Vice President of Academics Sean Michael Morris is quoted in the EdSurge article as saying, “Part of this news cycle around this caught us off guard.”
Morris’s reaction is shockingly tone-deaf from beginning to end. First of all, referring to this reaction as a “news cycle” reflects a fundamental misunderstanding of the seriousness of the brand problem Course Hero has. He actually jokes about universities unblocking their site as a solution to the problem. And he never once addresses the underlying issue of trust that caused the site to be blocked in the first place.
This has been my deepest concern with Course Hero, which has only grown with time. Although I still believe they are not intentional bad actors, they have the instincts of a consumer company catering to students and show little understanding of universities. And while they have made earnest efforts to reach out to and understand their critics—I have participated in some of those conversations—they demonstrate at times like these that they remain dangerously naive about the stakeholders inside the institutions they want to work with.
They have made good inroads with adjunct faculty. But incidents like this one, and their reaction to it, suggest that they have made little progress in understanding, much less winning over, the kinds of stakeholders who can block on-campus access to their site or even initiate legal action. And to be clear, I have heard more than one senior campus leader intimate that such actions were being contemplated.
Lumen, while it has been quieter, also seems to have been caught flat-footed. I am hearing from multiple long-time customers who have been put in a very difficult position by their lack of advance communication. Lumen needs its advocates and can’t afford to burn these bridges.
This was entirely avoidable
The two companies missed a chance to turn a potential blow-back into a trust-winning opportunity. They could have done something like the following:
Announced in advance that the two companies are working on a sustainability strategy to keep the OER accessible for free to students
Selectively sought input from Candela-using educators and campuses about the best way to do this
Created a separate site with a separate URL, hosted by Course Hero, that would have bought them more goodwill at the cost of some easy customer conversion
I don’t want to pretend that everything would have been rosy had they taken this path. The companies each have critics that would have come after them no matter what they did. So I understand the impulse to do this quietly.
But it obviously didn’t save them from the slings and arrows. Instead, it alienated Lumen’s allies while reinforcing rather than softening Course Hero’s reputation of being an enemy of university folk.
To sum up my own reading of the events in question, this story does not portend doom and gloom for OER. Nor does it provide convincing evidence of nefarious profiteering by Lumen. This is the story of two companies, each driven by enlightened self-interest, that screwed up a mutual effort to preserve access to free educational resources with a gob-smacking level of tone-deafness.
This story also tells us something about how OER does and doesn’t work in supporting different sorts of business models (e.g., Lumen’s and Course Hero’s, which are starkly different).
These companies obviously have some thinking to do and need to do a far better job of staunching the bleeding.
In the meantime, the academic community needs to get far more sophisticated in their thinking about how sustainability works when OER gets used as infrastructure in a for-profit EdTech world. Keep in mind that another option Lumen had at its disposal was to simply turn Candela off. That would have benefitted nobody.
I’m not going to pretend I have an answer or even pretend that I believe there is a one-size-fits-all answer. But we need better answers about sustainability at scale, balancing cost against quality, and harnessing the theoretical affordance of editability into something that actually serves students. I believe those answers will come, in part, from studying how different EdTech companies make their money and how the business mechanics interact with OER. After all, the foundation of OER is a copyright license. It may hack the private property system but it does not live outside of that system. We don’t have to look for evil motives to understand why Lumen and Course Hero thought moving stewardship of Candela might be good for everyone. It’s actually pretty straightforward.
So how do we cultivate companies whose business interests benefit from promoting affordable, quality education? And where does OER fit into that equation?